 陈辅元
 Cursor
+26
@@ -0,0 +1,26 @@
|
||||
# Python
|
||||
__pycache__/
|
||||
*.py[cod]
|
||||
*.egg-info/
|
||||
.pytest_cache/
|
||||
.venv/
|
||||
venv/
|
||||
.env
|
||||
.env.*
|
||||
|
||||
# Runtime / generated
|
||||
storage/uploads/
|
||||
storage/results/
|
||||
storage/assets/
|
||||
output/
|
||||
|
||||
# IDE / local agent
|
||||
.idea/
|
||||
.vscode/
|
||||
.claude/
|
||||
.learnings/
|
||||
|
||||
# OS
|
||||
Thumbs.db
|
||||
Desktop.ini
|
||||
.DS_Store
|
||||
@@ -0,0 +1,48 @@
|
||||
# AGENTS.md
|
||||
|
||||
This file provides guidance to Codex (Codex.ai/code) when working with code in this repository.
|
||||
|
||||
## Project status
|
||||
|
||||
This is a **greenfield project** — as of 2026-07-06 there is no code, no build system, and no git history yet. The only artifact is the requirements document `docx/自研搭建AI助手知识库.pdf` ("Self-built AI Assistant Knowledge Base"). Treat this file as the source of truth for requirements until code supersedes it.
|
||||
|
||||
## What this project is
|
||||
|
||||
A self-hosted **AI assistant knowledge base demo** (RAG system) whose primary goal is **high-quality document chunking/slicing**; recall quality is secondary. The driving problem: an existing knowledge-base feature ("AFE") slices poorly — it drops images and tables from word/pdf/excel documents, and its rules forcibly split a single passage across separate chunks. This project rebuilds the ingestion/slicing pipeline and exposes a demo UI to inspect the results.
|
||||
|
||||
## Requirements (from the PDF)
|
||||
|
||||
### Demo capabilities
|
||||
- Upload files and **view the chunking/slicing result**.
|
||||
- **Test recall** and inspect recall input parameters and return parameters.
|
||||
|
||||
### Supported document types
|
||||
- **Office docs:** pdf, doc, docx, ppt, pptx, wps, ppsx
|
||||
- **Tabular / structured:** xlsx, xls, csv, md, txt, html, json, xml, log
|
||||
- **Images:** jpg, png, jpeg, bmp, gif
|
||||
|
||||
### Slicing rules
|
||||
- **Table documents:** default split **or** split-by-row.
|
||||
- **Other documents:** default split **or** universal-identifier split.
|
||||
- **Tables inside a slice:** rendered as **Markdown**.
|
||||
|
||||
### Expected effects — basic
|
||||
1. Images stay in their original position in the rendered text — not lost or relocated to another chunk.
|
||||
2. Table content is extracted correctly and converted to Markdown.
|
||||
3. Slicing is structurally aware: for Word, all content under the same heading stays within one chunk.
|
||||
|
||||
### Expected effects — advanced
|
||||
1. Images/graphics are extracted as images **and** their text is OCR-recognized and converted to text.
|
||||
2. PDF text laid out in horizontal columns is read back in the correct reading order (not jumbled).
|
||||
|
||||
## Environment notes
|
||||
|
||||
- **OS:** Windows 11. Shell is **bash** (Git Bash / MSYS2) — use Unix syntax (`/dev/null`, forward slashes), not PowerShell/CMD.
|
||||
- **Python:** available at `/d/conda/python` (a conda environment). Relevant libraries **already installed** and useful for this project: `PyMuPDF` (fitz), `pdfplumber`, `pdfminer.six`, `pypdf`/`PyPDF2`, `pypdfium2`, `pikepdf`, `pdf2image`.
|
||||
- **Reading the requirements PDF:** the file is image-heavy. `pdftotext -enc UTF-8` (at `/mingw64/bin/pdftotext`) extracts the little body text present but **misses the embedded diagrams** that the PDF references with "如下图" ("as shown below"). `pdftoppm` (image rendering) is **not** installed, so to view the diagrams use PyMuPDF from Python instead, e.g. `fitz.open(path)[page].get_pixmap()`.
|
||||
- **Not a git repository.** Do not assume `git` workflows; initialize one only if asked.
|
||||
|
||||
## Working in this repo
|
||||
|
||||
- Before adding a chunking/slicing behavior, re-check the PDF's "期望效果" section above — the heading-awareness rule for Word and the image-position-preservation rule are the two most likely to be violated by naive splitters.
|
||||
- The folder is named "RAG-cut" — chunking quality is the headline deliverable, recall is secondary. Prioritize ingestion/parsing fidelity over retrieval sophistication.
|
||||
@@ -0,0 +1,48 @@
|
||||
# CLAUDE.md
|
||||
|
||||
This file provides guidance to Claude Code (claude.ai/code) when working with code in this repository.
|
||||
|
||||
## Project status
|
||||
|
||||
This is a **greenfield project** — as of 2026-07-06 there is no code, no build system, and no git history yet. The only artifact is the requirements document `docx/自研搭建AI助手知识库.pdf` ("Self-built AI Assistant Knowledge Base"). Treat this file as the source of truth for requirements until code supersedes it.
|
||||
|
||||
## What this project is
|
||||
|
||||
A self-hosted **AI assistant knowledge base demo** (RAG system) whose primary goal is **high-quality document chunking/slicing**; recall quality is secondary. The driving problem: an existing knowledge-base feature ("AFE") slices poorly — it drops images and tables from word/pdf/excel documents, and its rules forcibly split a single passage across separate chunks. This project rebuilds the ingestion/slicing pipeline and exposes a demo UI to inspect the results.
|
||||
|
||||
## Requirements (from the PDF)
|
||||
|
||||
### Demo capabilities
|
||||
- Upload files and **view the chunking/slicing result**.
|
||||
- **Test recall** and inspect recall input parameters and return parameters.
|
||||
|
||||
### Supported document types
|
||||
- **Office docs:** pdf, doc, docx, ppt, pptx, wps, ppsx
|
||||
- **Tabular / structured:** xlsx, xls, csv, md, txt, html, json, xml, log
|
||||
- **Images:** jpg, png, jpeg, bmp, gif
|
||||
|
||||
### Slicing rules
|
||||
- **Table documents:** default split **or** split-by-row.
|
||||
- **Other documents:** default split **or** universal-identifier split.
|
||||
- **Tables inside a slice:** rendered as **Markdown**.
|
||||
|
||||
### Expected effects — basic
|
||||
1. Images stay in their original position in the rendered text — not lost or relocated to another chunk.
|
||||
2. Table content is extracted correctly and converted to Markdown.
|
||||
3. Slicing is structurally aware: for Word, all content under the same heading stays within one chunk.
|
||||
|
||||
### Expected effects — advanced
|
||||
1. Images/graphics are extracted as images **and** their text is OCR-recognized and converted to text.
|
||||
2. PDF text laid out in horizontal columns is read back in the correct reading order (not jumbled).
|
||||
|
||||
## Environment notes
|
||||
|
||||
- **OS:** Windows 11. Shell is **bash** (Git Bash / MSYS2) — use Unix syntax (`/dev/null`, forward slashes), not PowerShell/CMD.
|
||||
- **Python:** available at `/d/conda/python` (a conda environment). Relevant libraries **already installed** and useful for this project: `PyMuPDF` (fitz), `pdfplumber`, `pdfminer.six`, `pypdf`/`PyPDF2`, `pypdfium2`, `pikepdf`, `pdf2image`.
|
||||
- **Reading the requirements PDF:** the file is image-heavy. `pdftotext -enc UTF-8` (at `/mingw64/bin/pdftotext`) extracts the little body text present but **misses the embedded diagrams** that the PDF references with "如下图" ("as shown below"). `pdftoppm` (image rendering) is **not** installed, so to view the diagrams use PyMuPDF from Python instead, e.g. `fitz.open(path)[page].get_pixmap()`.
|
||||
- **Not a git repository.** Do not assume `git` workflows; initialize one only if asked.
|
||||
|
||||
## Working in this repo
|
||||
|
||||
- Before adding a chunking/slicing behavior, re-check the PDF's "期望效果" section above — the heading-awareness rule for Word and the image-position-preservation rule are the two most likely to be violated by naive splitters.
|
||||
- The folder is named "RAG-cut" — chunking quality is the headline deliverable, recall is secondary. Prioritize ingestion/parsing fidelity over retrieval sophistication.
|
||||
@@ -0,0 +1,31 @@
|
||||
# Impact Analysis Report — 目录不解析、不切片
|
||||
|
||||
## 1. 改动概览
|
||||
|
||||
- **背景与目标**:所有文件跳过文档目录(目录 / Contents / TOC),不进入解析结果与切片。
|
||||
- **涉及模块**:`noise_filter.py`、`pipeline.py`、`pdf_semantic.py`、`mineru_adapter.py`、相关测试、`README.md`
|
||||
- **改动类型**:功能策略 / 缺陷修复(噪声过滤增强)
|
||||
|
||||
## 2. 方法级改动分析
|
||||
|
||||
| 位置 | 差异 |
|
||||
| --- | --- |
|
||||
| `is_toc_title_text` / `is_toc_entry_line` / `is_toc_noise_text` | 统一识别目录标题与带页码/引导线条目 |
|
||||
| `filter_toc_blocks` | 删除目录页/目录区;保留无页码的正文内清单(如形態指標) |
|
||||
| `filter_noise_blocks` | 串联 TOC 过滤 |
|
||||
| `pipeline.chunk_document` | 全格式解析后强制 `filter_toc_blocks` |
|
||||
| MinerU `_SKIP_MINERU_TYPES` | 增加 `toc` / `contents` 等类型 |
|
||||
|
||||
## 3. 调用方与影响范围
|
||||
|
||||
- PDF/Office(MinerU / PyMuPDF)及 md/txt 等所有走 `chunk_document` 的格式
|
||||
- **破坏性变更:否**(目录内容不再出现在切片中,属预期)
|
||||
|
||||
## 4. 风险与回滚
|
||||
|
||||
- **风险级别**:低~中(极少数非目录但带引导线+页码的行可能被误删)
|
||||
- **回滚方式是否简单:是**
|
||||
|
||||
## 5. 验证与测试
|
||||
|
||||
- 新增/更新噪声与语义切分单测;请对含目录的样本重新切分确认
|
||||
@@ -0,0 +1,507 @@
|
||||
# RAG-cut
|
||||
|
||||
自研 AI 助手知识库 Demo —— 以**高质量文档切片**为核心,召回为次要目标。
|
||||
|
||||
重建文档 ingestion / 切片流水线,解决现有 AFE 知识库的两类问题:
|
||||
|
||||
1. **文档解析不足**:Word / PDF / Excel 中的图片、表格无法有效提取
|
||||
2. **切片规则不佳**:同一逻辑段落被硬切到不同 chunk,图片丢失或错位
|
||||
|
||||
需求来源:`[docx/自研搭建AI助手知识库.pdf](docx/自研搭建AI助手知识库.pdf)`
|
||||
|
||||
---
|
||||
|
||||
## 功能概览
|
||||
|
||||
|
||||
| 能力 | 说明 |
|
||||
| --------- | --------------------------------------------------------------------------------------------- |
|
||||
| 多格式解析 | pdf / doc / docx / ppt / pptx / ppsx / xlsx / csv / md / txt / html / json / xml / log / 常见图片 |
|
||||
| PDF 双引擎 | MinerU(优先)+ PyMuPDF 回退;统一噪声过滤 |
|
||||
| 自动切分策略 | 前端可选自动,或手动指定 mode |
|
||||
| 语义切分 | PDF / Word 走 `heading_layout_multimodal`;超长章节仅按长度/子标题拆分(不再产父片) |
|
||||
| 父子标识符 | 独立模式 `parent_child`:父/子标识符双层切分,子片检索、父片上下文 |
|
||||
| 表格切分 | 自动识别表头 / 说明行;Q&A 表按行 1 片;普通表按行数自适应 |
|
||||
| Demo UI | 原文预览 · 切片列表 · Markdown 预览 · **历史切片回看** · BM25 召回测试 |
|
||||
| CLI / API | `scripts/chunk_cli.py` · FastAPI `/api/chunk` · `/api/results` · `/api/recall` |
|
||||
|
||||
|
||||
未支持:`.wps`(可先转为 docx/pdf)。独立图片暂不做 OCR。
|
||||
|
||||
---
|
||||
|
||||
|
||||
|
||||
## 技术架构
|
||||
|
||||
```
|
||||
上传文件
|
||||
│
|
||||
▼
|
||||
格式路由 (registry)
|
||||
│
|
||||
▼
|
||||
解析器 (parsers) ──► 有序 Block 流(heading / paragraph / table / image …)
|
||||
│ PDF:MinerU(优先)或 PyMuPDF → 噪声过滤 → 跨页表合并
|
||||
▼
|
||||
版面增强 (layout_meta) ──► 标题层级、图片/表格上下文、order_index
|
||||
│
|
||||
▼
|
||||
切分策略 (split_policy / pdf_strategy)
|
||||
│
|
||||
▼
|
||||
切分器 (splitters) ──► Block 分组(含父子切片关联)
|
||||
│
|
||||
▼
|
||||
渲染器 (renderer) ──► Markdown Chunk + embedding_text / retrieval 标记
|
||||
```
|
||||
|
||||
**核心设计**:先解析为不可拆分的 Block,再按结构切分。`image` / `table` 为原子块,不会被拆到不同 chunk。
|
||||
|
||||
### 目录结构
|
||||
|
||||
```
|
||||
RAG-cut/
|
||||
├── backend/
|
||||
│ ├── rag_cut/
|
||||
│ │ ├── models.py / pipeline.py / renderer.py / layout_meta.py
|
||||
│ │ ├── split_policy.py / retrieval.py
|
||||
│ │ ├── parsers/ # word / ppt / pdf / xlsx / text / image + MinerU
|
||||
│ │ │ └── pdf/ # PyMuPDF 流水线、噪声过滤、跨页表合并
|
||||
│ │ └── splitters/ # default / heading / pdf_semantic / by_row / delimiter
|
||||
│ ├── api/main.py # FastAPI:/api/chunk · /api/results · /api/recall · 静态前端
|
||||
│ ├── tests/
|
||||
│ └── run.py
|
||||
├── frontend/ # Demo(index.html + css + js)
|
||||
├── scripts/ # chunk_cli · run_all_samples
|
||||
├── storage/ # uploads / assets / results(运行时生成)
|
||||
├── docx/ # 需求 PDF、MinerU 说明
|
||||
└── requirements.txt
|
||||
```
|
||||
|
||||
---
|
||||
|
||||
|
||||
|
||||
## 快速开始
|
||||
|
||||
```bash
|
||||
pip install -r requirements.txt
|
||||
|
||||
cd backend
|
||||
python run.py
|
||||
```
|
||||
|
||||
浏览器打开:**[http://127.0.0.1:8000](http://127.0.0.1:8000)**
|
||||
|
||||
前后端分离开发时,另开终端:
|
||||
|
||||
```bash
|
||||
cd frontend
|
||||
python run.py # http://127.0.0.1:5173 ,API 需自行指向 :8000
|
||||
```
|
||||
|
||||
可选参数:`--host 0.0.0.0 --port 8000 --no-reload`(后端)· `--port 5173`(前端)
|
||||
|
||||
### 环境变量(PDF)
|
||||
|
||||
|
||||
| 变量 | 默认 | 说明 |
|
||||
| -------------------- | ------ | ------------------------------------------------------ |
|
||||
| `RAG_CUT_PDF_ENGINE` | `auto` | `auto` 优先 MinerU,失败回退 PyMuPDF;可强制 `mineru` / `pymupdf` |
|
||||
| `RAG_CUT_MINERU_CMD` | — | MinerU 可执行文件路径(不在 PATH 时) |
|
||||
| `RAG_CUT_MINERU_API_URL` | — | 复用已启动的 MinerU API,避免每次切分重复加载模型 |
|
||||
| `RAG_CUT_MINERU_TIMEOUT` | `540` | 单次 MinerU 解析超时秒数;超时后会清理其临时服务和子进程 |
|
||||
| `RAG_CUT_MINERU_OCR` | `1` | MinerU 图片无 OCR 时用 Tesseract 回填;`0` 关闭以加快切分 |
|
||||
|
||||
|
||||
详见 `[docx/mineru-integration.md](docx/mineru-integration.md)`。
|
||||
|
||||
### 依赖与运行环境
|
||||
|
||||
|
||||
| 类别 | 选型 |
|
||||
| ------------ | -------------------------------------------------------------- |
|
||||
| Python | 3.12+ |
|
||||
| Web | FastAPI + Uvicorn |
|
||||
| PDF | MinerU(`requirements.txt` 已含)/ PyMuPDF + pdfplumber |
|
||||
| Excel | openpyxl |
|
||||
| Office 转 PDF | 本机 **LibreOffice** 或 **Microsoft Word/PowerPoint**(doc/ppt 必需) |
|
||||
| 召回 | 内置 BM25 词法评分(无向量库) |
|
||||
|
||||
|
||||
---
|
||||
|
||||
|
||||
|
||||
## 各格式处理
|
||||
|
||||
所有格式统一:**解析 → Block → 切分 → Markdown Chunk**。
|
||||
|
||||
|
||||
| 扩展名 | 解析器 | 要点 | 默认切分 |
|
||||
| ---------------------- | ------------------- | ------------------------------- | ------------------------------ |
|
||||
| `.pdf` | `PdfParser` | MinerU / PyMuPDF → 噪声过滤 → 跨页表合并 | 语义切分(`max=2600`) |
|
||||
| `.doc` `.docx` | `WordParser` | 转 PDF 后复用 PDF 流水线 | 同上 |
|
||||
| `.ppt` `.pptx` `.ppsx` | `PptParser` | 转 PDF;页码 ≈ 幻灯片序号 | `default`(`max=2600`) |
|
||||
| `.xlsx` `.xls` `.csv` | `SpreadsheetParser` | 自动检测 preamble / 表头 / 数据起始行 | `by_row`(Q&A 表 1 行/片,否则按行数自适应) |
|
||||
| `.md` `.html` | `TextParser` | 按标题 / 段落拆块 | `default`(`max=1800`) |
|
||||
| `.json` | `TextParser` | 顶层 key / 数组元素 → `code` 块 | `default` |
|
||||
| `.txt` `.xml` `.log` | `TextParser` | 按空行分段(不解析 XML 结构) | `default` |
|
||||
| 图片 | `ImageParser` | 整图 1 个 Block | 整图 1 片 |
|
||||
|
||||
|
||||
|
||||
|
||||
### 统一产出
|
||||
|
||||
|
||||
| 项目 | 说明 |
|
||||
| -------- | ---------------------------------------------------------------------------------------------- |
|
||||
| Block 类型 | `heading` / `paragraph` / `table` / `image` / `list` / `code` |
|
||||
| Chunk | Markdown + `meta`(`heading` / `pages` / `embedding_text` / `retrieval` / 可选 `parent_chunk_id`) |
|
||||
| 图片 | `storage/assets/{doc_id}/`;JSON 内为 `assets/{doc_id}/…` |
|
||||
| 结果缓存 | `storage/results/{doc_id}.json`(供召回) |
|
||||
| 中间产物 | `_conversion/`(Office→PDF)、`_mineru/`(MinerU 输出) |
|
||||
|
||||
|
||||
|
||||
|
||||
### Word / PPT 转 PDF
|
||||
|
||||
优先 LibreOffice(`soffice --headless`),Windows 可回退 Office COM。转换失败时 API 返回 500 并附带各后端错误信息。
|
||||
|
||||
### Excel / CSV 布局检测
|
||||
|
||||
`detect_spreadsheet_layout` 会识别常见模板(如第 1 行字段说明、第 2 行列表头、第 3 行起数据),跳过 preamble;Q&A 评测表(列名含 query/answer 等)自动 `rows_per_chunk=1`。
|
||||
|
||||
> `.xls` 依赖 openpyxl,老二进制格式可能失败,建议先转 xlsx。
|
||||
|
||||
---
|
||||
|
||||
|
||||
|
||||
## PDF 切割方法
|
||||
|
||||
`.pdf` / `.doc` / `.docx` 在 `mode=default` 时走专用语义切分器
|
||||
`splitters/pdf_semantic.py`(策略名:`heading_layout_multimodal`)。
|
||||
Word 先转 PDF,再与 PDF 共用同一套规则。默认 `max_chunk_size=2600`、`overlap=120`。
|
||||
|
||||
### 流水线
|
||||
|
||||
```
|
||||
PDF/Word
|
||||
│
|
||||
├─ 解析:MinerU(优先)或 PyMuPDF → Block 流
|
||||
├─ 噪声过滤:页眉/页脚/页码、**整段文档目录**、装饰小图
|
||||
├─ 跨页表格合并
|
||||
├─ 版面增强:标题层级、图片/表格上下文、order_index
|
||||
├─ pdf_strategy:打标签(操作手册 vs 年报,见下)
|
||||
└─ heading_layout_multimodal 切分 → Chunk
|
||||
```
|
||||
|
||||
### 核心规则:`heading_layout_multimodal`
|
||||
|
||||
目标:同一逻辑小节(标题 + 正文 + 同节截图/表格)尽量落在同一 chunk,避免把步骤截图和说明文字拆开。
|
||||
|
||||
| 步骤 | 行为 |
|
||||
|------|------|
|
||||
| 1. 再过滤噪声 | 跳过页码、running header、**文档目录(目录/Contents 及条目)**、过小装饰图 |
|
||||
|
||||
| 2. 识别标题 | 解析器已标的 `heading`,或正则/字号启发式补识别 |
|
||||
| 3. 维护标题路径 | 用标题栈记录章节层级,如 `1 Getting Started → A. Log in` |
|
||||
| 4. 按标题开新片 | 遇到同级或更高级标题时 flush 当前组,开新 chunk |
|
||||
| 5. 图文同节 | 正文、image、table 跟在当前标题路径下;绑定前后文到 `meta` |
|
||||
| 6. 超长二次切 | 超过 `max_chunk_size` 时按子标题/内容标记/长度拆成多片;**不单独保留父片** |
|
||||
|
||||
**可识别的标题形态**(示例):
|
||||
|
||||
- 编号:`1.` / `1.2.3` / `A.` / `Chapter 2`(操作步骤 `Step N …` 作为正文保留,不单独开章)
|
||||
- 中文章节:`一、` / `(一)` 等
|
||||
- 字号显著大于正文的短文本(PyMuPDF 路径)
|
||||
|
||||
封面 Logo 等无语义组会标 `retrieval=false`,不进召回候选。
|
||||
|
||||
### 父子标识符切分(`mode=parent_child`)
|
||||
|
||||
适合「细粒度检索、粗粒度召回」:子片用于 BM25 检索,命中后通过 `parent_chunk_id` 关联父片上下文。
|
||||
|
||||
> 默认切分**不会**再因超长章节自动产出父片+子片;需要父子结构时请显式选择本模式。
|
||||
|
||||
流程:
|
||||
1. 按 **父级标识符**(`parent_delimiter`)切开,得到父片;超过父级最大长度时再按长度二次切
|
||||
2. 每个父片再按 **子级标识符**(`child_delimiter`,可选)切开,得到子片;超过子级最大长度时再按长度二次切
|
||||
3. 父片:`is_section_parent=true`,`retrieval=false`
|
||||
4. 子片:`is_sub_chunk=true`,`retrieval=true`,`parent_chunk_id` 指向父片
|
||||
|
||||
参数约束:
|
||||
|
||||
| 参数 | 说明 |
|
||||
|------|------|
|
||||
| `parent_delimiter` | 必填;父级切开标记(不会写入切片正文) |
|
||||
| `child_delimiter` | 可选;缺省则仅按子级最大长度拆子片 |
|
||||
| `max_chunk_size` | 父级最大长度 |
|
||||
| `child_max_size` | 子级最大长度,且 ≤ 父级、硬上限 1500 |
|
||||
| `overlap` | 超长二次切分时的重叠 |
|
||||
|
||||
Demo / CLI / API 均可显式选择此模式。
|
||||
### 文档类型标签:`pdf_strategy`
|
||||
|
||||
`splitters/pdf_strategy.py` 根据文件名与正文特征打标签,写入
|
||||
`split_config.pdf_chunk_strategy`(Demo 自动策略面板会显示):
|
||||
|
||||
| 标签 | 典型特征 | 说明 |
|
||||
|------|----------|------|
|
||||
| `pdf_feature_step_screenshot` | 步骤标题多、「点击/输入/选择」等操作词多、截图密度高 | 操作手册型 |
|
||||
| `pdf_outline_report` | 「年报/财务报表/董事会」等词多,或文件名含 annual/report/年报 | 年报/报告型 |
|
||||
|
||||
> 当前两类**切分算法相同**(都走 `heading_layout_multimodal`);标签用于结果标注,并为后续分叉策略预留。
|
||||
|
||||
### 其他切分模式(PDF 也可用)
|
||||
|
||||
| 模式 | 何时用 | 行为 |
|
||||
|------|--------|------|
|
||||
| `default` | Demo / 自动策略(推荐) | 上文语义切分 |
|
||||
| `delimiter` | CLI/API/前端显式指定 | 按自定义标识符切,再按长度二次切 |
|
||||
| `parent_child` | CLI/API/前端显式指定 | 父子标识符切分(检索用子片、父片作上下文) |
|
||||
| `by_row` | 一般不用于 PDF | 面向表格文档 |
|
||||
|
||||
相关代码:`pdf_semantic.py` · `pdf_strategy.py` · `parsers/pdf/noise_filter.py` · `pipeline.py`。
|
||||
|
||||
---
|
||||
|
||||
## 切分策略(全格式)
|
||||
|
||||
后端共 **4** 种切分模式(`SplitMode`):`default` / `delimiter` / `parent_child` / `by_row`。
|
||||
前端「自动」(`auto`) 不是独立模式:不传 `mode` 时由 `split_policy.choose_split_config` 按扩展名与表结构选型。
|
||||
|
||||
API **不会按扩展名拦截 mode**——凡解析器支持的格式均可手动指定任意模式;下表区分设计意图与有效行为。
|
||||
|
||||
### 可解析格式(21 种)
|
||||
|
||||
| 类别 | 扩展名 |
|
||||
| ---- | ------ |
|
||||
| Office | `.pdf` `.doc` `.docx` `.ppt` `.pptx` `.ppsx` |
|
||||
| 表格 | `.xlsx` `.xls` `.csv` |
|
||||
| 文本 | `.md` `.txt` `.html` `.htm` `.json` `.xml` `.log` |
|
||||
| 图片 | `.jpg` `.jpeg` `.png` `.bmp` `.gif` |
|
||||
|
||||
> 需求中的 `.wps` 尚未接入解析器。
|
||||
|
||||
### 四种模式与文档格式
|
||||
|
||||
| 模式 | 适用(设计意图) | 实际覆盖的格式 | 行为 |
|
||||
| ---- | ---------------- | -------------- | ---- |
|
||||
| `default` | 非表格 | 除表格类外全部;表格也可手动指定 | 结构/标题感知切分;`.pdf`/`.doc`/`.docx` 走语义切分(`heading_layout_multimodal`);单章超长时按子标题或长度拆开(**不产父片**) |
|
||||
| `delimiter` | 非表格(正文含可匹配标识符) | 全部可解析格式 | 按自定义标识符(如 `###`)切开;超长片段再按 `max_chunk_size` + `overlap`;无标识符时效果差 |
|
||||
| `parent_child` | 非表格(层级标识符) | 全部可解析格式 | 先按父标识符切父片,再按子标识符切子片;检索用子片,父片作上下文;典型如 `.md`/文本 |
|
||||
| `by_row` | 表格 | **有效**:`.xlsx` `.xls` `.csv`,或解析后含带 `rows` 的 TABLE block | 每片 = 表头 + N 行 Markdown;无表格行数据时退化为整篇一片;一般不用于 PDF/Word |
|
||||
|
||||
### 自动策略(不传 mode)
|
||||
|
||||
| 文档 | 自动选的模式 |
|
||||
| ---- | ------------ |
|
||||
| `.xlsx` `.xls` `.csv`,或整篇就一张表(含 `rows`) | `by_row` |
|
||||
| `.pdf` `.ppt` `.pptx` `.ppsx` | `default` |
|
||||
| 图片类 | `default` |
|
||||
| 文本类(`.md` `.txt` `.html` `.htm` `.json` `.xml` `.log`) | `default` |
|
||||
| `.doc` `.docx` 等其余 | `default` |
|
||||
|
||||
**一句话**:`by_row` 专吃表格;另外三种面向正文结构,其中 `default` 对 PDF/Word 有专用路径,`delimiter` / `parent_child` 对有标识符的文本最有用,但格式本身不限制。
|
||||
|
||||
|
||||
### `default` 决策树
|
||||
|
||||
```
|
||||
.pdf / .doc / .docx
|
||||
└─ 见上方「PDF 切割方法」(heading_layout_multimodal)
|
||||
单 table 且含 rows
|
||||
└─ 自动 by_row
|
||||
其他 + 足够标题
|
||||
└─ 标题大纲切;若某章超过 max_chunk_size
|
||||
→ 优先按子标题 / 内容标记拆分
|
||||
→ 否则按长度拆分(不保留整章父片)
|
||||
有 page 元数据、标题不足
|
||||
└─ 按页;单页超限再按长度
|
||||
否则
|
||||
└─ 按 max_chunk_size 打包;image/table 不拆
|
||||
```
|
||||
|
||||
`meta.retrieval = false` 的切片(如封面 Logo,或 `parent_child` 模式的父片)不参与召回。
|
||||
|
||||
### SplitConfig
|
||||
|
||||
|
||||
| 参数 | 默认 | 说明 |
|
||||
| ------------------------------------- | --------- | ------------------------------ |
|
||||
| `mode` | `default` | `default` / `delimiter` / `parent_child` / `by_row` |
|
||||
| `delimiter` | — | `delimiter` 模式必填 |
|
||||
| `parent_delimiter` / `child_delimiter` | — | `parent_child` 模式:父标识符必填,子标识符可选 |
|
||||
| `max_chunk_size` | 1500 | 单 chunk 上限(父级长度;自动策略常覆盖为 1800–2600) |
|
||||
| `child_max_size` | 512 | `parent_child` 子级最大长度(≤ 父级,且 ≤ 1500) |
|
||||
| `overlap` | 150 | 超长二次切分重叠 |
|
||||
| `header_row_start` / `header_row_end` | 1 | 表头行(1-based) |
|
||||
| `start_row` | 2 | 数据起始行 |
|
||||
| `rows_per_chunk` | 1 | 每片数据行数 |
|
||||
|
||||
|
||||
---
|
||||
|
||||
|
||||
|
||||
## Demo 前端
|
||||
|
||||
三栏工作区:**原文** · **切片列表** · **切片预览**;左侧可选手动切分模式,或保持「自动」由系统选型。
|
||||
|
||||
|
||||
| 区域 | 说明 |
|
||||
| ------ | ---------------------------------------- |
|
||||
| 上传 | 拖拽 / 选择文件 |
|
||||
| 切分模式 | 自动 / 默认(结构感知)/ 通用标识符 / **父子标识符** / 按行;手动模式可调对应参数 |
|
||||
| 策略面板 | 切分后回显 mode / max_size / overlap / PDF 策略 |
|
||||
| 原文 | PDF iframe / docx(mammoth)/ 文本 / 图片 |
|
||||
| 切片列表 | 类型标签、父子切片标记、字符数 |
|
||||
| 召回测试 | query + top_k;展示得分与命中切片 |
|
||||
| API 面板 | 可折叠请求/响应 JSON |
|
||||
|
||||
|
||||
---
|
||||
|
||||
|
||||
|
||||
## CLI / API
|
||||
|
||||
|
||||
|
||||
### CLI
|
||||
|
||||
```bash
|
||||
# 显式传 SplitConfig(不会走前端那种「全自动」空配置)
|
||||
python scripts/chunk_cli.py "path/to/file.pdf" --preview 3
|
||||
python scripts/chunk_cli.py "path/to/file.xlsx" --mode by_row --rows-per-chunk 5 -o storage/result.json
|
||||
python scripts/chunk_cli.py "readme.md" --mode delimiter --delimiter "##"
|
||||
python scripts/chunk_cli.py "readme.md" --mode parent_child \
|
||||
--parent-delimiter "##" --child-delimiter "###" \
|
||||
--max-chunk-size 2000 --child-max-size 512
|
||||
```
|
||||
|
||||
批量样例(若有 `data/`):`python scripts/run_all_samples.py`
|
||||
|
||||
### API
|
||||
|
||||
```bash
|
||||
# 健康检查
|
||||
curl http://127.0.0.1:8000/health
|
||||
|
||||
# 切分(不传 mode 等参数 → 自动策略,与 Demo 一致)
|
||||
curl -X POST http://127.0.0.1:8000/api/chunk -F "file=@./your.pdf"
|
||||
|
||||
# 切分(显式参数)
|
||||
curl -X POST http://127.0.0.1:8000/api/chunk \
|
||||
-F "file=@./your.xlsx" \
|
||||
-F "mode=by_row" \
|
||||
-F "rows_per_chunk=5"
|
||||
|
||||
# 召回(先切分拿到 doc_id)
|
||||
curl -X POST http://127.0.0.1:8000/api/recall \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{"doc_id":"abcdef123456","query":"如何修改交易密码","top_k":5}'
|
||||
```
|
||||
|
||||
也可直接:`cd backend && uvicorn api.main:app --reload --port 8000`
|
||||
|
||||
### Python
|
||||
|
||||
```python
|
||||
from pathlib import Path
|
||||
from rag_cut import chunk_document, SplitConfig, SplitMode
|
||||
from rag_cut.retrieval import recall_chunks
|
||||
|
||||
# 自动策略
|
||||
result = chunk_document(Path("doc.pdf"))
|
||||
|
||||
# 显式配置
|
||||
result = chunk_document(
|
||||
Path("doc.docx"),
|
||||
config=SplitConfig(mode=SplitMode.DEFAULT, max_chunk_size=1500),
|
||||
)
|
||||
|
||||
hits, n = recall_chunks("login password", result.chunks, top_k=5)
|
||||
```
|
||||
|
||||
将 `backend/` 加入 `PYTHONPATH`,或通过 `scripts/chunk_cli.py` 调用。
|
||||
|
||||
### 输出字段(节选)
|
||||
|
||||
```json
|
||||
{
|
||||
"filename": "guide.docx",
|
||||
"doc_id": "61c2a152cd5e",
|
||||
"split_mode": "default",
|
||||
"split_config": {
|
||||
"mode": "default",
|
||||
"max_chunk_size": 2600,
|
||||
"pdf_chunk_strategy": "pdf_feature_step_screenshot",
|
||||
"chunk_strategy": "heading_layout_multimodal"
|
||||
},
|
||||
"block_count": 269,
|
||||
"chunk_count": 48,
|
||||
"chunks": [
|
||||
{
|
||||
"index": 0,
|
||||
"content": "# …\n\n",
|
||||
"char_count": 431,
|
||||
"block_types": ["heading", "paragraph", "image"],
|
||||
"meta": {
|
||||
"heading": "1 Getting Started",
|
||||
"pages": [3],
|
||||
"embedding_text": "…",
|
||||
"retrieval": true
|
||||
}
|
||||
}
|
||||
],
|
||||
"assets_dir": "storage/assets/61c2a152cd5e"
|
||||
}
|
||||
```
|
||||
|
||||
---
|
||||
|
||||
|
||||
|
||||
## 期望效果对照
|
||||
|
||||
|
||||
| 需求 | 状态 |
|
||||
| ----------------- | ------------------------------------------- |
|
||||
| 图片保留原文位置 | ✅ PDF / Word / PPT(转 PDF) |
|
||||
| 表格提取为 Markdown | ✅ PDF / Excel / CSV |
|
||||
| Word 同标题内容同 chunk | ✅ 语义切分 |
|
||||
| PDF 多栏阅读顺序 | ✅ 双栏检测 + 行合并 |
|
||||
| 页眉页脚 / 页码噪声过滤 | ✅ MinerU 类型跳过 + 位置启发式 |
|
||||
| 手册截图文字不混入正文 | ✅ 大图区域过滤 |
|
||||
| 父子切片(超长章节) | ❌ 已从默认切分移除;超长仅按长度/子标题拆分 |
|
||||
| 父子标识符切分 | ✅ 独立模式 `parent_child`(父/子标识符 + 双长度) |
|
||||
| 召回入参/出参可检视 | ✅ `/api/recall` + Demo |
|
||||
| wps | ⏳ 未实现 |
|
||||
|
||||
|
||||
---
|
||||
|
||||
|
||||
|
||||
## 后续计划
|
||||
|
||||
- [ ] PDF OCR / 视觉描述增强
|
||||
- [ ] 向量召回(Embedding)
|
||||
- [ ] wps 格式支持
|
||||
|
||||
---
|
||||
|
||||
|
||||
|
||||
## 参考
|
||||
|
||||
- `[docx/自研搭建AI助手知识库.pdf](docx/自研搭建AI助手知识库.pdf)` — 需求
|
||||
- `[docx/mineru-integration.md](docx/mineru-integration.md)` — MinerU 接入
|
||||
- `[docx/tencent-cloud-document-splitting-settings.md](docx/tencent-cloud-document-splitting-settings.md)` — 腾讯云切分参考
|
||||
- `[CLAUDE.md](CLAUDE.md)` / `[AGENTS.md](AGENTS.md)` — AI 协作说明
|
||||
@@ -0,0 +1,22 @@
|
||||
# TASK_SUMMARY — 目录不解析、不切片
|
||||
|
||||
## 1. 任务基本信息
|
||||
|
||||
- **任务名称**:所有文件跳过文档目录
|
||||
- **相关项目**:RAG-cut
|
||||
|
||||
## 2. 改动说明
|
||||
|
||||
解析与切分链路统一剔除「目录 / Contents / TOC」标题及带页码引导线的目录条目;正文内无页码清单(如形態指標列表)保留。
|
||||
|
||||
## 3. 影响与风险
|
||||
|
||||
- 见 `IMPACT_ANALYSIS.md`;**破坏性变更:否**
|
||||
|
||||
## 4. 测试与验证
|
||||
|
||||
- 运行 `test_pdf_noise_filter`、`test_heading_layout_multimodal` 等相关单测
|
||||
|
||||
## 5. 后续事项
|
||||
|
||||
- 若遇无引导线、无页码的「伪目录」仍进切片,可再扩展 TOC 区检测
|
||||
@@ -0,0 +1 @@
|
||||
"""RAG-cut FastAPI app. Start with: python backend/run.py"""
|
||||
@@ -0,0 +1,288 @@
|
||||
"""FastAPI endpoints for document chunking + demo frontend."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import asyncio
|
||||
import json
|
||||
import mimetypes
|
||||
import re
|
||||
import shutil
|
||||
import tempfile
|
||||
import time
|
||||
from datetime import datetime, timezone
|
||||
from pathlib import Path
|
||||
|
||||
from fastapi import FastAPI, File, Form, HTTPException, UploadFile
|
||||
from fastapi.middleware.cors import CORSMiddleware
|
||||
from fastapi.responses import FileResponse, JSONResponse
|
||||
from fastapi.staticfiles import StaticFiles
|
||||
from pydantic import BaseModel, Field
|
||||
|
||||
from rag_cut.models import ChunkResult, SplitConfig, SplitMode
|
||||
from rag_cut.pipeline import chunk_document
|
||||
from rag_cut.retrieval import recall_chunks
|
||||
|
||||
ROOT = Path(__file__).resolve().parent.parent.parent
|
||||
FRONTEND_DIR = ROOT / "frontend"
|
||||
STORAGE_DIR = ROOT / "storage"
|
||||
RESULTS_DIR = STORAGE_DIR / "results"
|
||||
UPLOADS_DIR = STORAGE_DIR / "uploads"
|
||||
DOC_ID_RE = re.compile(r"^[a-f0-9]{12}$")
|
||||
WORD_EXTS = {".doc", ".docx"}
|
||||
|
||||
app = FastAPI(title="RAG-cut Chunking API", version="0.1.0")
|
||||
|
||||
app.add_middleware(
|
||||
CORSMiddleware,
|
||||
allow_origins=["*"],
|
||||
allow_credentials=False,
|
||||
allow_methods=["*"],
|
||||
allow_headers=["*"],
|
||||
)
|
||||
|
||||
(STORAGE_DIR / "assets").mkdir(parents=True, exist_ok=True)
|
||||
RESULTS_DIR.mkdir(parents=True, exist_ok=True)
|
||||
UPLOADS_DIR.mkdir(parents=True, exist_ok=True)
|
||||
app.mount("/assets", StaticFiles(directory=STORAGE_DIR / "assets"), name="assets")
|
||||
|
||||
|
||||
class RecallRequest(BaseModel):
|
||||
doc_id: str
|
||||
query: str = Field(min_length=1, max_length=500)
|
||||
top_k: int = Field(default=5, ge=1, le=20)
|
||||
|
||||
|
||||
def _result_path(doc_id: str) -> Path:
|
||||
if not DOC_ID_RE.fullmatch(doc_id):
|
||||
raise HTTPException(status_code=400, detail="Invalid doc_id")
|
||||
return RESULTS_DIR / f"{doc_id}.json"
|
||||
|
||||
|
||||
def _save_result(result: ChunkResult) -> None:
|
||||
_result_path(result.doc_id).write_text(result.model_dump_json(indent=2), encoding="utf-8")
|
||||
|
||||
|
||||
def _find_original(doc_id: str) -> Path | None:
|
||||
uploads_dir = UPLOADS_DIR / doc_id
|
||||
if not uploads_dir.is_dir():
|
||||
return None
|
||||
files = sorted(p for p in uploads_dir.iterdir() if p.is_file())
|
||||
return files[0] if files else None
|
||||
|
||||
|
||||
def _find_preview(doc_id: str) -> Path | None:
|
||||
"""Return a browser-previewable source, preferring converted Word PDFs."""
|
||||
original = _find_original(doc_id)
|
||||
if original is None:
|
||||
return None
|
||||
if original.suffix.lower() == ".pdf":
|
||||
return original
|
||||
if original.suffix.lower() not in WORD_EXTS:
|
||||
return None
|
||||
|
||||
conversion_dir = STORAGE_DIR / "assets" / doc_id / "_conversion"
|
||||
exact = conversion_dir / f"{original.stem}.pdf"
|
||||
if exact.is_file():
|
||||
return exact
|
||||
if conversion_dir.is_dir():
|
||||
return next(iter(sorted(conversion_dir.glob("*.pdf"))), None)
|
||||
return None
|
||||
|
||||
|
||||
def _load_result(doc_id: str) -> ChunkResult:
|
||||
result_path = _result_path(doc_id)
|
||||
if not result_path.exists():
|
||||
raise HTTPException(status_code=404, detail="Chunk result not found")
|
||||
try:
|
||||
return ChunkResult.model_validate_json(result_path.read_text(encoding="utf-8"))
|
||||
except Exception as exc:
|
||||
raise HTTPException(status_code=500, detail=f"Invalid result file: {exc}") from exc
|
||||
|
||||
|
||||
def _result_summary(path: Path) -> dict | None:
|
||||
"""Build list summary without loading the full chunks array."""
|
||||
try:
|
||||
with path.open("r", encoding="utf-8") as fh:
|
||||
head = fh.read(32768)
|
||||
idx = head.find('\n "chunks"')
|
||||
if idx == -1:
|
||||
idx = head.find('"chunks"')
|
||||
if idx != -1:
|
||||
data = json.loads(head[:idx].rstrip().rstrip(",") + "\n}")
|
||||
else:
|
||||
data = json.loads(path.read_text(encoding="utf-8"))
|
||||
except (OSError, json.JSONDecodeError):
|
||||
return None
|
||||
doc_id = data.get("doc_id") or path.stem
|
||||
if not DOC_ID_RE.fullmatch(str(doc_id)):
|
||||
return None
|
||||
mtime = path.stat().st_mtime
|
||||
return {
|
||||
"doc_id": doc_id,
|
||||
"filename": data.get("filename") or path.name,
|
||||
"split_mode": data.get("split_mode"),
|
||||
"chunk_count": data.get("chunk_count", 0),
|
||||
"block_count": data.get("block_count", 0),
|
||||
"has_original": _find_original(doc_id) is not None,
|
||||
"saved_at": datetime.fromtimestamp(mtime, tz=timezone.utc).isoformat(),
|
||||
"saved_ts": mtime,
|
||||
}
|
||||
|
||||
|
||||
@app.get("/health")
|
||||
def health():
|
||||
return {"status": "ok"}
|
||||
|
||||
|
||||
@app.get("/api/results")
|
||||
def list_results():
|
||||
"""List persisted chunk results (newest first)."""
|
||||
items: list[dict] = []
|
||||
for path in RESULTS_DIR.glob("*.json"):
|
||||
summary = _result_summary(path)
|
||||
if summary:
|
||||
items.append(summary)
|
||||
items.sort(key=lambda item: item["saved_ts"], reverse=True)
|
||||
for item in items:
|
||||
item.pop("saved_ts", None)
|
||||
return {"count": len(items), "results": items}
|
||||
|
||||
|
||||
@app.get("/api/results/{doc_id}")
|
||||
def get_result(doc_id: str):
|
||||
"""Load a full persisted chunk result by doc_id."""
|
||||
chunk_result = _load_result(doc_id)
|
||||
payload = json.loads(chunk_result.model_dump_json())
|
||||
payload["has_original"] = _find_original(doc_id) is not None
|
||||
return JSONResponse(content=payload)
|
||||
|
||||
|
||||
@app.get("/api/results/{doc_id}/original")
|
||||
def get_original(doc_id: str):
|
||||
"""Serve the original uploaded file for a historical result (if still on disk)."""
|
||||
if not DOC_ID_RE.fullmatch(doc_id):
|
||||
raise HTTPException(status_code=400, detail="Invalid doc_id")
|
||||
original = _find_original(doc_id)
|
||||
if original is None:
|
||||
raise HTTPException(status_code=404, detail="Original file not found")
|
||||
media_type, _ = mimetypes.guess_type(original.name)
|
||||
return FileResponse(
|
||||
path=original,
|
||||
media_type=media_type or "application/octet-stream",
|
||||
filename=original.name,
|
||||
)
|
||||
|
||||
|
||||
@app.get("/api/results/{doc_id}/preview")
|
||||
def get_preview(doc_id: str):
|
||||
"""Serve an inline PDF preview for PDF and converted Word documents."""
|
||||
if not DOC_ID_RE.fullmatch(doc_id):
|
||||
raise HTTPException(status_code=400, detail="Invalid doc_id")
|
||||
preview = _find_preview(doc_id)
|
||||
if preview is None:
|
||||
raise HTTPException(status_code=404, detail="PDF preview not found")
|
||||
return FileResponse(path=preview, media_type="application/pdf")
|
||||
|
||||
|
||||
def _delete_tree(path: Path) -> bool:
|
||||
if not path.exists():
|
||||
return False
|
||||
if path.is_dir():
|
||||
shutil.rmtree(path)
|
||||
else:
|
||||
path.unlink()
|
||||
return True
|
||||
|
||||
|
||||
@app.delete("/api/results/{doc_id}")
|
||||
def delete_result(doc_id: str):
|
||||
"""Delete a persisted chunk result and its uploads/assets."""
|
||||
result_path = _result_path(doc_id)
|
||||
if not result_path.exists():
|
||||
raise HTTPException(status_code=404, detail="Chunk result not found")
|
||||
|
||||
removed = {
|
||||
"result": _delete_tree(result_path),
|
||||
"uploads": _delete_tree(UPLOADS_DIR / doc_id),
|
||||
"assets": _delete_tree(STORAGE_DIR / "assets" / doc_id),
|
||||
}
|
||||
return {"doc_id": doc_id, "deleted": True, "removed": removed}
|
||||
|
||||
|
||||
@app.post("/api/chunk")
|
||||
async def chunk_file(
|
||||
file: UploadFile = File(...),
|
||||
mode: str | None = Form(None),
|
||||
delimiter: str | None = Form(None),
|
||||
parent_delimiter: str | None = Form(None),
|
||||
child_delimiter: str | None = Form(None),
|
||||
max_chunk_size: int | None = Form(None),
|
||||
child_max_size: int | None = Form(None),
|
||||
overlap: int | None = Form(None),
|
||||
header_row_start: int | None = Form(None),
|
||||
header_row_end: int | None = Form(None),
|
||||
start_row: int | None = Form(None),
|
||||
rows_per_chunk: int | None = Form(None),
|
||||
):
|
||||
config = None
|
||||
if mode is not None:
|
||||
try:
|
||||
split_mode = SplitMode(mode)
|
||||
except ValueError as exc:
|
||||
raise HTTPException(status_code=400, detail=f"Invalid mode: {mode}") from exc
|
||||
|
||||
config = SplitConfig(
|
||||
mode=split_mode,
|
||||
delimiter=delimiter,
|
||||
parent_delimiter=parent_delimiter,
|
||||
child_delimiter=child_delimiter,
|
||||
max_chunk_size=1500 if max_chunk_size is None else max_chunk_size,
|
||||
child_max_size=512 if child_max_size is None else child_max_size,
|
||||
overlap=150 if overlap is None else overlap,
|
||||
header_row_start=1 if header_row_start is None else header_row_start,
|
||||
header_row_end=1 if header_row_end is None else header_row_end,
|
||||
start_row=2 if start_row is None else start_row,
|
||||
rows_per_chunk=1 if rows_per_chunk is None else rows_per_chunk,
|
||||
)
|
||||
|
||||
filename = Path(file.filename or "upload").name
|
||||
payload = await file.read()
|
||||
with tempfile.TemporaryDirectory() as tmp:
|
||||
tmp_path = Path(tmp) / filename
|
||||
tmp_path.write_bytes(payload)
|
||||
try:
|
||||
# Heavy parsing (MinerU / LibreOffice / OCR) must not block the event loop,
|
||||
# otherwise /health and other uploads hang while one document is processing.
|
||||
result = await asyncio.to_thread(chunk_document, tmp_path, config)
|
||||
_save_result(result)
|
||||
return JSONResponse(content=json.loads(result.model_dump_json()))
|
||||
except ValueError as exc:
|
||||
raise HTTPException(status_code=400, detail=str(exc)) from exc
|
||||
except FileNotFoundError as exc:
|
||||
raise HTTPException(status_code=404, detail=str(exc)) from exc
|
||||
except RuntimeError as exc:
|
||||
raise HTTPException(status_code=500, detail=str(exc)) from exc
|
||||
|
||||
|
||||
@app.post("/api/recall")
|
||||
def recall(request: RecallRequest):
|
||||
result_path = _result_path(request.doc_id)
|
||||
if not result_path.exists():
|
||||
raise HTTPException(status_code=404, detail="Chunk result not found; upload and split the document again")
|
||||
|
||||
started = time.perf_counter()
|
||||
chunk_result = ChunkResult.model_validate_json(result_path.read_text(encoding="utf-8"))
|
||||
results, candidate_count = recall_chunks(request.query, chunk_result.chunks, request.top_k)
|
||||
return {
|
||||
"doc_id": request.doc_id,
|
||||
"query": request.query,
|
||||
"top_k": request.top_k,
|
||||
"candidate_count": candidate_count,
|
||||
"returned_count": len(results),
|
||||
"elapsed_ms": round((time.perf_counter() - started) * 1000, 3),
|
||||
"results": results,
|
||||
}
|
||||
|
||||
|
||||
if FRONTEND_DIR.exists():
|
||||
app.mount("/", StaticFiles(directory=FRONTEND_DIR, html=True), name="frontend")
|
||||
@@ -0,0 +1,6 @@
|
||||
"""RAG-cut document chunking pipeline."""
|
||||
|
||||
from rag_cut.models import Block, Chunk, SplitConfig, SplitMode
|
||||
from rag_cut.pipeline import chunk_document
|
||||
|
||||
__all__ = ["Block", "Chunk", "SplitConfig", "SplitMode", "chunk_document"]
|
||||
@@ -0,0 +1,244 @@
|
||||
"""Layout metadata: reading order, heading binding, image context."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
from rag_cut.models import Block, BlockType
|
||||
from rag_cut.parsers.pdf.tables import build_table_embedding_text, extract_table_keywords, guess_table_title
|
||||
from rag_cut.splitters.heading_splitter import is_heading_block, normalize_heading_block
|
||||
|
||||
|
||||
def assign_order_index(blocks: list[Block], start: int = 0) -> list[Block]:
|
||||
"""Assign a global document-order index to every block."""
|
||||
result: list[Block] = []
|
||||
for idx, block in enumerate(blocks):
|
||||
meta = dict(block.meta)
|
||||
meta["order_index"] = start + idx
|
||||
result.append(block.model_copy(update={"meta": meta}))
|
||||
return result
|
||||
|
||||
|
||||
def sort_blocks_reading_order(blocks: list[Block]) -> list[Block]:
|
||||
"""Sort by page then top-to-bottom / left-to-right; stable for missing bboxes."""
|
||||
|
||||
def sort_key(item: tuple[int, Block]) -> tuple[int, float, float, int]:
|
||||
idx, block = item
|
||||
page = block.meta.get("page")
|
||||
try:
|
||||
page_key = int(page) if page is not None else 10**9
|
||||
except (TypeError, ValueError):
|
||||
page_key = 10**9
|
||||
bbox = block.meta.get("bbox")
|
||||
if isinstance(bbox, (list, tuple)) and len(bbox) >= 4:
|
||||
try:
|
||||
return (page_key, float(bbox[1]), float(bbox[0]), idx)
|
||||
except (TypeError, ValueError):
|
||||
pass
|
||||
return (page_key, float(idx), 0.0, idx)
|
||||
|
||||
return [block for _, block in sorted(enumerate(blocks), key=sort_key)]
|
||||
|
||||
|
||||
def bind_heading_context(blocks: list[Block]) -> list[Block]:
|
||||
"""
|
||||
Propagate heading hierarchy and bind images to nearest heading and adjacent text.
|
||||
Chunk content should follow: heading → body → image → OCR/caption → subsequent body.
|
||||
"""
|
||||
heading_stack: list[tuple[int, str]] = []
|
||||
result: list[Block] = []
|
||||
|
||||
for i, block in enumerate(blocks):
|
||||
meta = dict(block.meta)
|
||||
candidate = normalize_heading_block(block)
|
||||
|
||||
if is_heading_block(candidate):
|
||||
level = candidate.level or 1
|
||||
while heading_stack and heading_stack[-1][0] >= level:
|
||||
heading_stack.pop()
|
||||
heading_stack.append((level, candidate.text))
|
||||
meta["section_boundary"] = True
|
||||
if block.type != BlockType.HEADING or candidate is not block:
|
||||
block = candidate.model_copy(update={"meta": {**dict(candidate.meta), **meta}})
|
||||
meta = dict(block.meta)
|
||||
else:
|
||||
meta["section_boundary"] = False
|
||||
# Demote overlong HEADING blobs (title+body merge) back to paragraph.
|
||||
if block.type == BlockType.HEADING and candidate.type != BlockType.HEADING:
|
||||
block = candidate.model_copy(update={"meta": {**dict(candidate.meta), **meta}})
|
||||
meta = dict(block.meta)
|
||||
|
||||
if heading_stack:
|
||||
meta["parent_heading"] = heading_stack[-1][1]
|
||||
meta["heading_path"] = [text for _, text in heading_stack]
|
||||
meta["nearest_heading"] = heading_stack[-1][1]
|
||||
if (block.level or 1) <= 2 and block.type == BlockType.HEADING:
|
||||
meta["chapter"] = block.text
|
||||
elif "chapter" not in meta and len(heading_stack) >= 1:
|
||||
# Keep chapter as nearest level-1/2 ancestor
|
||||
for lvl, text in reversed(heading_stack):
|
||||
if lvl <= 2:
|
||||
meta["chapter"] = text
|
||||
break
|
||||
|
||||
if block.type == BlockType.IMAGE:
|
||||
_bind_image_context(blocks, i, meta)
|
||||
elif block.type == BlockType.TABLE:
|
||||
_bind_table_context(blocks, i, meta)
|
||||
|
||||
result.append(block.model_copy(update={"meta": meta}))
|
||||
|
||||
return result
|
||||
|
||||
|
||||
def _heading_text(block: Block) -> str | None:
|
||||
candidate = normalize_heading_block(block)
|
||||
if is_heading_block(candidate):
|
||||
return (candidate.text or "").strip() or None
|
||||
return None
|
||||
|
||||
|
||||
def _spatial_heading_above(
|
||||
blocks: list[Block],
|
||||
index: int,
|
||||
page: object,
|
||||
bbox: list[float] | None,
|
||||
) -> str | None:
|
||||
"""Pick same-page heading whose bottom edge is nearest above the image top."""
|
||||
if page is None or not bbox or len(bbox) < 4:
|
||||
return None
|
||||
try:
|
||||
page_key = int(page)
|
||||
img_y0 = float(bbox[1])
|
||||
except (TypeError, ValueError):
|
||||
return None
|
||||
|
||||
best_text: str | None = None
|
||||
best_dist = float("inf")
|
||||
for j, block in enumerate(blocks):
|
||||
if j == index:
|
||||
continue
|
||||
text = _heading_text(block)
|
||||
if not text:
|
||||
continue
|
||||
try:
|
||||
if int(block.meta.get("page")) != page_key:
|
||||
continue
|
||||
except (TypeError, ValueError):
|
||||
continue
|
||||
hb = block.meta.get("bbox")
|
||||
if not isinstance(hb, (list, tuple)) or len(hb) < 4:
|
||||
continue
|
||||
try:
|
||||
heading_y1 = float(hb[3])
|
||||
except (TypeError, ValueError):
|
||||
continue
|
||||
if heading_y1 > img_y0 + 2:
|
||||
continue
|
||||
dist = img_y0 - heading_y1
|
||||
if dist < best_dist:
|
||||
best_dist = dist
|
||||
best_text = text
|
||||
return best_text
|
||||
|
||||
|
||||
def _list_heading_above(blocks: list[Block], index: int) -> str | None:
|
||||
for j in range(index - 1, -1, -1):
|
||||
text = _heading_text(blocks[j])
|
||||
if text:
|
||||
return text
|
||||
return None
|
||||
|
||||
|
||||
def _bind_image_context(blocks: list[Block], index: int, meta: dict) -> None:
|
||||
"""Bind image to nearest heading above and adjacent body text on the same page."""
|
||||
page = meta.get("page")
|
||||
bbox = meta.get("bbox") if isinstance(meta.get("bbox"), list) else None
|
||||
|
||||
bound = _spatial_heading_above(blocks, index, page, bbox) or _list_heading_above(blocks, index)
|
||||
if bound:
|
||||
meta["bound_heading"] = bound
|
||||
|
||||
for j in range(index - 1, -1, -1):
|
||||
prev = blocks[j]
|
||||
if _heading_text(prev):
|
||||
break
|
||||
if prev.type == BlockType.PARAGRAPH and prev.meta.get("page") == page:
|
||||
meta["preceding_text"] = (prev.text or "")[:300]
|
||||
break
|
||||
|
||||
if not meta.get("bound_heading") and meta.get("nearest_heading"):
|
||||
meta["bound_heading"] = meta["nearest_heading"]
|
||||
|
||||
for j in range(index + 1, len(blocks)):
|
||||
nxt = blocks[j]
|
||||
if nxt.type == BlockType.IMAGE:
|
||||
break
|
||||
if nxt.type == BlockType.PARAGRAPH and nxt.meta.get("page") == page:
|
||||
meta["following_text"] = (nxt.text or "")[:300]
|
||||
break
|
||||
if _heading_text(nxt):
|
||||
break
|
||||
|
||||
|
||||
def _bind_table_context(blocks: list[Block], index: int, meta: dict) -> None:
|
||||
"""Bind table title, surrounding text and retrieval fields."""
|
||||
page = meta.get("page")
|
||||
block = blocks[index]
|
||||
|
||||
for j in range(index - 1, -1, -1):
|
||||
prev = blocks[j]
|
||||
if prev.type == BlockType.TABLE:
|
||||
break
|
||||
heading = _heading_text(prev)
|
||||
if heading:
|
||||
if not meta.get("table_title"):
|
||||
meta["table_title"] = heading
|
||||
meta.setdefault("bound_heading", heading)
|
||||
break
|
||||
if prev.type == BlockType.PARAGRAPH and prev.meta.get("page") == page:
|
||||
title = guess_table_title(prev.text or "")
|
||||
if title:
|
||||
meta["table_title"] = title
|
||||
meta["preceding_text"] = (prev.text or "")[:400]
|
||||
break
|
||||
|
||||
if not meta.get("table_title") and meta.get("nearest_heading"):
|
||||
meta.setdefault("table_title", meta["nearest_heading"])
|
||||
|
||||
for j in range(index + 1, len(blocks)):
|
||||
nxt = blocks[j]
|
||||
if nxt.type == BlockType.TABLE:
|
||||
break
|
||||
if nxt.type == BlockType.PARAGRAPH and nxt.meta.get("page") == page:
|
||||
text = (nxt.text or "").strip()
|
||||
if text and len(text) <= 300:
|
||||
meta["following_text"] = text
|
||||
if not meta.get("footnotes") and any(k in text for k in ("注", "备注", "说明", "Note")):
|
||||
meta["table_description"] = text
|
||||
break
|
||||
if _heading_text(nxt):
|
||||
break
|
||||
|
||||
if not meta.get("keywords"):
|
||||
meta["keywords"] = extract_table_keywords(
|
||||
meta.get("table_title") or "",
|
||||
block.markdown or "",
|
||||
meta.get("table_description") or meta.get("footnotes") or "",
|
||||
block.ocr_text or "",
|
||||
)
|
||||
|
||||
meta["embedding_text"] = build_table_embedding_text(
|
||||
chapter=meta.get("chapter") or meta.get("nearest_heading") or "",
|
||||
table_title=meta.get("table_title") or "",
|
||||
markdown=block.markdown or "",
|
||||
description=meta.get("table_description") or meta.get("preceding_text") or "",
|
||||
footnotes=meta.get("footnotes") or meta.get("following_text") or "",
|
||||
keywords=meta.get("keywords") or [],
|
||||
ocr_text=block.ocr_text or "",
|
||||
)
|
||||
|
||||
|
||||
def enrich_layout_metadata(blocks: list[Block]) -> list[Block]:
|
||||
"""Full post-parse enrichment: spatial order + order index + heading/image context."""
|
||||
blocks = sort_blocks_reading_order(blocks)
|
||||
blocks = assign_order_index(blocks)
|
||||
return bind_heading_context(blocks)
|
||||
@@ -0,0 +1,100 @@
|
||||
"""Core data models for document chunking."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
from enum import Enum
|
||||
from typing import Any
|
||||
|
||||
from pydantic import BaseModel, Field
|
||||
|
||||
|
||||
class BlockType(str, Enum):
|
||||
HEADING = "heading"
|
||||
PARAGRAPH = "paragraph"
|
||||
TABLE = "table"
|
||||
IMAGE = "image"
|
||||
LIST = "list"
|
||||
CODE = "code"
|
||||
|
||||
|
||||
class SplitMode(str, Enum):
|
||||
DEFAULT = "default"
|
||||
DELIMITER = "delimiter"
|
||||
PARENT_CHILD = "parent_child"
|
||||
BY_ROW = "by_row"
|
||||
|
||||
|
||||
class Block(BaseModel):
|
||||
"""Atomic document unit; images and tables must not be split across chunks."""
|
||||
|
||||
type: BlockType
|
||||
text: str = ""
|
||||
markdown: str = ""
|
||||
level: int = 0
|
||||
image_id: str | None = None
|
||||
image_path: str | None = None
|
||||
ocr_text: str = ""
|
||||
meta: dict[str, Any] = Field(default_factory=dict)
|
||||
|
||||
def render(self) -> str:
|
||||
if self.type == BlockType.TABLE:
|
||||
parts: list[str] = []
|
||||
title = self.meta.get("table_title")
|
||||
if title:
|
||||
parts.append(f"### {title}")
|
||||
image_ref = self.image_path or self.meta.get("crop_path")
|
||||
if image_ref:
|
||||
alt = (title or self.image_id or "table").replace("\n", " ").strip()
|
||||
parts.append(f"")
|
||||
parts.append(self.markdown or self.text)
|
||||
footnotes = self.meta.get("footnotes")
|
||||
if footnotes and footnotes not in (self.markdown or ""):
|
||||
parts.append(f"*{footnotes}*")
|
||||
if self.ocr_text:
|
||||
parts.append(f"*[表格 OCR]* {self.ocr_text}")
|
||||
return "\n\n".join(p for p in parts if p.strip())
|
||||
if self.type == BlockType.IMAGE:
|
||||
alt = (self.image_id or self.text or "image").replace("\n", " ").strip()
|
||||
path = self.image_path or self.image_id or ""
|
||||
body = f""
|
||||
if self.ocr_text:
|
||||
body += f"\n\n*[OCR]* {self.ocr_text}"
|
||||
return body
|
||||
if self.type == BlockType.HEADING:
|
||||
prefix = "#" * max(1, min(self.level, 6))
|
||||
return f"{prefix} {self.text}".strip()
|
||||
return self.text or self.markdown
|
||||
|
||||
|
||||
class SplitConfig(BaseModel):
|
||||
mode: SplitMode = SplitMode.DEFAULT
|
||||
delimiter: str | None = None
|
||||
parent_delimiter: str | None = None
|
||||
child_delimiter: str | None = None
|
||||
max_chunk_size: int = 1500
|
||||
child_max_size: int = 512
|
||||
overlap: int = 150
|
||||
header_row_start: int = 1
|
||||
header_row_end: int = 1
|
||||
start_row: int = 2
|
||||
rows_per_chunk: int = 1
|
||||
table_format: str = "markdown"
|
||||
|
||||
|
||||
class Chunk(BaseModel):
|
||||
index: int
|
||||
content: str
|
||||
char_count: int
|
||||
block_types: list[str]
|
||||
meta: dict[str, Any] = Field(default_factory=dict)
|
||||
|
||||
|
||||
class ChunkResult(BaseModel):
|
||||
filename: str
|
||||
doc_id: str
|
||||
split_mode: SplitMode
|
||||
split_config: dict[str, Any] = Field(default_factory=dict)
|
||||
block_count: int
|
||||
chunk_count: int
|
||||
chunks: list[Chunk]
|
||||
assets_dir: str | None = None
|
||||
@@ -0,0 +1,5 @@
|
||||
"""Document parsers."""
|
||||
|
||||
from rag_cut.parsers.registry import get_parser
|
||||
|
||||
__all__ = ["get_parser"]
|
||||
@@ -0,0 +1,14 @@
|
||||
"""Parser base class."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
from abc import ABC, abstractmethod
|
||||
from pathlib import Path
|
||||
|
||||
from rag_cut.models import Block
|
||||
|
||||
|
||||
class BaseParser(ABC):
|
||||
@abstractmethod
|
||||
def parse(self, path: Path, assets_dir: Path) -> list[Block]:
|
||||
raise NotImplementedError
|
||||
@@ -0,0 +1,24 @@
|
||||
"""Standalone image parser."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import shutil
|
||||
from pathlib import Path
|
||||
|
||||
from rag_cut.models import Block, BlockType
|
||||
from rag_cut.parsers.base import BaseParser
|
||||
|
||||
|
||||
class ImageParser(BaseParser):
|
||||
def parse(self, path: Path, assets_dir: Path) -> list[Block]:
|
||||
assets_dir.mkdir(parents=True, exist_ok=True)
|
||||
target = assets_dir / path.name
|
||||
shutil.copy2(path, target)
|
||||
return [
|
||||
Block(
|
||||
type=BlockType.IMAGE,
|
||||
text=path.stem,
|
||||
image_id=path.name,
|
||||
image_path=str(target),
|
||||
)
|
||||
]
|
||||
@@ -0,0 +1,421 @@
|
||||
"""Optional MinerU parser adapter.
|
||||
|
||||
MinerU improves the parsing layer when installed, while RAG-cut keeps owning
|
||||
chunking strategy and retrieval metadata.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import json
|
||||
import os
|
||||
import signal
|
||||
import shutil
|
||||
import subprocess
|
||||
from pathlib import Path
|
||||
from typing import Any
|
||||
|
||||
from rag_cut.models import Block, BlockType
|
||||
from rag_cut.parsers.pdf.ocr import describe_visual, ocr_image_file
|
||||
|
||||
|
||||
def _mineru_command() -> str | None:
|
||||
configured = os.getenv("RAG_CUT_MINERU_CMD")
|
||||
if configured:
|
||||
return configured
|
||||
return shutil.which("mineru") or shutil.which("magic-pdf")
|
||||
|
||||
|
||||
def _mineru_timeout_sec() -> float:
|
||||
raw = os.getenv("RAG_CUT_MINERU_TIMEOUT", "540").strip()
|
||||
try:
|
||||
return max(30.0, float(raw))
|
||||
except ValueError:
|
||||
return 540.0
|
||||
|
||||
|
||||
def _mineru_ocr_enabled() -> bool:
|
||||
"""Fill empty OCR from image assets when pytesseract is available."""
|
||||
raw = os.getenv("RAG_CUT_MINERU_OCR", "1").strip().lower()
|
||||
return raw not in {"0", "false", "off", "no"}
|
||||
|
||||
|
||||
def _terminate_process_tree(process: subprocess.Popen[str]) -> None:
|
||||
"""Stop MinerU and any temporary API/model workers it started."""
|
||||
try:
|
||||
if os.name == "nt":
|
||||
subprocess.run(
|
||||
["taskkill", "/PID", str(process.pid), "/T", "/F"],
|
||||
check=False,
|
||||
capture_output=True,
|
||||
timeout=10,
|
||||
)
|
||||
else:
|
||||
os.killpg(process.pid, signal.SIGKILL)
|
||||
except (OSError, subprocess.SubprocessError):
|
||||
pass
|
||||
|
||||
if process.poll() is None:
|
||||
process.kill()
|
||||
try:
|
||||
process.wait(timeout=5)
|
||||
except (OSError, subprocess.SubprocessError):
|
||||
pass
|
||||
|
||||
|
||||
def _run_mineru(path: Path, output_dir: Path) -> bool:
|
||||
cmd = _mineru_command()
|
||||
if not cmd:
|
||||
return False
|
||||
|
||||
output_dir.mkdir(parents=True, exist_ok=True)
|
||||
if Path(cmd).name.lower() == "magic-pdf":
|
||||
args = [cmd, "-p", str(path), "-o", str(output_dir)]
|
||||
else:
|
||||
args = [cmd, "-p", str(path), "-o", str(output_dir), "-b", "pipeline"]
|
||||
api_url = os.getenv("RAG_CUT_MINERU_API_URL", "").strip()
|
||||
if api_url:
|
||||
args.extend(["--api-url", api_url])
|
||||
|
||||
try:
|
||||
popen_kwargs: dict[str, Any] = {}
|
||||
if os.name == "nt":
|
||||
popen_kwargs["creationflags"] = getattr(subprocess, "CREATE_NEW_PROCESS_GROUP", 0)
|
||||
else:
|
||||
popen_kwargs["start_new_session"] = True
|
||||
|
||||
process = subprocess.Popen(
|
||||
args,
|
||||
stdout=subprocess.PIPE,
|
||||
stderr=subprocess.PIPE,
|
||||
text=True,
|
||||
encoding="utf-8",
|
||||
errors="replace",
|
||||
**popen_kwargs,
|
||||
)
|
||||
process.communicate(timeout=_mineru_timeout_sec())
|
||||
except subprocess.TimeoutExpired:
|
||||
_terminate_process_tree(process)
|
||||
return False
|
||||
except (OSError, subprocess.SubprocessError):
|
||||
return False
|
||||
return process.returncode == 0
|
||||
|
||||
|
||||
def _find_content_list(output_dir: Path) -> Path | None:
|
||||
"""Prefer stable content_list.json over content_list_v2.json."""
|
||||
candidates = list(output_dir.rglob("*content_list*.json"))
|
||||
if not candidates:
|
||||
return None
|
||||
|
||||
def rank(path: Path) -> tuple[int, int, str]:
|
||||
name = path.name.lower()
|
||||
is_v2 = 1 if "v2" in name else 0
|
||||
return (is_v2, len(path.parts), str(path).lower())
|
||||
|
||||
return sorted(candidates, key=rank)[0]
|
||||
|
||||
|
||||
def _read_json(path: Path) -> Any:
|
||||
return json.loads(path.read_text(encoding="utf-8"))
|
||||
|
||||
|
||||
def _resolve_asset(path_text: str, base_dir: Path) -> Path | None:
|
||||
if not path_text:
|
||||
return None
|
||||
raw = Path(path_text)
|
||||
if raw.is_absolute() and raw.exists():
|
||||
return raw
|
||||
candidate = base_dir / raw
|
||||
if candidate.exists():
|
||||
return candidate
|
||||
matches = list(base_dir.rglob(raw.name))
|
||||
return matches[0] if matches else None
|
||||
|
||||
|
||||
def _copy_asset(src: Path | None, assets_dir: Path) -> tuple[str | None, str | None]:
|
||||
if not src or not src.exists():
|
||||
return None, None
|
||||
assets_dir.mkdir(parents=True, exist_ok=True)
|
||||
target = assets_dir / src.name
|
||||
if src.resolve() != target.resolve():
|
||||
shutil.copy2(src, target)
|
||||
return target.name, str(target)
|
||||
|
||||
|
||||
def _page(item: dict[str, Any]) -> int | None:
|
||||
for key in ("page", "page_no", "page_num"):
|
||||
if item.get(key) is not None:
|
||||
try:
|
||||
return int(item[key])
|
||||
except (TypeError, ValueError):
|
||||
return None
|
||||
if item.get("page_idx") is not None:
|
||||
try:
|
||||
return int(item["page_idx"]) + 1
|
||||
except (TypeError, ValueError):
|
||||
return None
|
||||
return None
|
||||
|
||||
|
||||
def _bbox(item: dict[str, Any]) -> list[float]:
|
||||
raw = item.get("bbox") or item.get("poly") or []
|
||||
if isinstance(raw, list) and len(raw) >= 4:
|
||||
try:
|
||||
if all(isinstance(v, (int, float)) for v in raw[:4]):
|
||||
return [float(v) for v in raw[:4]]
|
||||
if all(isinstance(p, list) and len(p) >= 2 for p in raw):
|
||||
xs = [float(p[0]) for p in raw]
|
||||
ys = [float(p[1]) for p in raw]
|
||||
return [min(xs), min(ys), max(xs), max(ys)]
|
||||
except (TypeError, ValueError):
|
||||
return []
|
||||
return []
|
||||
|
||||
|
||||
def _meta(item: dict[str, Any]) -> dict[str, Any]:
|
||||
meta: dict[str, Any] = {"parser": "mineru"}
|
||||
page = _page(item)
|
||||
bbox = _bbox(item)
|
||||
kind = _item_type(item)
|
||||
if page:
|
||||
meta["page"] = page
|
||||
if bbox:
|
||||
meta["bbox"] = bbox
|
||||
if kind:
|
||||
meta["mineru_type"] = kind
|
||||
return meta
|
||||
|
||||
|
||||
def _text_value(item: dict[str, Any]) -> str:
|
||||
for key in (
|
||||
"text",
|
||||
"content",
|
||||
"table_caption",
|
||||
"image_caption",
|
||||
"code_body",
|
||||
"code",
|
||||
"equation",
|
||||
"latex",
|
||||
):
|
||||
value = item.get(key)
|
||||
if isinstance(value, str) and value.strip():
|
||||
return value.strip()
|
||||
if isinstance(value, list):
|
||||
joined = " ".join(str(v).strip() for v in value if str(v).strip())
|
||||
if joined:
|
||||
return joined
|
||||
|
||||
list_items = item.get("list_items")
|
||||
if isinstance(list_items, list) and list_items:
|
||||
parts: list[str] = []
|
||||
for entry in list_items:
|
||||
if isinstance(entry, str) and entry.strip():
|
||||
parts.append(entry.strip())
|
||||
elif isinstance(entry, dict):
|
||||
piece = str(entry.get("text") or entry.get("content") or "").strip()
|
||||
if piece:
|
||||
parts.append(piece)
|
||||
if parts:
|
||||
return "\n".join(parts)
|
||||
return ""
|
||||
|
||||
|
||||
def _table_markdown(item: dict[str, Any]) -> str:
|
||||
for key in ("table_body", "html", "text", "content"):
|
||||
value = item.get(key)
|
||||
if isinstance(value, str) and value.strip():
|
||||
return value.strip()
|
||||
return ""
|
||||
|
||||
|
||||
def _image_path_text(item: dict[str, Any]) -> str:
|
||||
for key in ("img_path", "image_path", "path"):
|
||||
value = item.get(key)
|
||||
if isinstance(value, str) and value.strip():
|
||||
return value.strip()
|
||||
return ""
|
||||
|
||||
|
||||
def _item_type(item: dict[str, Any]) -> str:
|
||||
return str(item.get("type") or item.get("category") or "").lower()
|
||||
|
||||
|
||||
def _ocr_from_item(item: dict[str, Any], image_path: str | None) -> str:
|
||||
ocr_text = str(item.get("ocr_text") or item.get("image_ocr") or item.get("img_caption") or "").strip()
|
||||
if not ocr_text:
|
||||
caption = item.get("image_caption")
|
||||
if isinstance(caption, list):
|
||||
ocr_text = " ".join(str(v).strip() for v in caption if str(v).strip())
|
||||
elif isinstance(caption, str):
|
||||
ocr_text = caption.strip()
|
||||
if ocr_text or not image_path or not _mineru_ocr_enabled():
|
||||
return ocr_text
|
||||
return ocr_image_file(Path(image_path))
|
||||
|
||||
|
||||
_SKIP_MINERU_TYPES = frozenset(
|
||||
{
|
||||
"header",
|
||||
"page_header",
|
||||
"footer",
|
||||
"page_footer",
|
||||
"page_number",
|
||||
"page_num",
|
||||
"header_image",
|
||||
"footer_image",
|
||||
"aside_text",
|
||||
"toc",
|
||||
"contents",
|
||||
"table_of_contents",
|
||||
}
|
||||
)
|
||||
|
||||
# Visual regions MinerU may label separately from plain "image".
|
||||
_IMAGE_KINDS = frozenset(
|
||||
{
|
||||
"image",
|
||||
"figure",
|
||||
"chart",
|
||||
"diagram",
|
||||
"graphic",
|
||||
"photo",
|
||||
"screenshot",
|
||||
"equation",
|
||||
"formula",
|
||||
}
|
||||
)
|
||||
|
||||
|
||||
def _build_image_block(
|
||||
item: dict[str, Any],
|
||||
base_dir: Path,
|
||||
assets_dir: Path,
|
||||
*,
|
||||
visual_kind: str = "图片",
|
||||
) -> Block | None:
|
||||
src = _resolve_asset(_image_path_text(item), base_dir)
|
||||
image_id, image_path = _copy_asset(src, assets_dir)
|
||||
if not image_id and not image_path:
|
||||
return None
|
||||
|
||||
caption = _text_value(item)
|
||||
ocr_text = _ocr_from_item(item, image_path)
|
||||
meta = _meta(item)
|
||||
meta.update(
|
||||
{
|
||||
"caption": caption,
|
||||
"source_image_path": str(src) if src else None,
|
||||
}
|
||||
)
|
||||
return Block(
|
||||
type=BlockType.IMAGE,
|
||||
text=caption or describe_visual(ocr_text, visual_kind, image_id or "image"),
|
||||
image_id=image_id,
|
||||
image_path=image_path,
|
||||
ocr_text=ocr_text,
|
||||
meta=meta,
|
||||
)
|
||||
|
||||
|
||||
def _blocks_from_content_list(content_list: list[dict[str, Any]], json_path: Path, assets_dir: Path) -> list[Block]:
|
||||
blocks: list[Block] = []
|
||||
base_dir = json_path.parent
|
||||
|
||||
for item in content_list:
|
||||
kind = _item_type(item)
|
||||
if kind in _SKIP_MINERU_TYPES:
|
||||
continue
|
||||
meta = _meta(item)
|
||||
img_path = _image_path_text(item)
|
||||
|
||||
if kind != "table" and (
|
||||
kind in _IMAGE_KINDS or (img_path and kind not in {"text", "title", "heading", "list"})
|
||||
):
|
||||
visual = "图表" if kind in {"chart", "diagram"} else "图片"
|
||||
image_block = _build_image_block(item, base_dir, assets_dir, visual_kind=visual)
|
||||
if image_block:
|
||||
blocks.append(image_block)
|
||||
continue
|
||||
# Chart/image without a resolvable asset: fall through if there is caption text.
|
||||
|
||||
if kind == "table":
|
||||
markdown = _table_markdown(item)
|
||||
src = _resolve_asset(img_path, base_dir) if img_path else None
|
||||
image_id, image_path = _copy_asset(src, assets_dir)
|
||||
ocr_text = _ocr_from_item(item, image_path) if image_path else ""
|
||||
if not markdown and not image_path:
|
||||
continue
|
||||
caption = _text_value(item)
|
||||
if caption:
|
||||
meta["caption"] = caption
|
||||
if src:
|
||||
meta["source_image_path"] = str(src)
|
||||
if image_path:
|
||||
meta["crop_path"] = image_path
|
||||
blocks.append(
|
||||
Block(
|
||||
type=BlockType.TABLE,
|
||||
markdown=markdown,
|
||||
text=caption,
|
||||
image_id=image_id,
|
||||
image_path=image_path,
|
||||
ocr_text=ocr_text,
|
||||
meta=meta,
|
||||
)
|
||||
)
|
||||
continue
|
||||
|
||||
if kind == "code":
|
||||
image_block = _build_image_block(item, base_dir, assets_dir, visual_kind="代码")
|
||||
if image_block:
|
||||
blocks.append(image_block)
|
||||
continue
|
||||
code_text = _text_value(item)
|
||||
if code_text:
|
||||
blocks.append(Block(type=BlockType.PARAGRAPH, text=code_text, meta=meta))
|
||||
continue
|
||||
|
||||
if kind in {"page_footnote", "footnote", "ref_text"}:
|
||||
note = _text_value(item)
|
||||
if note:
|
||||
meta["is_footnote"] = True
|
||||
blocks.append(Block(type=BlockType.PARAGRAPH, text=note, meta=meta))
|
||||
continue
|
||||
|
||||
text = _text_value(item)
|
||||
if not text:
|
||||
# Last resort: unknown typed asset with an image should not be dropped.
|
||||
if img_path:
|
||||
image_block = _build_image_block(item, base_dir, assets_dir)
|
||||
if image_block:
|
||||
blocks.append(image_block)
|
||||
continue
|
||||
level = item.get("text_level") or item.get("level")
|
||||
try:
|
||||
level_int = int(level)
|
||||
except (TypeError, ValueError):
|
||||
level_int = 0
|
||||
if kind in {"title", "heading"} or level_int > 0:
|
||||
meta["source_heading"] = True
|
||||
meta["source_heading_level"] = max(level_int, 1)
|
||||
blocks.append(Block(type=BlockType.HEADING, text=text, level=max(level_int, 1), meta=meta))
|
||||
else:
|
||||
blocks.append(Block(type=BlockType.PARAGRAPH, text=text, meta=meta))
|
||||
|
||||
return blocks
|
||||
|
||||
|
||||
def parse_pdf_with_mineru(path: Path, assets_dir: Path) -> list[Block] | None:
|
||||
"""Return MinerU blocks when available; otherwise None for fallback."""
|
||||
output_dir = assets_dir / "_mineru"
|
||||
if not _run_mineru(path, output_dir):
|
||||
return None
|
||||
|
||||
content_json = _find_content_list(output_dir)
|
||||
if not content_json:
|
||||
return None
|
||||
data = _read_json(content_json)
|
||||
if not isinstance(data, list):
|
||||
return None
|
||||
blocks = _blocks_from_content_list(data, content_json, assets_dir)
|
||||
return blocks or None
|
||||
@@ -0,0 +1,164 @@
|
||||
"""Convert Office documents to PDF for downstream parsing."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import platform
|
||||
import shutil
|
||||
import subprocess
|
||||
from pathlib import Path
|
||||
|
||||
_PPT_EXTENSIONS = {".ppt", ".pptx", ".ppsx"}
|
||||
_WORD_EXTENSIONS = {".doc", ".docx"}
|
||||
|
||||
|
||||
def _find_soffice() -> Path | None:
|
||||
for candidate in (
|
||||
"soffice",
|
||||
r"C:\Program Files\LibreOffice\program\soffice.exe",
|
||||
r"C:\Program Files (x86)\LibreOffice\program\soffice.exe",
|
||||
"/usr/bin/libreoffice",
|
||||
"/usr/bin/soffice",
|
||||
):
|
||||
if candidate in ("soffice", "libreoffice"):
|
||||
found = shutil.which(candidate)
|
||||
if found:
|
||||
return Path(found)
|
||||
elif Path(candidate).is_file():
|
||||
return Path(candidate)
|
||||
return None
|
||||
|
||||
|
||||
def _convert_via_libreoffice(source: Path, out_dir: Path) -> Path:
|
||||
soffice = _find_soffice()
|
||||
if soffice is None:
|
||||
raise RuntimeError("LibreOffice (soffice) not found")
|
||||
|
||||
out_dir.mkdir(parents=True, exist_ok=True)
|
||||
subprocess.run(
|
||||
[
|
||||
str(soffice),
|
||||
"--headless",
|
||||
"--convert-to",
|
||||
"pdf",
|
||||
"--outdir",
|
||||
str(out_dir),
|
||||
str(source.resolve()),
|
||||
],
|
||||
check=True,
|
||||
capture_output=True,
|
||||
text=True,
|
||||
timeout=180,
|
||||
)
|
||||
pdf_path = out_dir / f"{source.stem}.pdf"
|
||||
if not pdf_path.is_file():
|
||||
raise RuntimeError(f"LibreOffice did not produce PDF: {pdf_path}")
|
||||
return pdf_path
|
||||
|
||||
|
||||
def _convert_via_powerpoint(source: Path, out_dir: Path) -> Path:
|
||||
if platform.system() != "Windows":
|
||||
raise RuntimeError("PowerPoint COM conversion is only available on Windows")
|
||||
|
||||
out_dir.mkdir(parents=True, exist_ok=True)
|
||||
pdf_path = out_dir / f"{source.stem}.pdf"
|
||||
src = str(source.resolve())
|
||||
dst = str(pdf_path.resolve())
|
||||
script = f"""
|
||||
$ErrorActionPreference = 'Stop'
|
||||
$pp = New-Object -ComObject PowerPoint.Application
|
||||
try {{
|
||||
$pres = $pp.Presentations.Open('{src.replace("'", "''")}', $true, $true, $false)
|
||||
try {{
|
||||
$pres.SaveAs('{dst.replace("'", "''")}', 32)
|
||||
}} finally {{
|
||||
$pres.Close()
|
||||
}}
|
||||
}} finally {{
|
||||
$pp.Quit()
|
||||
}}
|
||||
"""
|
||||
subprocess.run(
|
||||
["powershell", "-NoProfile", "-NonInteractive", "-Command", script],
|
||||
check=True,
|
||||
capture_output=True,
|
||||
text=True,
|
||||
timeout=180,
|
||||
)
|
||||
if not pdf_path.is_file():
|
||||
raise RuntimeError(f"PowerPoint did not produce PDF: {pdf_path}")
|
||||
return pdf_path
|
||||
|
||||
|
||||
def _convert_via_word(source: Path, out_dir: Path) -> Path:
|
||||
if platform.system() != "Windows":
|
||||
raise RuntimeError("Word COM conversion is only available on Windows")
|
||||
|
||||
out_dir.mkdir(parents=True, exist_ok=True)
|
||||
pdf_path = out_dir / f"{source.stem}.pdf"
|
||||
src = str(source.resolve())
|
||||
dst = str(pdf_path.resolve())
|
||||
script = f"""
|
||||
$ErrorActionPreference = 'Stop'
|
||||
$word = New-Object -ComObject Word.Application
|
||||
$word.Visible = $false
|
||||
try {{
|
||||
$doc = $word.Documents.Open('{src.replace("'", "''")}', $false, $true)
|
||||
try {{
|
||||
$doc.SaveAs2('{dst.replace("'", "''")}', 17)
|
||||
}} finally {{
|
||||
$doc.Close([ref]$false)
|
||||
}}
|
||||
}} finally {{
|
||||
$word.Quit()
|
||||
}}
|
||||
"""
|
||||
subprocess.run(
|
||||
["powershell", "-NoProfile", "-NonInteractive", "-Command", script],
|
||||
check=True,
|
||||
capture_output=True,
|
||||
text=True,
|
||||
timeout=180,
|
||||
)
|
||||
if not pdf_path.is_file():
|
||||
raise RuntimeError(f"Word did not produce PDF: {pdf_path}")
|
||||
return pdf_path
|
||||
|
||||
|
||||
def convert_to_pdf(source: Path, out_dir: Path) -> Path:
|
||||
"""Convert an Office file to PDF. Tries LibreOffice, then format-specific COM on Windows."""
|
||||
source = source.resolve()
|
||||
if not source.is_file():
|
||||
raise FileNotFoundError(source)
|
||||
|
||||
errors: list[str] = []
|
||||
try:
|
||||
return _convert_via_libreoffice(source, out_dir)
|
||||
except Exception as exc: # noqa: BLE001 — collect and try next backend
|
||||
errors.append(f"libreoffice: {exc}")
|
||||
|
||||
ext = source.suffix.lower()
|
||||
fallbacks: list = []
|
||||
if ext in _PPT_EXTENSIONS:
|
||||
fallbacks.append(_convert_via_powerpoint)
|
||||
elif ext in _WORD_EXTENSIONS:
|
||||
fallbacks.append(_convert_via_word)
|
||||
|
||||
for converter in fallbacks:
|
||||
try:
|
||||
return converter(source, out_dir)
|
||||
except Exception as exc: # noqa: BLE001
|
||||
errors.append(f"{converter.__name__}: {exc}")
|
||||
|
||||
detail = "; ".join(errors) if errors else "no converter available"
|
||||
raise RuntimeError(
|
||||
f"Failed to convert {source.name} to PDF. "
|
||||
f"Install LibreOffice or Microsoft Office. Details: {detail}"
|
||||
)
|
||||
|
||||
|
||||
def is_presentation(path: Path) -> bool:
|
||||
return path.suffix.lower() in _PPT_EXTENSIONS
|
||||
|
||||
|
||||
def is_word_document(path: Path) -> bool:
|
||||
return path.suffix.lower() in _WORD_EXTENSIONS
|
||||
@@ -0,0 +1,5 @@
|
||||
"""PyMuPDF-based PDF parsing pipeline."""
|
||||
|
||||
from rag_cut.parsers.pdf.pipeline import parse_pdf
|
||||
|
||||
__all__ = ["parse_pdf"]
|
||||
@@ -0,0 +1,349 @@
|
||||
"""Page rendering and layout analysis."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import re
|
||||
from dataclasses import dataclass, field
|
||||
from typing import Any
|
||||
|
||||
import fitz
|
||||
|
||||
from rag_cut.parsers.pdf.tables import looks_like_table
|
||||
|
||||
|
||||
_NUMBERED_LINE_RE = re.compile(
|
||||
r"^\s*(\d+(?:\.\d+)*)(?:\.|.)?\s*([A-Za-z0-9\u4e00-\u9fff].{2,})$"
|
||||
)
|
||||
|
||||
|
||||
@dataclass
|
||||
class TextLine:
|
||||
x0: float
|
||||
y0: float
|
||||
x1: float
|
||||
y1: float
|
||||
text: str
|
||||
font_size: float
|
||||
|
||||
|
||||
@dataclass
|
||||
class LayoutRegion:
|
||||
x0: float
|
||||
y0: float
|
||||
x1: float
|
||||
y1: float
|
||||
kind: str # text | table | image
|
||||
data: dict[str, Any] = field(default_factory=dict)
|
||||
|
||||
|
||||
@dataclass
|
||||
class PageLayout:
|
||||
page_index: int
|
||||
page_width: float
|
||||
page_height: float
|
||||
body_font_size: float
|
||||
regions: list[LayoutRegion] = field(default_factory=list)
|
||||
|
||||
|
||||
def render_page(page: fitz.Page, zoom: float = 2.0) -> fitz.Pixmap:
|
||||
"""Render page to pixmap for region cropping and OCR."""
|
||||
return page.get_pixmap(matrix=fitz.Matrix(zoom, zoom), alpha=False)
|
||||
|
||||
|
||||
def _median_body_size(text_dict: dict) -> float:
|
||||
sizes: list[float] = []
|
||||
for block in text_dict.get("blocks", []):
|
||||
if block.get("type") != 0:
|
||||
continue
|
||||
for line in block.get("lines", []):
|
||||
for span in line.get("spans", []):
|
||||
sizes.append(span.get("size", 12))
|
||||
return sorted(sizes)[len(sizes) // 2] if sizes else 12
|
||||
|
||||
|
||||
def _collect_text_lines(page: fitz.Page, body_size: float) -> list[TextLine]:
|
||||
text_dict = page.get_text("dict")
|
||||
lines: list[TextLine] = []
|
||||
for block in text_dict.get("blocks", []):
|
||||
if block.get("type") != 0:
|
||||
continue
|
||||
for line in block.get("lines", []):
|
||||
text = "".join(span.get("text", "") for span in line.get("spans", [])).strip()
|
||||
if not text:
|
||||
continue
|
||||
x0, y0, x1, y1 = line["bbox"]
|
||||
max_size = body_size
|
||||
for span in line.get("spans", []):
|
||||
max_size = max(max_size, span.get("size", body_size))
|
||||
lines.append(TextLine(x0=x0, y0=y0, x1=x1, y1=y1, text=text, font_size=max_size))
|
||||
return lines
|
||||
|
||||
|
||||
def _detect_columns(
|
||||
items: list[tuple[float, float, float, float]],
|
||||
page_width: float,
|
||||
) -> list[tuple[float, float, float, float]]:
|
||||
if not items:
|
||||
return items
|
||||
mid = page_width / 2
|
||||
left = [b for b in items if (b[0] + b[2]) / 2 < mid]
|
||||
right = [b for b in items if (b[0] + b[2]) / 2 >= mid]
|
||||
if len(left) >= 2 and len(right) >= 2:
|
||||
left.sort(key=lambda b: (b[1], b[0]))
|
||||
right.sort(key=lambda b: (b[1], b[0]))
|
||||
return left + right
|
||||
return sorted(items, key=lambda b: (b[1], b[0]))
|
||||
|
||||
|
||||
def _sort_reading_order(
|
||||
items: list[tuple[float, float, float, float]],
|
||||
page_width: float,
|
||||
) -> list[tuple[float, float, float, float]]:
|
||||
"""Sort page boxes in a human reading order, preserving two-column flows."""
|
||||
if not items:
|
||||
return []
|
||||
|
||||
mid = page_width / 2
|
||||
full_width: list[tuple[float, float, float, float]] = []
|
||||
column_items: list[tuple[float, float, float, float]] = []
|
||||
for box in items:
|
||||
width = box[2] - box[0]
|
||||
spans_mid = box[0] < mid < box[2]
|
||||
if width >= page_width * 0.60 or (spans_mid and width >= page_width * 0.35):
|
||||
full_width.append(box)
|
||||
else:
|
||||
column_items.append(box)
|
||||
|
||||
left = [b for b in column_items if (b[0] + b[2]) / 2 < mid]
|
||||
right = [b for b in column_items if (b[0] + b[2]) / 2 >= mid]
|
||||
if len(left) < 2 or len(right) < 2:
|
||||
return sorted(items, key=lambda b: (b[1], b[0]))
|
||||
|
||||
full_width.sort(key=lambda b: (b[1], b[0]))
|
||||
ordered: list[tuple[float, float, float, float]] = []
|
||||
segment_top = float("-inf")
|
||||
|
||||
def add_columns_between(top: float, bottom: float) -> None:
|
||||
segment = [b for b in column_items if b[1] >= top and b[1] < bottom]
|
||||
segment_left = sorted([b for b in segment if (b[0] + b[2]) / 2 < mid], key=lambda b: (b[1], b[0]))
|
||||
segment_right = sorted([b for b in segment if (b[0] + b[2]) / 2 >= mid], key=lambda b: (b[1], b[0]))
|
||||
ordered.extend(segment_left)
|
||||
ordered.extend(segment_right)
|
||||
|
||||
for box in full_width:
|
||||
add_columns_between(segment_top, box[1])
|
||||
ordered.append(box)
|
||||
segment_top = box[3]
|
||||
add_columns_between(segment_top, float("inf"))
|
||||
|
||||
seen: set[tuple[float, float, float, float]] = set(ordered)
|
||||
ordered.extend(b for b in sorted(items, key=lambda b: (b[1], b[0])) if b not in seen)
|
||||
return ordered
|
||||
|
||||
|
||||
def _rect_overlap(a: tuple[float, float, float, float], b: tuple[float, float, float, float]) -> float:
|
||||
x0 = max(a[0], b[0])
|
||||
y0 = max(a[1], b[1])
|
||||
x1 = min(a[2], b[2])
|
||||
y1 = min(a[3], b[3])
|
||||
if x1 <= x0 or y1 <= y0:
|
||||
return 0.0
|
||||
inter = (x1 - x0) * (y1 - y0)
|
||||
area_a = max((a[2] - a[0]) * (a[3] - a[1]), 1e-6)
|
||||
return inter / area_a
|
||||
|
||||
|
||||
def _center_inside(inner: tuple[float, float, float, float], outer: tuple[float, float, float, float]) -> bool:
|
||||
cx = (inner[0] + inner[2]) / 2
|
||||
cy = (inner[1] + inner[3]) / 2
|
||||
return outer[0] <= cx <= outer[2] and outer[1] <= cy <= outer[3]
|
||||
|
||||
|
||||
def _horizontal_overlap_ratio(a: TextLine, b: TextLine) -> float:
|
||||
overlap = min(a.x1, b.x1) - max(a.x0, b.x0)
|
||||
if overlap <= 0:
|
||||
return 0.0
|
||||
return overlap / max(min(a.x1 - a.x0, b.x1 - b.x0), 1e-6)
|
||||
|
||||
|
||||
def _line_on_image(
|
||||
line: TextLine,
|
||||
image_boxes: list[tuple[float, float, float, float]],
|
||||
large_image_boxes: list[tuple[float, float, float, float]],
|
||||
) -> bool:
|
||||
# Never drop numbered section titles even if they sit near a screenshot.
|
||||
if _NUMBERED_LINE_RE.match(line.text.strip()):
|
||||
return False
|
||||
bbox = (line.x0, line.y0, line.x1, line.y1)
|
||||
# Large background/screenshot: require near-full coverage of the line, not
|
||||
# merely center-inside (which wiped text sitting in margins of wide figures).
|
||||
if large_image_boxes and any(
|
||||
_center_inside(bbox, box) and _rect_overlap(bbox, box) >= 0.85 for box in large_image_boxes
|
||||
):
|
||||
return True
|
||||
return any(_rect_overlap(bbox, box) >= 0.55 for box in image_boxes)
|
||||
|
||||
|
||||
def _area(box: tuple[float, float, float, float]) -> float:
|
||||
return max(box[2] - box[0], 0.0) * max(box[3] - box[1], 0.0)
|
||||
|
||||
|
||||
def _filter_nested_image_regions(regions: list[LayoutRegion]) -> list[LayoutRegion]:
|
||||
"""Drop image fragments that are already contained in a larger screenshot."""
|
||||
result: list[LayoutRegion] = []
|
||||
boxes = [(r.x0, r.y0, r.x1, r.y1) for r in regions]
|
||||
for region, box in zip(regions, boxes):
|
||||
box_area = _area(box)
|
||||
nested = False
|
||||
for other in boxes:
|
||||
other_area = _area(other)
|
||||
if other == box or other_area <= box_area * 1.5:
|
||||
continue
|
||||
if _center_inside(box, other) and _rect_overlap(box, other) >= 0.85:
|
||||
nested = True
|
||||
break
|
||||
if not nested:
|
||||
result.append(region)
|
||||
return result
|
||||
|
||||
|
||||
def _merge_lines_to_paragraphs(lines: list[TextLine], page_width: float) -> list[TextLine]:
|
||||
if not lines:
|
||||
return []
|
||||
|
||||
ordered_boxes = _sort_reading_order([(ln.x0, ln.y0, ln.x1, ln.y1) for ln in lines], page_width)
|
||||
order = {(b[0], b[1], b[2], b[3]): i for i, b in enumerate(ordered_boxes)}
|
||||
ordered = sorted(lines, key=lambda ln: order.get((ln.x0, ln.y0, ln.x1, ln.y1), (ln.y0, ln.x0)))
|
||||
|
||||
paragraphs: list[TextLine] = []
|
||||
current = ordered[0]
|
||||
for nxt in ordered[1:]:
|
||||
vgap = nxt.y0 - current.y1
|
||||
line_h = max(current.y1 - current.y0, nxt.y1 - nxt.y0, 8.0)
|
||||
size_gap = abs(current.font_size - nxt.font_size)
|
||||
size_ratio = max(current.font_size, nxt.font_size) / max(
|
||||
min(current.font_size, nxt.font_size), 1e-6
|
||||
)
|
||||
# Keep title vs body separate: small absolute gap is enough when ratio is large.
|
||||
same_style = size_gap <= 1.0 and size_ratio <= 1.15
|
||||
either_numbered = bool(
|
||||
_NUMBERED_LINE_RE.match(current.text.strip()) or _NUMBERED_LINE_RE.match(nxt.text.strip())
|
||||
)
|
||||
if (
|
||||
same_style
|
||||
and not either_numbered
|
||||
and vgap <= line_h * 2.2
|
||||
and _horizontal_overlap_ratio(current, nxt) >= 0.25
|
||||
):
|
||||
joiner = "" if current.text.endswith("-") or current.text.endswith(" ") else " "
|
||||
current = TextLine(
|
||||
x0=min(current.x0, nxt.x0),
|
||||
y0=current.y0,
|
||||
x1=max(current.x1, nxt.x1),
|
||||
y1=nxt.y1,
|
||||
text=f"{current.text}{joiner}{nxt.text}",
|
||||
font_size=max(current.font_size, nxt.font_size),
|
||||
)
|
||||
else:
|
||||
paragraphs.append(current)
|
||||
current = nxt
|
||||
paragraphs.append(current)
|
||||
return paragraphs
|
||||
|
||||
|
||||
def analyze_page_layout(page: fitz.Page, page_index: int) -> PageLayout:
|
||||
"""Layout analysis: text paragraphs, table regions, image regions."""
|
||||
text_dict = page.get_text("dict")
|
||||
body_size = _median_body_size(text_dict)
|
||||
page_width = page.rect.width
|
||||
page_height = page.rect.height
|
||||
page_area = page_width * page_height
|
||||
|
||||
table_regions: list[LayoutRegion] = []
|
||||
try:
|
||||
table_finder = page.find_tables()
|
||||
for idx, table in enumerate(table_finder.tables):
|
||||
bbox = table.bbox
|
||||
rows = table.extract() or []
|
||||
if not looks_like_table(rows):
|
||||
continue
|
||||
table_regions.append(
|
||||
LayoutRegion(
|
||||
x0=bbox[0],
|
||||
y0=bbox[1],
|
||||
x1=bbox[2],
|
||||
y1=bbox[3],
|
||||
kind="table",
|
||||
data={"rows": rows, "table_index": idx, "source": "pymupdf"},
|
||||
)
|
||||
)
|
||||
except Exception:
|
||||
pass
|
||||
|
||||
image_regions: list[LayoutRegion] = []
|
||||
for img_info in page.get_images(full=True):
|
||||
xref = img_info[0]
|
||||
try:
|
||||
rects = page.get_image_rects(xref)
|
||||
except Exception:
|
||||
rects = []
|
||||
if not rects:
|
||||
continue
|
||||
for rect_idx, rect in enumerate(rects):
|
||||
image_regions.append(
|
||||
LayoutRegion(
|
||||
x0=rect.x0,
|
||||
y0=rect.y0,
|
||||
x1=rect.x1,
|
||||
y1=rect.y1,
|
||||
kind="image",
|
||||
data={"xref": xref, "rect_index": rect_idx},
|
||||
)
|
||||
)
|
||||
image_regions = _filter_nested_image_regions(image_regions)
|
||||
|
||||
image_boxes = [(r.x0, r.y0, r.x1, r.y1) for r in image_regions]
|
||||
large_image_boxes = [
|
||||
box
|
||||
for box in image_boxes
|
||||
if (box[2] - box[0]) * (box[3] - box[1]) >= page_area * 0.12
|
||||
]
|
||||
table_boxes = [(r.x0, r.y0, r.x1, r.y1) for r in table_regions]
|
||||
|
||||
raw_lines = _collect_text_lines(page, body_size)
|
||||
filtered_lines = [
|
||||
ln
|
||||
for ln in raw_lines
|
||||
if not _line_on_image(ln, image_boxes, large_image_boxes)
|
||||
and not any(_rect_overlap((ln.x0, ln.y0, ln.x1, ln.y1), box) >= 0.55 for box in table_boxes)
|
||||
]
|
||||
paragraphs = _merge_lines_to_paragraphs(filtered_lines, page_width)
|
||||
|
||||
text_regions: list[LayoutRegion] = []
|
||||
for para in paragraphs:
|
||||
text_regions.append(
|
||||
LayoutRegion(
|
||||
x0=para.x0,
|
||||
y0=para.y0,
|
||||
x1=para.x1,
|
||||
y1=para.y1,
|
||||
kind="text",
|
||||
data={"text": para.text, "font_size": para.font_size},
|
||||
)
|
||||
)
|
||||
|
||||
regions = text_regions + table_regions + image_regions
|
||||
ordered_boxes = _sort_reading_order(
|
||||
[(r.x0, r.y0, r.x1, r.y1) for r in regions],
|
||||
page_width,
|
||||
)
|
||||
order = {box: i for i, box in enumerate(ordered_boxes)}
|
||||
regions.sort(key=lambda r: order.get((r.x0, r.y0, r.x1, r.y1), len(order)))
|
||||
|
||||
return PageLayout(
|
||||
page_index=page_index,
|
||||
page_width=page_width,
|
||||
page_height=page_height,
|
||||
body_font_size=body_size,
|
||||
regions=regions,
|
||||
)
|
||||
@@ -0,0 +1,446 @@
|
||||
"""Filter page headers, footers, page numbers and other margin noise from PDF blocks."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import re
|
||||
from collections import defaultdict
|
||||
|
||||
from rag_cut.models import Block, BlockType
|
||||
|
||||
HEADER_ZONE_RATIO = 0.12
|
||||
FOOTER_ZONE_RATIO = 0.10
|
||||
RUNNING_HEADER_MIN_PAGES = 3
|
||||
RUNNING_HEADER_PAGE_RATIO = 0.5
|
||||
MAX_RUNNING_HEADER_LEN = 48
|
||||
MIN_RUNNING_HEADER_LEN = 3
|
||||
# Drop decorative fragments (icons/logos) from layout detectors like MinerU.
|
||||
MIN_IMAGE_SIDE = 40.0
|
||||
MIN_IMAGE_AREA = 1600.0
|
||||
# Body paragraphs shorter than this can still exit a TOC zone when they
|
||||
# clearly are not directory entries (keeps in-section catalogs like 形態指標).
|
||||
TOC_BODY_EXIT_CHARS = 48
|
||||
TOC_PAGE_ENTRY_RATIO = 0.55
|
||||
TOC_PAGE_MIN_ENTRIES = 3
|
||||
|
||||
_PAGE_NUM_RE = re.compile(r"^\d{1,4}$")
|
||||
_NUMBERED_SECTION_RE = re.compile(
|
||||
r"^\s*(\d+(?:\.\d+)*)(?:\.|.)?\s*([A-Za-z0-9\u4e00-\u9fff][A-Za-z0-9\u4e00-\u9fff&/ \-_::]{2,})\s*$"
|
||||
)
|
||||
# Cover-page / front-matter directory headings only (exact-ish).
|
||||
_TOC_TITLE_RE = re.compile(
|
||||
r"^\s*(?:"
|
||||
r"contents|table\s+of\s+contents|toc|"
|
||||
r"\u76ee\u5f55|\u76ee\u9304|\u76ee\u6b21|" # 目录 / 目錄 / 目次
|
||||
r"\u7ae0\u8282\u76ee\u5f55|\u7ae0\u7bc0\u76ee\u9304|" # 章节目录 / 章節目錄
|
||||
r"list\s+of\s+(?:figures|tables|contents)"
|
||||
r")[\s.::·•…-]*$",
|
||||
re.I,
|
||||
)
|
||||
_DOT_LEADER_RE = re.compile(r"(?:\.{2,}|\u2026{2,}|\u00b7{2,}|\u2022{2,})")
|
||||
# Classic TOC line: title …… 12 / 1. Login ..... 3
|
||||
_TOC_ENTRY_LINE_RE = re.compile(
|
||||
r"^\s*.{1,120}?"
|
||||
r"(?:"
|
||||
r"(?:\.{2,}|\u2026{2,}|\u00b7{2,}|\s{2,})"
|
||||
r"\s*\d{1,4}"
|
||||
r"|"
|
||||
r"(?:\.{2,}|\u2026+)\s*\d{1,4}"
|
||||
r")"
|
||||
r"\s*$"
|
||||
)
|
||||
# Numbered entry with trailing page: "1.1 Account Status 12"
|
||||
_TOC_NUMBERED_PAGE_RE = re.compile(
|
||||
r"^\s*\d+(?:\.\d+)*(?:[\..]\s*|\s+)"
|
||||
r".{1,100}?"
|
||||
r"(?:\s{2,}|\s+)"
|
||||
r"\d{1,4}\s*$"
|
||||
)
|
||||
_MD_TOC_LINK_RE = re.compile(r"^\s*[-*+]\s+\[[^\]]+\]\([^)]+\)\s*$")
|
||||
|
||||
|
||||
def _looks_like_numbered_section(text: str) -> bool:
|
||||
match = _NUMBERED_SECTION_RE.match(text.strip())
|
||||
return bool(match and len(match.group(2).strip()) >= 3)
|
||||
|
||||
|
||||
def _norm_text(text: str) -> str:
|
||||
return " ".join((text or "").split())
|
||||
|
||||
|
||||
def is_toc_title_text(text: str) -> bool:
|
||||
"""True for standalone 目录 / Contents / TOC headings."""
|
||||
return bool(_TOC_TITLE_RE.match(_norm_text(text)))
|
||||
|
||||
|
||||
def is_toc_entry_line(text: str) -> bool:
|
||||
"""True for a single TOC row (leaders / trailing page number / md link)."""
|
||||
stripped = (text or "").strip()
|
||||
if not stripped or len(stripped) > 200:
|
||||
return False
|
||||
if is_toc_title_text(stripped):
|
||||
return False
|
||||
if _MD_TOC_LINK_RE.match(stripped):
|
||||
return True
|
||||
if _DOT_LEADER_RE.search(stripped) and re.search(r"\d\s*$", stripped):
|
||||
return True
|
||||
if _TOC_ENTRY_LINE_RE.match(stripped):
|
||||
return True
|
||||
if _TOC_NUMBERED_PAGE_RE.match(stripped):
|
||||
return True
|
||||
return False
|
||||
|
||||
|
||||
def is_toc_noise_text(text: str) -> bool:
|
||||
"""True if the whole block text is a TOC title or TOC entries."""
|
||||
stripped = (text or "").strip()
|
||||
if not stripped:
|
||||
return False
|
||||
if is_toc_title_text(stripped):
|
||||
return True
|
||||
lines = [ln.strip() for ln in stripped.splitlines() if ln.strip()]
|
||||
if not lines:
|
||||
return False
|
||||
if len(lines) == 1:
|
||||
return is_toc_entry_line(lines[0])
|
||||
hits = sum(1 for ln in lines if is_toc_entry_line(ln) or is_toc_title_text(ln))
|
||||
return hits >= max(2, int(len(lines) * 0.6))
|
||||
|
||||
|
||||
def _is_toc_zone_exit_block(block: Block) -> bool:
|
||||
"""Substantial body / media ends a front-matter TOC stretch."""
|
||||
if block.type in {BlockType.IMAGE, BlockType.TABLE}:
|
||||
return True
|
||||
text = (block.text or block.markdown or "").strip()
|
||||
if not text or is_toc_noise_text(text):
|
||||
return False
|
||||
# Real section start right after TOC (no page-number trailer).
|
||||
if _looks_like_numbered_section(text) and not is_toc_entry_line(text):
|
||||
return True
|
||||
if len(text) >= TOC_BODY_EXIT_CHARS and not is_toc_entry_line(text):
|
||||
return True
|
||||
return False
|
||||
|
||||
|
||||
def _toc_heavy_pages(blocks: list[Block]) -> set[int]:
|
||||
"""Pages dominated by directory lines are dropped wholesale (text only)."""
|
||||
by_page: dict[int, list[Block]] = defaultdict(list)
|
||||
for block in blocks:
|
||||
if block.type in {BlockType.IMAGE, BlockType.TABLE}:
|
||||
continue
|
||||
page = block.meta.get("page")
|
||||
if page is None:
|
||||
continue
|
||||
try:
|
||||
page_key = int(page)
|
||||
except (TypeError, ValueError):
|
||||
continue
|
||||
by_page[page_key].append(block)
|
||||
|
||||
heavy: set[int] = set()
|
||||
for page_key, page_blocks in by_page.items():
|
||||
texts = [(b.text or b.markdown or "").strip() for b in page_blocks]
|
||||
texts = [t for t in texts if t]
|
||||
if not texts:
|
||||
continue
|
||||
entry_hits = sum(1 for t in texts if is_toc_noise_text(t))
|
||||
has_title = any(is_toc_title_text(t) for t in texts)
|
||||
if entry_hits >= TOC_PAGE_MIN_ENTRIES and entry_hits / len(texts) >= TOC_PAGE_ENTRY_RATIO:
|
||||
heavy.add(page_key)
|
||||
elif has_title and entry_hits >= 1 and entry_hits / len(texts) >= 0.4:
|
||||
heavy.add(page_key)
|
||||
return heavy
|
||||
|
||||
|
||||
def _toc_noise_bottoms(blocks: list[Block]) -> dict[int, float]:
|
||||
"""Lowest TOC text position per page, so real content below it survives."""
|
||||
bottoms: dict[int, float] = {}
|
||||
for block in blocks:
|
||||
if block.type in {BlockType.IMAGE, BlockType.TABLE}:
|
||||
continue
|
||||
text = (block.text or block.markdown or "").strip()
|
||||
if not is_toc_noise_text(text):
|
||||
continue
|
||||
page = block.meta.get("page")
|
||||
bbox = block.meta.get("bbox")
|
||||
if page is None or not isinstance(bbox, (list, tuple)) or len(bbox) < 4:
|
||||
continue
|
||||
try:
|
||||
page_key = int(page)
|
||||
bottom = float(bbox[3])
|
||||
except (TypeError, ValueError):
|
||||
continue
|
||||
bottoms[page_key] = max(bottoms.get(page_key, 0.0), bottom)
|
||||
return bottoms
|
||||
|
||||
|
||||
def filter_toc_blocks(blocks: list[Block]) -> list[Block]:
|
||||
"""Drop document directories (目录 / Contents) — never chunk them.
|
||||
|
||||
Keeps in-section numbered catalogs without page leaders (e.g. 形態指標 list).
|
||||
"""
|
||||
if not blocks:
|
||||
return blocks
|
||||
|
||||
toc_pages = _toc_heavy_pages(blocks)
|
||||
toc_bottoms = _toc_noise_bottoms(blocks)
|
||||
filtered: list[Block] = []
|
||||
in_toc = False
|
||||
|
||||
for block in blocks:
|
||||
page = block.meta.get("page")
|
||||
try:
|
||||
page_key = int(page) if page is not None else None
|
||||
except (TypeError, ValueError):
|
||||
page_key = None
|
||||
|
||||
text = (block.text or block.markdown or "").strip()
|
||||
|
||||
if page_key is not None and page_key in toc_pages and block.type not in {
|
||||
BlockType.IMAGE,
|
||||
BlockType.TABLE,
|
||||
}:
|
||||
bbox = block.meta.get("bbox")
|
||||
toc_bottom = toc_bottoms.get(page_key)
|
||||
if (
|
||||
toc_bottom is None
|
||||
or not isinstance(bbox, (list, tuple))
|
||||
or len(bbox) < 4
|
||||
or float(bbox[1]) <= toc_bottom
|
||||
):
|
||||
continue
|
||||
|
||||
if is_toc_title_text(text):
|
||||
in_toc = True
|
||||
continue
|
||||
|
||||
if in_toc:
|
||||
if _is_toc_zone_exit_block(block):
|
||||
in_toc = False
|
||||
filtered.append(block)
|
||||
continue
|
||||
if is_toc_noise_text(text) or is_toc_entry_line(text):
|
||||
continue
|
||||
# Ambiguous short line right after TOC: treat as first real section.
|
||||
in_toc = False
|
||||
filtered.append(block)
|
||||
continue
|
||||
|
||||
if is_toc_noise_text(text):
|
||||
continue
|
||||
|
||||
filtered.append(block)
|
||||
|
||||
return filtered
|
||||
|
||||
|
||||
def _bbox4(block: Block) -> list[float] | None:
|
||||
bbox = block.meta.get("bbox")
|
||||
if not isinstance(bbox, (list, tuple)) or len(bbox) < 4:
|
||||
return None
|
||||
try:
|
||||
return [float(bbox[0]), float(bbox[1]), float(bbox[2]), float(bbox[3])]
|
||||
except (TypeError, ValueError):
|
||||
return None
|
||||
|
||||
|
||||
def _bbox_area(bbox: list[float]) -> float:
|
||||
return max(bbox[2] - bbox[0], 0.0) * max(bbox[3] - bbox[1], 0.0)
|
||||
|
||||
|
||||
def _center_inside(inner: list[float], outer: list[float]) -> bool:
|
||||
cx = (inner[0] + inner[2]) / 2
|
||||
cy = (inner[1] + inner[3]) / 2
|
||||
return outer[0] <= cx <= outer[2] and outer[1] <= cy <= outer[3]
|
||||
|
||||
|
||||
def _overlap_ratio(inner: list[float], outer: list[float]) -> float:
|
||||
x0 = max(inner[0], outer[0])
|
||||
y0 = max(inner[1], outer[1])
|
||||
x1 = min(inner[2], outer[2])
|
||||
y1 = min(inner[3], outer[3])
|
||||
if x1 <= x0 or y1 <= y0:
|
||||
return 0.0
|
||||
inter = (x1 - x0) * (y1 - y0)
|
||||
return inter / max(_bbox_area(inner), 1e-6)
|
||||
|
||||
|
||||
def is_tiny_image_block(block: Block) -> bool:
|
||||
"""True for tiny image fragments that are usually logos/icons, not content figures."""
|
||||
if block.type != BlockType.IMAGE:
|
||||
return False
|
||||
bbox = _bbox4(block)
|
||||
if not bbox:
|
||||
return False
|
||||
width = bbox[2] - bbox[0]
|
||||
height = bbox[3] - bbox[1]
|
||||
if width <= 0 or height <= 0:
|
||||
return True
|
||||
if width < MIN_IMAGE_SIDE and height < MIN_IMAGE_SIDE:
|
||||
return True
|
||||
return width * height < MIN_IMAGE_AREA
|
||||
|
||||
|
||||
def filter_nested_image_blocks(blocks: list[Block]) -> list[Block]:
|
||||
"""Drop image fragments whose center lies inside a larger same-page image."""
|
||||
image_boxes: list[tuple[int, int, list[float], float]] = []
|
||||
for idx, block in enumerate(blocks):
|
||||
if block.type != BlockType.IMAGE:
|
||||
continue
|
||||
bbox = _bbox4(block)
|
||||
page = block.meta.get("page")
|
||||
if bbox is None or page is None:
|
||||
continue
|
||||
try:
|
||||
page_key = int(page)
|
||||
except (TypeError, ValueError):
|
||||
continue
|
||||
image_boxes.append((idx, page_key, bbox, _bbox_area(bbox)))
|
||||
|
||||
drop: set[int] = set()
|
||||
for idx, page_key, bbox, area in image_boxes:
|
||||
for other_idx, other_page, other_bbox, other_area in image_boxes:
|
||||
if idx == other_idx or page_key != other_page or other_area <= area * 1.5:
|
||||
continue
|
||||
if _center_inside(bbox, other_bbox) and _overlap_ratio(bbox, other_bbox) >= 0.85:
|
||||
drop.add(idx)
|
||||
break
|
||||
|
||||
if not drop:
|
||||
return blocks
|
||||
return [block for idx, block in enumerate(blocks) if idx not in drop]
|
||||
|
||||
|
||||
def _infer_page_heights(blocks: list[Block]) -> dict[int, float]:
|
||||
heights: dict[int, float] = {}
|
||||
for block in blocks:
|
||||
page = block.meta.get("page")
|
||||
if page is None:
|
||||
continue
|
||||
try:
|
||||
page_key = int(page)
|
||||
except (TypeError, ValueError):
|
||||
continue
|
||||
explicit = block.meta.get("page_height")
|
||||
if explicit:
|
||||
heights[page_key] = max(heights.get(page_key, 0), float(explicit))
|
||||
bbox = block.meta.get("bbox")
|
||||
if bbox and len(bbox) >= 4:
|
||||
heights[page_key] = max(heights.get(page_key, 0), float(bbox[3]))
|
||||
return {page: max(height, 1.0) for page, height in heights.items()}
|
||||
|
||||
|
||||
def _page_height(block: Block, heights: dict[int, float]) -> float | None:
|
||||
page = block.meta.get("page")
|
||||
if page is None:
|
||||
explicit = block.meta.get("page_height")
|
||||
return float(explicit) if explicit else None
|
||||
try:
|
||||
page_key = int(page)
|
||||
except (TypeError, ValueError):
|
||||
return block.meta.get("page_height")
|
||||
return heights.get(page_key) or block.meta.get("page_height")
|
||||
|
||||
|
||||
def _in_margin_zone(bbox: list[float], page_height: float, *, header: bool) -> bool:
|
||||
y_mid = (float(bbox[1]) + float(bbox[3])) / 2
|
||||
if header:
|
||||
return y_mid < page_height * HEADER_ZONE_RATIO
|
||||
return y_mid > page_height * (1 - FOOTER_ZONE_RATIO)
|
||||
|
||||
|
||||
def is_margin_noise_block(block: Block, page_height: float | None) -> bool:
|
||||
"""Heuristic margin noise filter for blocks missing explicit MinerU region types."""
|
||||
if block.type == BlockType.IMAGE:
|
||||
return is_tiny_image_block(block)
|
||||
if block.type == BlockType.TABLE:
|
||||
return False
|
||||
|
||||
text = (block.text or "").strip()
|
||||
if not text:
|
||||
return False
|
||||
|
||||
bbox = block.meta.get("bbox")
|
||||
if not page_height or not bbox or len(bbox) < 4:
|
||||
return block.type == BlockType.PARAGRAPH and bool(_PAGE_NUM_RE.match(text))
|
||||
|
||||
in_header = _in_margin_zone(bbox, page_height, header=True)
|
||||
in_footer = _in_margin_zone(bbox, page_height, header=False)
|
||||
if not in_header and not in_footer:
|
||||
return False
|
||||
|
||||
if _PAGE_NUM_RE.match(text):
|
||||
return True
|
||||
|
||||
if block.type != BlockType.PARAGRAPH:
|
||||
return False
|
||||
|
||||
# Numbered section titles often sit at the top of a continued page — keep them.
|
||||
if _looks_like_numbered_section(text):
|
||||
return False
|
||||
|
||||
return len(text) <= MAX_RUNNING_HEADER_LEN
|
||||
|
||||
|
||||
def detect_running_header_texts(blocks: list[Block]) -> set[str]:
|
||||
"""Texts that repeat across many pages are likely running headers/footers.
|
||||
|
||||
Only paragraphs in the header/footer margin bands are considered, so
|
||||
real section headings that happen to repeat are not wiped document-wide.
|
||||
"""
|
||||
pages_by_text: dict[str, set[int]] = defaultdict(set)
|
||||
all_pages: set[int] = set()
|
||||
heights = _infer_page_heights(blocks)
|
||||
|
||||
for block in blocks:
|
||||
if block.type != BlockType.PARAGRAPH:
|
||||
continue
|
||||
text = (block.text or "").strip()
|
||||
if not (MIN_RUNNING_HEADER_LEN <= len(text) <= MAX_RUNNING_HEADER_LEN):
|
||||
continue
|
||||
if _looks_like_numbered_section(text):
|
||||
continue
|
||||
page = block.meta.get("page")
|
||||
if page is None:
|
||||
continue
|
||||
try:
|
||||
page_key = int(page)
|
||||
except (TypeError, ValueError):
|
||||
continue
|
||||
page_height = _page_height(block, heights)
|
||||
bbox = _bbox4(block)
|
||||
if page_height and bbox:
|
||||
in_margin = _in_margin_zone(bbox, float(page_height), header=True) or _in_margin_zone(
|
||||
bbox, float(page_height), header=False
|
||||
)
|
||||
if not in_margin:
|
||||
continue
|
||||
all_pages.add(page_key)
|
||||
pages_by_text[text].add(page_key)
|
||||
|
||||
if len(all_pages) < RUNNING_HEADER_MIN_PAGES:
|
||||
return set()
|
||||
|
||||
threshold = max(RUNNING_HEADER_MIN_PAGES, int(len(all_pages) * RUNNING_HEADER_PAGE_RATIO))
|
||||
return {text for text, pages in pages_by_text.items() if len(pages) >= threshold}
|
||||
|
||||
|
||||
def filter_noise_blocks(blocks: list[Block]) -> list[Block]:
|
||||
"""Remove headers, footers, page numbers, TOC and other repeated margin noise."""
|
||||
if not blocks:
|
||||
return blocks
|
||||
|
||||
heights = _infer_page_heights(blocks)
|
||||
running_headers = detect_running_header_texts(blocks)
|
||||
filtered: list[Block] = []
|
||||
|
||||
for block in blocks:
|
||||
text = (block.text or "").strip()
|
||||
# Never wipe real section headings via running-header equality.
|
||||
if text and text in running_headers and block.type == BlockType.PARAGRAPH:
|
||||
continue
|
||||
page_height = _page_height(block, heights)
|
||||
if is_margin_noise_block(block, float(page_height) if page_height else None):
|
||||
continue
|
||||
filtered.append(block)
|
||||
|
||||
return filter_nested_image_blocks(filter_toc_blocks(filtered))
|
||||
@@ -0,0 +1,57 @@
|
||||
"""Optional OCR for cropped image/table regions."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import io
|
||||
from pathlib import Path
|
||||
|
||||
import fitz
|
||||
|
||||
|
||||
def ocr_pixmap(pix: fitz.Pixmap) -> str:
|
||||
"""Run OCR on a pixmap; returns empty string when OCR is unavailable."""
|
||||
try:
|
||||
import pytesseract
|
||||
from PIL import Image
|
||||
except ImportError:
|
||||
return ""
|
||||
|
||||
try:
|
||||
image = Image.open(io.BytesIO(pix.tobytes("png")))
|
||||
return _ocr_pil(image)
|
||||
except Exception:
|
||||
return ""
|
||||
|
||||
|
||||
def ocr_image_file(path: Path) -> str:
|
||||
try:
|
||||
import pytesseract # noqa: F401
|
||||
from PIL import Image
|
||||
except ImportError:
|
||||
return ""
|
||||
|
||||
try:
|
||||
return _ocr_pil(Image.open(path))
|
||||
except Exception:
|
||||
return ""
|
||||
|
||||
|
||||
def _ocr_pil(image) -> str:
|
||||
import pytesseract
|
||||
|
||||
for lang in ("chi_tra+eng", "chi_sim+eng", "eng"):
|
||||
try:
|
||||
text = pytesseract.image_to_string(image, lang=lang)
|
||||
cleaned = " ".join(text.split())
|
||||
if cleaned:
|
||||
return cleaned
|
||||
except Exception:
|
||||
continue
|
||||
return ""
|
||||
|
||||
|
||||
def describe_visual(ocr_text: str, kind: str, label: str) -> str:
|
||||
"""Lightweight image/table description without an external vision model."""
|
||||
if ocr_text:
|
||||
return f"{kind}:{ocr_text[:300]}"
|
||||
return f"{kind}:{label}"
|
||||
@@ -0,0 +1,213 @@
|
||||
"""End-to-end PyMuPDF PDF pipeline matching the architecture diagram."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
from dataclasses import dataclass
|
||||
from pathlib import Path
|
||||
|
||||
import pdfplumber
|
||||
|
||||
from rag_cut.models import Block
|
||||
from rag_cut.parsers.pdf.layout import (
|
||||
LayoutRegion,
|
||||
PageLayout,
|
||||
_rect_overlap,
|
||||
_sort_reading_order,
|
||||
analyze_page_layout,
|
||||
render_page,
|
||||
)
|
||||
from rag_cut.parsers.pdf.standardize import open_document
|
||||
from rag_cut.parsers.pdf.tables import rows_to_markdown
|
||||
from rag_cut.parsers.pdf.text_extract import extract_text_blocks
|
||||
from rag_cut.parsers.pdf.visual_extract import extract_visual_blocks
|
||||
|
||||
|
||||
@dataclass
|
||||
class _PageItem:
|
||||
y0: float
|
||||
x0: float
|
||||
kind: str
|
||||
block: Block
|
||||
|
||||
|
||||
def _pdfplumber_tables(path: Path) -> dict[int, list[dict]]:
|
||||
"""Extract tables per page with bbox from pdfplumber."""
|
||||
tables_by_page: dict[int, list[dict]] = {}
|
||||
try:
|
||||
with pdfplumber.open(path) as pdf:
|
||||
for i, page in enumerate(pdf.pages):
|
||||
found = []
|
||||
try:
|
||||
for idx, table in enumerate(page.find_tables()):
|
||||
rows = table.extract() or []
|
||||
if not rows:
|
||||
continue
|
||||
bbox = table.bbox
|
||||
found.append(
|
||||
{
|
||||
"rows": rows,
|
||||
"table_index": idx,
|
||||
"source": "pdfplumber",
|
||||
"bbox": list(bbox) if bbox else None,
|
||||
}
|
||||
)
|
||||
except Exception:
|
||||
rows_list = page.extract_tables() or []
|
||||
for idx, rows in enumerate(rows_list):
|
||||
found.append({"rows": rows, "table_index": idx, "source": "pdfplumber", "bbox": None})
|
||||
if found:
|
||||
tables_by_page[i] = found
|
||||
except Exception:
|
||||
pass
|
||||
return tables_by_page
|
||||
|
||||
|
||||
def _inject_pdfplumber_tables(layout: PageLayout, plumber_tables: list[dict]) -> PageLayout:
|
||||
if not plumber_tables:
|
||||
return layout
|
||||
if any(r.kind == "table" for r in layout.regions):
|
||||
return layout
|
||||
|
||||
for item in plumber_tables:
|
||||
rows = item.get("rows") or []
|
||||
md = rows_to_markdown(rows)
|
||||
if not md:
|
||||
continue
|
||||
bbox = item.get("bbox")
|
||||
if bbox and len(bbox) == 4:
|
||||
x0, y0, x1, y1 = bbox
|
||||
else:
|
||||
idx = int(item.get("table_index", 0))
|
||||
x0, y0 = 0, layout.page_height * (idx + 1) / (len(plumber_tables) + 1)
|
||||
x1, y1 = layout.page_width, layout.page_height * (idx + 2) / (len(plumber_tables) + 1)
|
||||
layout.regions.append(
|
||||
LayoutRegion(
|
||||
x0=x0,
|
||||
y0=y0,
|
||||
x1=x1,
|
||||
y1=y1,
|
||||
kind="table",
|
||||
data={
|
||||
"rows": rows,
|
||||
"table_index": item.get("table_index", 0),
|
||||
"source": item.get("source", "pdfplumber"),
|
||||
},
|
||||
)
|
||||
)
|
||||
ordered_boxes = _sort_reading_order(
|
||||
[(r.x0, r.y0, r.x1, r.y1) for r in layout.regions],
|
||||
layout.page_width,
|
||||
)
|
||||
order = {box: i for i, box in enumerate(ordered_boxes)}
|
||||
layout.regions.sort(key=lambda r: order.get((r.x0, r.y0, r.x1, r.y1), len(order)))
|
||||
return layout
|
||||
|
||||
|
||||
def _bbox_key(bbox: list[float] | tuple[float, ...]) -> tuple[float, ...]:
|
||||
return tuple(round(v, 1) for v in bbox)
|
||||
|
||||
|
||||
def _region_box(region: LayoutRegion) -> tuple[float, float, float, float]:
|
||||
return (region.x0, region.y0, region.x1, region.y1)
|
||||
|
||||
|
||||
def _match_block_to_region(
|
||||
region: LayoutRegion,
|
||||
candidates: list[Block],
|
||||
used: set[int],
|
||||
) -> Block | None:
|
||||
"""Match a layout region to a parsed block via exact bbox key or overlap."""
|
||||
region_box = _region_box(region)
|
||||
key = _bbox_key(region_box)
|
||||
|
||||
for block in candidates:
|
||||
if id(block) in used:
|
||||
continue
|
||||
bbox = block.meta.get("bbox")
|
||||
if bbox and _bbox_key(bbox) == key:
|
||||
return block
|
||||
|
||||
best: Block | None = None
|
||||
best_overlap = 0.35
|
||||
for block in candidates:
|
||||
if id(block) in used:
|
||||
continue
|
||||
bbox = block.meta.get("bbox")
|
||||
if not bbox:
|
||||
continue
|
||||
overlap = _rect_overlap(region_box, tuple(bbox))
|
||||
if overlap > best_overlap:
|
||||
best_overlap = overlap
|
||||
best = block
|
||||
return best
|
||||
|
||||
|
||||
def _merge_page_blocks(
|
||||
text_blocks: list[Block],
|
||||
visual_blocks: list[Block],
|
||||
layout: PageLayout,
|
||||
) -> list[Block]:
|
||||
"""Merge text and visual branches in page reading order."""
|
||||
used: set[int] = set()
|
||||
merged: list[_PageItem] = []
|
||||
|
||||
for region in layout.regions:
|
||||
if region.kind == "text":
|
||||
candidates = text_blocks
|
||||
elif region.kind in {"table", "image"}:
|
||||
candidates = visual_blocks
|
||||
else:
|
||||
continue
|
||||
|
||||
block = _match_block_to_region(region, candidates, used)
|
||||
if block is not None:
|
||||
merged.append(_PageItem(y0=region.y0, x0=region.x0, kind=region.kind, block=block))
|
||||
used.add(id(block))
|
||||
|
||||
leftovers: list[_PageItem] = []
|
||||
for block in text_blocks + visual_blocks:
|
||||
if id(block) not in used:
|
||||
bbox = block.meta.get("bbox", [0, 0, 0, 0])
|
||||
leftovers.append(_PageItem(y0=bbox[1], x0=bbox[0], kind=block.type.value, block=block))
|
||||
|
||||
merged.extend(sorted(leftovers, key=lambda it: (it.y0, it.x0)))
|
||||
return [it.block for it in merged]
|
||||
|
||||
|
||||
def parse_pdf(path: Path, assets_dir: Path) -> list[Block]:
|
||||
"""
|
||||
PDF pipeline:
|
||||
1. 文档标准化
|
||||
2. 页面渲染 + 版面分析
|
||||
3. 文本块提取 ∥ 图片/表格区域裁剪 + OCR
|
||||
4. 章节级语义切片(合并两路结果,标注章节上下文)
|
||||
"""
|
||||
assets_dir.mkdir(parents=True, exist_ok=True)
|
||||
renders_dir = assets_dir / "pages"
|
||||
renders_dir.mkdir(parents=True, exist_ok=True)
|
||||
|
||||
doc = open_document(path)
|
||||
plumber_tables = _pdfplumber_tables(path)
|
||||
all_blocks: list[Block] = []
|
||||
chapter_title: str | None = None
|
||||
img_counter = 0
|
||||
|
||||
try:
|
||||
for page_index, page in enumerate(doc):
|
||||
layout = analyze_page_layout(page, page_index)
|
||||
layout = _inject_pdfplumber_tables(layout, plumber_tables.get(page_index, []))
|
||||
|
||||
page_render = render_page(page)
|
||||
render_path = renders_dir / f"page{page_index + 1}.png"
|
||||
page_render.save(str(render_path))
|
||||
|
||||
text_blocks, chapter_title = extract_text_blocks(layout, chapter_title)
|
||||
visual_blocks, img_counter = extract_visual_blocks(
|
||||
page, layout, doc, assets_dir, chapter_title, img_counter
|
||||
)
|
||||
page_blocks = _merge_page_blocks(text_blocks, visual_blocks, layout)
|
||||
all_blocks.extend(page_blocks)
|
||||
finally:
|
||||
doc.close()
|
||||
|
||||
return all_blocks
|
||||
@@ -0,0 +1,16 @@
|
||||
"""Document standardization for PDF input."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
from pathlib import Path
|
||||
|
||||
import fitz
|
||||
|
||||
|
||||
def open_document(path: Path) -> fitz.Document:
|
||||
"""Open and normalize a PDF for downstream layout processing."""
|
||||
doc = fitz.open(path)
|
||||
if doc.is_encrypted and not doc.authenticate(""):
|
||||
doc.close()
|
||||
raise ValueError(f"Encrypted PDF cannot be opened: {path.name}")
|
||||
return doc
|
||||
@@ -0,0 +1,104 @@
|
||||
"""Build rich table blocks from PDF layout regions."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
from pathlib import Path
|
||||
|
||||
import fitz
|
||||
|
||||
from rag_cut.models import Block, BlockType
|
||||
from rag_cut.parsers.pdf.layout import LayoutRegion, PageLayout
|
||||
from rag_cut.parsers.pdf.ocr import describe_visual, ocr_pixmap
|
||||
from rag_cut.parsers.pdf.tables import (
|
||||
detect_header_row_count,
|
||||
extract_table_keywords,
|
||||
header_signature,
|
||||
normalize_rows,
|
||||
rows_to_markdown,
|
||||
split_body_and_footnotes,
|
||||
)
|
||||
|
||||
|
||||
def _crop_region(page: fitz.Page, region: LayoutRegion, zoom: float = 2.0) -> fitz.Pixmap:
|
||||
clip = fitz.Rect(region.x0, region.y0, region.x1, region.y1)
|
||||
return page.get_pixmap(matrix=fitz.Matrix(zoom, zoom), clip=clip, alpha=False)
|
||||
|
||||
|
||||
def _save_pixmap(pix: fitz.Pixmap, path: Path) -> None:
|
||||
if pix.n - pix.alpha > 3:
|
||||
pix = fitz.Pixmap(fitz.csRGB, pix)
|
||||
pix.save(str(path))
|
||||
|
||||
|
||||
def build_table_block(
|
||||
page: fitz.Page,
|
||||
region: LayoutRegion,
|
||||
layout: PageLayout,
|
||||
assets_dir: Path,
|
||||
chapter_title: str | None,
|
||||
) -> Block | None:
|
||||
"""Extract a table block with rows, screenshot, OCR and structural metadata."""
|
||||
raw_rows = region.data.get("rows") or []
|
||||
normalized = normalize_rows(raw_rows)
|
||||
if not normalized:
|
||||
return None
|
||||
|
||||
header_rows = detect_header_row_count(normalized)
|
||||
body_rows, footnote_rows, footnotes = split_body_and_footnotes(normalized, header_rows)
|
||||
data_rows = normalized[:header_rows] + body_rows
|
||||
if not data_rows:
|
||||
return None
|
||||
|
||||
page_no = layout.page_index + 1
|
||||
table_index = int(region.data.get("table_index", 0)) + 1
|
||||
crop_id = f"page{page_no}_table{table_index}.png"
|
||||
crops_dir = assets_dir / "crops"
|
||||
crops_dir.mkdir(parents=True, exist_ok=True)
|
||||
crop_path = crops_dir / crop_id
|
||||
|
||||
ocr_text = ""
|
||||
try:
|
||||
crop_pix = _crop_region(page, region)
|
||||
_save_pixmap(crop_pix, crop_path)
|
||||
ocr_text = ocr_pixmap(crop_pix)
|
||||
except Exception:
|
||||
crop_path_str = ""
|
||||
else:
|
||||
crop_path_str = str(crop_path)
|
||||
|
||||
sig = header_signature(normalized, header_rows)
|
||||
md = rows_to_markdown(normalized, header_rows=header_rows, include_footnotes=footnotes)
|
||||
if not md:
|
||||
return None
|
||||
|
||||
header_text = " ".join(" ".join(r for r in row if r) for row in normalized[:header_rows])
|
||||
keywords = extract_table_keywords(header_text, md, footnotes, ocr_text)
|
||||
|
||||
meta: dict = {
|
||||
"page": page_no,
|
||||
"pages": [page_no],
|
||||
"bbox": [region.x0, region.y0, region.x1, region.y1],
|
||||
"bboxes": [{"page": page_no, "bbox": [region.x0, region.y0, region.x1, region.y1]}],
|
||||
"table_source": region.data.get("source", "pymupdf"),
|
||||
"crop_path": crop_path_str,
|
||||
"rows": normalized,
|
||||
"row_count": len(normalized),
|
||||
"col_count": max((len(r) for r in normalized), default=0),
|
||||
"header_rows": header_rows,
|
||||
"header_signature": [list(r) for r in sig],
|
||||
"footnotes": footnotes,
|
||||
"keywords": keywords,
|
||||
"cross_page": False,
|
||||
}
|
||||
if chapter_title:
|
||||
meta["chapter"] = chapter_title
|
||||
|
||||
return Block(
|
||||
type=BlockType.TABLE,
|
||||
markdown=md,
|
||||
ocr_text=ocr_text,
|
||||
text=describe_visual(ocr_text, "表格", crop_id) if ocr_text else "",
|
||||
image_id=crop_id,
|
||||
image_path=crop_path_str or None,
|
||||
meta=meta,
|
||||
)
|
||||
@@ -0,0 +1,177 @@
|
||||
"""Cross-page table detection and merging."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
from rag_cut.models import Block, BlockType
|
||||
from rag_cut.parsers.pdf.tables import (
|
||||
detect_header_row_count,
|
||||
header_signature,
|
||||
normalize_rows,
|
||||
rows_to_markdown,
|
||||
split_body_and_footnotes,
|
||||
)
|
||||
|
||||
|
||||
def _page(block: Block) -> int | None:
|
||||
page = block.meta.get("page")
|
||||
return int(page) if page is not None else None
|
||||
|
||||
|
||||
def _header_rows(block: Block) -> int:
|
||||
rows = block.meta.get("rows") or []
|
||||
return int(block.meta.get("header_rows") or detect_header_row_count(normalize_rows(rows)) or 1)
|
||||
|
||||
|
||||
def _header_sig(block: Block) -> tuple[tuple[str, ...], ...]:
|
||||
if block.meta.get("header_signature"):
|
||||
raw = block.meta["header_signature"]
|
||||
return tuple(tuple(r) for r in raw)
|
||||
rows = normalize_rows(block.meta.get("rows") or [])
|
||||
return header_signature(rows, _header_rows(block))
|
||||
|
||||
|
||||
def _column_count(block: Block) -> int:
|
||||
rows = normalize_rows(block.meta.get("rows") or [])
|
||||
return max((len(r) for r in rows), default=0)
|
||||
|
||||
|
||||
def _similar_columns(a: Block, b: Block) -> bool:
|
||||
ca, cb = _column_count(a), _column_count(b)
|
||||
if ca == 0 or cb == 0:
|
||||
return False
|
||||
return ca == cb or abs(ca - cb) <= 1
|
||||
|
||||
|
||||
def _repeated_header(rows: list[list[str]], sig: tuple[tuple[str, ...], ...]) -> int:
|
||||
"""Return number of leading rows in `rows` that repeat the header signature."""
|
||||
if not sig:
|
||||
return 0
|
||||
n = len(sig)
|
||||
if len(rows) < n:
|
||||
return 0
|
||||
if header_signature(rows, n) == sig:
|
||||
return n
|
||||
if n == 1 and rows and tuple(rows[0]) == sig[0]:
|
||||
return 1
|
||||
return 0
|
||||
|
||||
|
||||
def _can_merge_continuation(prev: Block, nxt: Block) -> bool:
|
||||
if prev.type != BlockType.TABLE or nxt.type != BlockType.TABLE:
|
||||
return False
|
||||
|
||||
prev_page = _page(prev)
|
||||
nxt_page = _page(nxt)
|
||||
if prev_page is None or nxt_page is None or nxt_page != prev_page + 1:
|
||||
return False
|
||||
if not _similar_columns(prev, nxt):
|
||||
return False
|
||||
|
||||
sig = _header_sig(prev)
|
||||
if not sig:
|
||||
return False
|
||||
|
||||
rows_b = normalize_rows(nxt.meta.get("rows") or [])
|
||||
if not rows_b:
|
||||
return False
|
||||
|
||||
if _repeated_header(rows_b, sig) > 0:
|
||||
return True
|
||||
|
||||
# Continuation without repeated header: similar width and no title on next table
|
||||
if nxt.meta.get("table_title"):
|
||||
return False
|
||||
|
||||
prev_bbox = prev.meta.get("bbox") or []
|
||||
nxt_bbox = nxt.meta.get("bbox") or []
|
||||
if len(prev_bbox) == 4 and len(nxt_bbox) == 4:
|
||||
prev_width = prev_bbox[2] - prev_bbox[0]
|
||||
nxt_width = nxt_bbox[2] - nxt_bbox[0]
|
||||
if prev_width > 0 and abs(prev_width - nxt_width) / prev_width <= 0.15:
|
||||
return True
|
||||
|
||||
return _column_count(prev) == _column_count(nxt)
|
||||
|
||||
|
||||
def _merge_two_tables(prev: Block, nxt: Block) -> Block:
|
||||
rows_a = normalize_rows(prev.meta.get("rows") or [])
|
||||
rows_b = normalize_rows(nxt.meta.get("rows") or [])
|
||||
header_rows = _header_rows(prev)
|
||||
sig = _header_sig(prev)
|
||||
|
||||
skip = _repeated_header(rows_b, sig)
|
||||
merged_rows = rows_a + rows_b[skip:]
|
||||
|
||||
body_rows, _, foot_a = split_body_and_footnotes(rows_a, header_rows)
|
||||
_, _, foot_b = split_body_and_footnotes(rows_b, skip or header_rows)
|
||||
footnotes = " ".join(x for x in (prev.meta.get("footnotes") or foot_a, foot_b) if x).strip()
|
||||
|
||||
pages = sorted(set((prev.meta.get("pages") or [_page(prev)]) + [_page(nxt)]))
|
||||
pages = [p for p in pages if p is not None]
|
||||
bboxes = list(prev.meta.get("bboxes") or [])
|
||||
if prev.meta.get("bbox"):
|
||||
bboxes.append({"page": _page(prev), "bbox": prev.meta["bbox"]})
|
||||
if nxt.meta.get("bbox"):
|
||||
bboxes.append({"page": _page(nxt), "bbox": nxt.meta["bbox"]})
|
||||
|
||||
prev_bbox = prev.meta.get("bbox") or [0, 0, 0, 0]
|
||||
nxt_bbox = nxt.meta.get("bbox") or prev_bbox
|
||||
merged_bbox = [
|
||||
min(prev_bbox[0], nxt_bbox[0]),
|
||||
min(prev_bbox[1], nxt_bbox[1]),
|
||||
max(prev_bbox[2], nxt_bbox[2]),
|
||||
max(prev_bbox[3], nxt_bbox[3]),
|
||||
]
|
||||
|
||||
md = rows_to_markdown(merged_rows, header_rows=header_rows, include_footnotes=footnotes)
|
||||
meta = dict(prev.meta)
|
||||
meta.update(
|
||||
{
|
||||
"rows": merged_rows,
|
||||
"row_count": len(merged_rows),
|
||||
"col_count": max((len(r) for r in merged_rows), default=0),
|
||||
"header_rows": header_rows,
|
||||
"header_signature": [list(r) for r in sig],
|
||||
"footnotes": footnotes,
|
||||
"pages": pages,
|
||||
"page": pages[0] if pages else prev.meta.get("page"),
|
||||
"bbox": merged_bbox,
|
||||
"bboxes": bboxes,
|
||||
"cross_page": len(pages) > 1,
|
||||
"merged_table_count": int(prev.meta.get("merged_table_count") or 1) + 1,
|
||||
}
|
||||
)
|
||||
if nxt.meta.get("following_text") and not meta.get("following_text"):
|
||||
meta["following_text"] = nxt.meta.get("following_text")
|
||||
|
||||
return prev.model_copy(update={"markdown": md, "meta": meta})
|
||||
|
||||
|
||||
def merge_cross_page_tables(blocks: list[Block]) -> list[Block]:
|
||||
"""Merge consecutive cross-page table blocks that share headers/structure."""
|
||||
if not blocks:
|
||||
return []
|
||||
|
||||
result: list[Block] = []
|
||||
i = 0
|
||||
while i < len(blocks):
|
||||
current = blocks[i]
|
||||
if current.type != BlockType.TABLE:
|
||||
result.append(current)
|
||||
i += 1
|
||||
continue
|
||||
|
||||
merged = current
|
||||
j = i + 1
|
||||
while j < len(blocks):
|
||||
nxt = blocks[j]
|
||||
if nxt.type == BlockType.TABLE and _can_merge_continuation(merged, nxt):
|
||||
merged = _merge_two_tables(merged, nxt)
|
||||
j += 1
|
||||
continue
|
||||
break
|
||||
|
||||
result.append(merged)
|
||||
i = j
|
||||
|
||||
return result
|
||||
@@ -0,0 +1,313 @@
|
||||
"""Table helpers: normalization, header detection, Markdown export, cross-page merge."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import re
|
||||
from typing import Any
|
||||
|
||||
FOOTNOTE_ROW_RE = re.compile(r"^[\s*※①②③④⑤]*(?:注[::]?|备注[::]?|说明[::]?|Note[::]?)", re.I)
|
||||
DATA_FIRST_CELL_RE = re.compile(r"^[a-z_][a-z0-9_.-]*$", re.I)
|
||||
TABLE_TITLE_RE = re.compile(
|
||||
r"^(?:表\s*\d+[::.]?|Table\s*\d+[::.]?|图\s*\d+[::.]?)?\s*.{2,80}$",
|
||||
re.I,
|
||||
)
|
||||
KEYWORD_TERMS = (
|
||||
"字段", "参数", "必填", "选填", "状态", "类型", "说明", "含义", "取值",
|
||||
"field", "parameter", "required", "optional", "status", "description",
|
||||
)
|
||||
|
||||
|
||||
def normalize_cell(value: str | None) -> str:
|
||||
"""Merge in-cell line breaks; escape pipe chars for Markdown tables."""
|
||||
if not value:
|
||||
return ""
|
||||
text = str(value).replace("\r\n", "\n").replace("\r", "\n")
|
||||
parts = [p.strip() for p in text.split("\n") if p.strip()]
|
||||
merged = " ".join(parts) if parts else ""
|
||||
return merged.replace("|", "\\|")
|
||||
|
||||
|
||||
def normalize_rows(rows: list[list[str | None]]) -> list[list[str]]:
|
||||
"""Pad columns and normalize every cell without losing row alignment."""
|
||||
if not rows:
|
||||
return []
|
||||
cleaned = [[normalize_cell(c) for c in row] for row in rows]
|
||||
col_count = max((len(r) for r in cleaned), default=0)
|
||||
return [row + [""] * (col_count - len(row)) for row in cleaned]
|
||||
|
||||
|
||||
def looks_like_table(rows: list[list[str | None]]) -> bool:
|
||||
"""Return True only for rows that have a real table-like grid."""
|
||||
if len(rows) < 2:
|
||||
return False
|
||||
|
||||
cleaned = normalize_rows(rows)
|
||||
col_count = max((len(r) for r in cleaned), default=0)
|
||||
if col_count < 2:
|
||||
return False
|
||||
|
||||
non_empty_cells = sum(1 for row in cleaned for cell in row if cell)
|
||||
rows_with_two_cells = sum(1 for row in cleaned if sum(1 for cell in row if cell) >= 2)
|
||||
return non_empty_cells >= 4 and rows_with_two_cells >= 2
|
||||
|
||||
|
||||
DESCRIPTION_HINTS = ("必填", "选填", "格式要求", "required", "optional", "格式", "用于标识")
|
||||
QA_HEADER_TERMS = ("query", "question", "用户输入", "reference_output", "answer", "标准答案", "session")
|
||||
|
||||
|
||||
def _row_fill(row: list[str]) -> int:
|
||||
return sum(1 for c in row if c)
|
||||
|
||||
|
||||
def looks_like_column_header_row(row: list[str]) -> bool:
|
||||
"""True when a row looks like short spreadsheet column names."""
|
||||
filled = [c.strip() for c in row if c and c.strip()]
|
||||
if len(filled) < 2:
|
||||
return False
|
||||
if any(len(c) > 40 for c in filled):
|
||||
return False
|
||||
identifier_like = sum(
|
||||
1
|
||||
for c in filled
|
||||
if DATA_FIRST_CELL_RE.match(c) or re.match(r"^[a-z][a-z0-9_]*$", c, re.I)
|
||||
)
|
||||
return identifier_like >= max(2, (len(filled) + 1) // 2)
|
||||
|
||||
|
||||
def looks_like_description_row(row: list[str]) -> bool:
|
||||
"""True when a row is a template field-description line (not data/header)."""
|
||||
filled = [c.strip() for c in row if c and c.strip()]
|
||||
if not filled:
|
||||
return False
|
||||
if max(len(c) for c in filled) >= 48:
|
||||
return True
|
||||
return sum(1 for c in filled if any(h in c for h in DESCRIPTION_HINTS)) >= 2
|
||||
|
||||
|
||||
def detect_header_row_count(rows: list[list[str]]) -> int:
|
||||
"""Detect 1-2 header rows from content patterns."""
|
||||
if len(rows) < 2:
|
||||
return 1 if rows else 0
|
||||
|
||||
first_fill = _row_fill(rows[0])
|
||||
second_fill = _row_fill(rows[1]) if len(rows) > 1 else 0
|
||||
if first_fill < 2:
|
||||
return 0
|
||||
|
||||
if len(rows) > 2 and second_fill >= 2:
|
||||
first_short = all(len(c) <= 24 for c in rows[0] if c)
|
||||
second_short = all(len(c) <= 24 for c in rows[1] if c)
|
||||
second_is_data = bool(rows[1][0]) and DATA_FIRST_CELL_RE.match(rows[1][0])
|
||||
third_data_like = _row_fill(rows[2]) >= max(1, first_fill - 1)
|
||||
if first_short and second_short and third_data_like and not second_is_data:
|
||||
return 2
|
||||
return 1
|
||||
|
||||
|
||||
def detect_spreadsheet_layout(rows: list[list[str]]) -> dict[str, int]:
|
||||
"""
|
||||
Detect spreadsheet preamble/header/data boundaries (1-based row numbers).
|
||||
|
||||
Common template: row 1 = field descriptions, row 2 = column names, row 3+ = data.
|
||||
"""
|
||||
normalized = normalize_rows(rows)
|
||||
if not normalized:
|
||||
return {
|
||||
"preamble_rows": 0,
|
||||
"header_rows": 1,
|
||||
"header_row_start": 1,
|
||||
"header_row_end": 1,
|
||||
"data_start_row": 2,
|
||||
}
|
||||
|
||||
preamble = 0
|
||||
header_index = 0
|
||||
|
||||
if (
|
||||
len(normalized) >= 3
|
||||
and looks_like_description_row(normalized[0])
|
||||
and looks_like_column_header_row(normalized[1])
|
||||
):
|
||||
preamble = 1
|
||||
header_index = 1
|
||||
header_rows = 1
|
||||
else:
|
||||
header_rows = detect_header_row_count(normalized)
|
||||
header_index = preamble
|
||||
|
||||
header_end_index = header_index + header_rows - 1
|
||||
data_start_index = header_end_index + 1
|
||||
|
||||
return {
|
||||
"preamble_rows": preamble,
|
||||
"header_rows": header_rows,
|
||||
"header_row_start": header_index + 1,
|
||||
"header_row_end": header_end_index + 1,
|
||||
"data_start_row": data_start_index + 1,
|
||||
}
|
||||
|
||||
|
||||
def is_qa_style_table(rows: list[list[str]], layout: dict[str, int] | None = None) -> bool:
|
||||
"""True for evaluation/Q&A sheets where each row should become one chunk."""
|
||||
if not rows:
|
||||
return False
|
||||
layout = layout or detect_spreadsheet_layout(rows)
|
||||
h_start = layout["header_row_start"] - 1
|
||||
h_end = layout["header_row_end"]
|
||||
header_text = " ".join(
|
||||
(cell or "").lower() for row in rows[h_start:h_end] for cell in row if cell
|
||||
)
|
||||
return sum(1 for term in QA_HEADER_TERMS if term in header_text) >= 2
|
||||
|
||||
|
||||
def split_body_and_footnotes(rows: list[list[str]], header_rows: int) -> tuple[list[list[str]], list[list[str]], str]:
|
||||
"""Separate data rows from trailing footnote rows."""
|
||||
if header_rows >= len(rows):
|
||||
return [], [], ""
|
||||
|
||||
body = rows[header_rows:]
|
||||
footnote_rows: list[list[str]] = []
|
||||
while body:
|
||||
first_cell = (body[-1][0] if body[-1] else "") or ""
|
||||
joined = " ".join(c for c in body[-1] if c)
|
||||
if FOOTNOTE_ROW_RE.match(first_cell) or FOOTNOTE_ROW_RE.match(joined):
|
||||
footnote_rows.insert(0, body.pop())
|
||||
elif len(joined) <= 80 and any(k in joined for k in ("注", "备注", "说明", "Note")):
|
||||
footnote_rows.insert(0, body.pop())
|
||||
else:
|
||||
break
|
||||
|
||||
footnotes = " ".join(" ".join(c for c in row if c) for row in footnote_rows).strip()
|
||||
return body, footnote_rows, footnotes
|
||||
|
||||
|
||||
def header_signature(rows: list[list[str]], header_rows: int) -> tuple[tuple[str, ...], ...]:
|
||||
if header_rows <= 0:
|
||||
return ()
|
||||
return tuple(tuple(row) for row in rows[:header_rows])
|
||||
|
||||
|
||||
def rows_to_markdown(
|
||||
rows: list[list[str | None]],
|
||||
header_rows: int | None = None,
|
||||
include_footnotes: str = "",
|
||||
) -> str:
|
||||
"""Render rows as a standard Markdown table."""
|
||||
if not looks_like_table(rows):
|
||||
return ""
|
||||
|
||||
normalized = normalize_rows(rows)
|
||||
if header_rows is None:
|
||||
header_rows = detect_header_row_count(normalized)
|
||||
|
||||
body_rows, _, inline_footnotes = split_body_and_footnotes(normalized, header_rows)
|
||||
data_rows = normalized[:header_rows] + body_rows
|
||||
if not data_rows:
|
||||
return ""
|
||||
|
||||
col_count = max(len(r) for r in data_rows)
|
||||
lines: list[str] = []
|
||||
for i, row in enumerate(data_rows):
|
||||
padded = row + [""] * (col_count - len(row))
|
||||
lines.append("| " + " | ".join(padded) + " |")
|
||||
if i == header_rows - 1:
|
||||
lines.append("| " + " | ".join(["---"] * col_count) + " |")
|
||||
|
||||
md = "\n".join(lines)
|
||||
footnotes = include_footnotes or inline_footnotes
|
||||
if footnotes:
|
||||
md += f"\n\n*{footnotes}*"
|
||||
return md
|
||||
|
||||
|
||||
def guess_table_title(text: str) -> str | None:
|
||||
"""Guess table title from a short preceding line."""
|
||||
cleaned = normalize_cell(text)
|
||||
if not cleaned or len(cleaned) > 120:
|
||||
return None
|
||||
if TABLE_TITLE_RE.match(cleaned):
|
||||
return cleaned
|
||||
if cleaned.endswith("表") or cleaned.endswith("列表") or cleaned.endswith("说明"):
|
||||
return cleaned
|
||||
if re.match(r"^表\s*\d+", cleaned):
|
||||
return cleaned
|
||||
return None
|
||||
|
||||
|
||||
def extract_table_keywords(*texts: str, limit: int = 20) -> list[str]:
|
||||
"""Extract retrieval keywords from table title, headers and body."""
|
||||
source = " ".join(t for t in texts if t)
|
||||
words = re.findall(r"[A-Za-z][A-Za-z0-9_-]{2,}|[\u4e00-\u9fff]{2,}", source)
|
||||
seen: set[str] = set()
|
||||
result: list[str] = []
|
||||
for word in words:
|
||||
if word in seen:
|
||||
continue
|
||||
seen.add(word)
|
||||
result.append(word)
|
||||
if len(result) >= limit:
|
||||
break
|
||||
for term in KEYWORD_TERMS:
|
||||
if term.lower() in source.lower() and term not in seen:
|
||||
result.append(term)
|
||||
seen.add(term)
|
||||
if len(result) >= limit:
|
||||
break
|
||||
return result[:limit]
|
||||
|
||||
|
||||
def build_table_embedding_text(
|
||||
*,
|
||||
chapter: str = "",
|
||||
table_title: str = "",
|
||||
markdown: str = "",
|
||||
description: str = "",
|
||||
footnotes: str = "",
|
||||
keywords: list[str] | None = None,
|
||||
ocr_text: str = "",
|
||||
) -> str:
|
||||
"""Compose embedding text: chapter + title + markdown + description + keywords."""
|
||||
parts: list[str] = []
|
||||
if chapter:
|
||||
parts.append(f"章节标题:{chapter}")
|
||||
if table_title:
|
||||
parts.append(f"表格标题:{table_title}")
|
||||
if markdown:
|
||||
parts.append(markdown)
|
||||
if description:
|
||||
parts.append(f"表格说明:{description}")
|
||||
if footnotes:
|
||||
parts.append(f"脚注说明:{footnotes}")
|
||||
if ocr_text:
|
||||
parts.append(f"表格 OCR:{ocr_text}")
|
||||
if keywords:
|
||||
parts.append(f"关键词:{','.join(keywords)}")
|
||||
return "\n".join(parts)
|
||||
|
||||
|
||||
def table_meta_summary(meta: dict[str, Any]) -> dict[str, Any]:
|
||||
"""Pick table-specific fields for chunk metadata."""
|
||||
keys = (
|
||||
"table_title",
|
||||
"table_description",
|
||||
"header_rows",
|
||||
"header_signature",
|
||||
"footnotes",
|
||||
"keywords",
|
||||
"chapter",
|
||||
"pages",
|
||||
"page",
|
||||
"bbox",
|
||||
"bboxes",
|
||||
"crop_path",
|
||||
"image_path",
|
||||
"row_count",
|
||||
"col_count",
|
||||
"cross_page",
|
||||
"table_source",
|
||||
"preceding_text",
|
||||
"following_text",
|
||||
"nearest_heading",
|
||||
"parent_heading",
|
||||
)
|
||||
return {k: meta[k] for k in keys if k in meta and meta[k] not in (None, "", [], {})}
|
||||
@@ -0,0 +1,104 @@
|
||||
"""Text block extraction from analyzed layout."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import re
|
||||
|
||||
from rag_cut.models import Block, BlockType
|
||||
from rag_cut.parsers.pdf.layout import LayoutRegion, PageLayout
|
||||
|
||||
_UI_LABEL_RE = re.compile(r"^[\d\s\W]{0,6}[\u4e00-\u9fff]{1,6}$")
|
||||
# "10.上升三角形態" / "1.2 ACCOUNT STATUS" (space after number optional)
|
||||
_NUMBERED_HEADING_RE = re.compile(
|
||||
r"^\s*(\d+(?:\.\d+)*)(?:\.|.)?\s*([A-Za-z0-9\u4e00-\u9fff][A-Za-z0-9\u4e00-\u9fff&/ \-_::]{2,})\s*$"
|
||||
)
|
||||
|
||||
# Title+body merges must not become headings; real section titles stay shorter.
|
||||
MAX_HEADING_CHARS = 100
|
||||
|
||||
|
||||
def _numbered_heading_level(text: str) -> int | None:
|
||||
match = _NUMBERED_HEADING_RE.match(text.strip())
|
||||
if not match or len(match.group(2).strip()) < 3:
|
||||
return None
|
||||
return match.group(1).count(".") + 1
|
||||
|
||||
|
||||
def _looks_like_ui_label(text: str) -> bool:
|
||||
"""True for short UI chips; exclude numbered / CJK section titles."""
|
||||
stripped = text.strip()
|
||||
if _numbered_heading_level(stripped) is not None:
|
||||
return False
|
||||
if re.match(r"^\d+(?:\.\d+)*(?:\.|.)", stripped):
|
||||
return False
|
||||
# Short Chinese section banners like 「形態指標」are not toolbar labels.
|
||||
if re.fullmatch(r"[\u4e00-\u9fff]{2,12}", stripped):
|
||||
return False
|
||||
return bool(_UI_LABEL_RE.match(stripped))
|
||||
|
||||
|
||||
def _font_heading_level(size: float, body_size: float, text: str) -> int | None:
|
||||
stripped = text.strip()
|
||||
numbered = _numbered_heading_level(stripped)
|
||||
if numbered and len(stripped) <= MAX_HEADING_CHARS:
|
||||
return numbered
|
||||
if len(stripped) < 4 or len(stripped) > MAX_HEADING_CHARS:
|
||||
return None
|
||||
if _looks_like_ui_label(stripped):
|
||||
return None
|
||||
|
||||
# Compact CJK section titles such as 「形態指標」.
|
||||
if (
|
||||
size >= body_size + 3
|
||||
and re.fullmatch(r"[\u4e00-\u9fff]{2,12}", stripped)
|
||||
and not _numbered_heading_level(stripped)
|
||||
):
|
||||
return 1
|
||||
|
||||
if size >= body_size + 6:
|
||||
return 1 if len(stripped) >= 10 else 2
|
||||
if size >= body_size + 3:
|
||||
return 2 if len(stripped) >= 8 else 3
|
||||
if size >= body_size + 1.5:
|
||||
return 3
|
||||
return None
|
||||
|
||||
|
||||
def extract_text_blocks(layout: PageLayout, chapter_title: str | None = None) -> tuple[list[Block], str | None]:
|
||||
"""Extract heading/paragraph blocks; update chapter title when headings appear."""
|
||||
blocks: list[Block] = []
|
||||
current_chapter = chapter_title
|
||||
|
||||
for region in layout.regions:
|
||||
if region.kind != "text":
|
||||
continue
|
||||
|
||||
text = region.data.get("text", "").strip()
|
||||
if not text:
|
||||
continue
|
||||
|
||||
font_size = float(region.data.get("font_size", layout.body_font_size))
|
||||
level = _font_heading_level(font_size, layout.body_font_size, text)
|
||||
page_no = layout.page_index + 1
|
||||
meta = {
|
||||
"page": page_no,
|
||||
"bbox": [region.x0, region.y0, region.x1, region.y1],
|
||||
"font_size": font_size,
|
||||
"body_font_size": layout.body_font_size,
|
||||
"page_height": layout.page_height,
|
||||
}
|
||||
if current_chapter:
|
||||
meta["chapter"] = current_chapter
|
||||
|
||||
if level:
|
||||
if level <= 2:
|
||||
current_chapter = text
|
||||
if current_chapter:
|
||||
meta["chapter"] = current_chapter
|
||||
blk = Block(type=BlockType.HEADING, text=text, level=level, meta=meta)
|
||||
else:
|
||||
blk = Block(type=BlockType.PARAGRAPH, text=text, meta=meta)
|
||||
|
||||
blocks.append(blk)
|
||||
|
||||
return blocks, current_chapter
|
||||
@@ -0,0 +1,91 @@
|
||||
"""Image/table region cropping with OCR and descriptions."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
from pathlib import Path
|
||||
|
||||
import fitz
|
||||
|
||||
from rag_cut.models import Block, BlockType
|
||||
from rag_cut.parsers.pdf.layout import LayoutRegion, PageLayout
|
||||
from rag_cut.parsers.pdf.ocr import describe_visual, ocr_image_file, ocr_pixmap
|
||||
from rag_cut.parsers.pdf.table_extract import build_table_block
|
||||
|
||||
|
||||
def _crop_region(page: fitz.Page, region: LayoutRegion, zoom: float = 2.0) -> fitz.Pixmap:
|
||||
clip = fitz.Rect(region.x0, region.y0, region.x1, region.y1)
|
||||
return page.get_pixmap(matrix=fitz.Matrix(zoom, zoom), clip=clip, alpha=False)
|
||||
|
||||
|
||||
def _save_pixmap(pix: fitz.Pixmap, path: Path) -> None:
|
||||
if pix.n - pix.alpha > 3:
|
||||
pix = fitz.Pixmap(fitz.csRGB, pix)
|
||||
pix.save(str(path))
|
||||
|
||||
|
||||
def extract_visual_blocks(
|
||||
page: fitz.Page,
|
||||
layout: PageLayout,
|
||||
doc: fitz.Document,
|
||||
assets_dir: Path,
|
||||
chapter_title: str | None,
|
||||
img_counter: int,
|
||||
) -> tuple[list[Block], int]:
|
||||
blocks: list[Block] = []
|
||||
page_no = layout.page_index + 1
|
||||
|
||||
for region in layout.regions:
|
||||
if region.kind == "table":
|
||||
table_block = build_table_block(page, region, layout, assets_dir, chapter_title)
|
||||
if table_block:
|
||||
blocks.append(table_block)
|
||||
continue
|
||||
|
||||
if region.kind != "image":
|
||||
continue
|
||||
|
||||
img_counter += 1
|
||||
xref = region.data.get("xref")
|
||||
img_id = f"page{page_no}_img{img_counter}.png"
|
||||
img_path = assets_dir / img_id
|
||||
|
||||
try:
|
||||
# Prefer on-page crop so scaled/clipped placements OCR the visible region.
|
||||
crop_pix = _crop_region(page, region)
|
||||
_save_pixmap(crop_pix, img_path)
|
||||
except Exception:
|
||||
try:
|
||||
pix = fitz.Pixmap(doc, xref)
|
||||
if pix.n - pix.alpha > 3:
|
||||
pix = fitz.Pixmap(fitz.csRGB, pix)
|
||||
pix.save(str(img_path))
|
||||
except Exception:
|
||||
continue
|
||||
|
||||
ocr_text = ocr_image_file(img_path)
|
||||
if not ocr_text:
|
||||
try:
|
||||
ocr_text = ocr_pixmap(_crop_region(page, region))
|
||||
except Exception:
|
||||
ocr_text = ""
|
||||
|
||||
meta = {
|
||||
"page": page_no,
|
||||
"bbox": [region.x0, region.y0, region.x1, region.y1],
|
||||
"xref": xref,
|
||||
}
|
||||
if chapter_title:
|
||||
meta["chapter"] = chapter_title
|
||||
|
||||
blocks.append(
|
||||
Block(
|
||||
type=BlockType.IMAGE,
|
||||
image_id=img_id,
|
||||
image_path=str(img_path),
|
||||
ocr_text=ocr_text,
|
||||
text=describe_visual(ocr_text, "图片", img_id),
|
||||
meta=meta,
|
||||
)
|
||||
)
|
||||
|
||||
return blocks, img_counter
|
||||
@@ -0,0 +1,31 @@
|
||||
"""PDF parser entry point — delegates to the PyMuPDF pipeline."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import os
|
||||
from pathlib import Path
|
||||
|
||||
from rag_cut.models import Block
|
||||
from rag_cut.parsers.base import BaseParser
|
||||
from rag_cut.parsers.mineru_adapter import parse_pdf_with_mineru
|
||||
from rag_cut.parsers.pdf.noise_filter import filter_noise_blocks
|
||||
from rag_cut.parsers.pdf.pipeline import parse_pdf
|
||||
|
||||
|
||||
class PdfParser(BaseParser):
|
||||
def parse(self, path: Path, assets_dir: Path) -> list[Block]:
|
||||
engine = os.getenv("RAG_CUT_PDF_ENGINE", "auto").strip().lower()
|
||||
if engine not in {"auto", "mineru", "pymupdf"}:
|
||||
engine = "auto"
|
||||
|
||||
blocks: list[Block] | None = None
|
||||
if engine in {"auto", "mineru"}:
|
||||
blocks = parse_pdf_with_mineru(path, assets_dir)
|
||||
if blocks is None and engine == "mineru":
|
||||
raise RuntimeError("MinerU parsing failed or MinerU is not installed")
|
||||
|
||||
if blocks is None:
|
||||
blocks = parse_pdf(path, assets_dir)
|
||||
|
||||
# filter_noise_blocks already includes TOC removal.
|
||||
return filter_noise_blocks(blocks)
|
||||
@@ -0,0 +1,30 @@
|
||||
"""PPT/PPTX parser: convert to PDF, then reuse PdfParser."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
from pathlib import Path
|
||||
|
||||
from rag_cut.models import Block
|
||||
from rag_cut.parsers.base import BaseParser
|
||||
from rag_cut.parsers.office_to_pdf import convert_to_pdf
|
||||
from rag_cut.parsers.pdf_parser import PdfParser
|
||||
|
||||
|
||||
class PptParser(BaseParser):
|
||||
"""Parse presentations by converting to PDF and delegating to PdfParser."""
|
||||
|
||||
def __init__(self) -> None:
|
||||
self._pdf_parser = PdfParser()
|
||||
|
||||
def parse(self, path: Path, assets_dir: Path) -> list[Block]:
|
||||
assets_dir.mkdir(parents=True, exist_ok=True)
|
||||
pdf_dir = assets_dir / "_conversion"
|
||||
pdf_path = convert_to_pdf(path, pdf_dir)
|
||||
|
||||
blocks = self._pdf_parser.parse(pdf_path, assets_dir)
|
||||
source_fmt = path.suffix.lower().lstrip(".")
|
||||
for block in blocks:
|
||||
block.meta.setdefault("source_format", source_fmt)
|
||||
if page := block.meta.get("page"):
|
||||
block.meta["slide"] = page
|
||||
return blocks
|
||||
@@ -0,0 +1,44 @@
|
||||
"""Route file extensions to parsers."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
from pathlib import Path
|
||||
|
||||
from rag_cut.parsers.base import BaseParser
|
||||
from rag_cut.parsers.word_parser import WordParser
|
||||
from rag_cut.parsers.image_parser import ImageParser
|
||||
from rag_cut.parsers.pdf_parser import PdfParser
|
||||
from rag_cut.parsers.ppt_parser import PptParser
|
||||
from rag_cut.parsers.text_parser import TextParser
|
||||
from rag_cut.parsers.xlsx_parser import SpreadsheetParser
|
||||
|
||||
PARSERS: dict[str, BaseParser] = {
|
||||
".docx": WordParser(),
|
||||
".doc": WordParser(),
|
||||
".pdf": PdfParser(),
|
||||
".ppt": PptParser(),
|
||||
".pptx": PptParser(),
|
||||
".ppsx": PptParser(),
|
||||
".xlsx": SpreadsheetParser(),
|
||||
".xls": SpreadsheetParser(),
|
||||
".csv": SpreadsheetParser(),
|
||||
".md": TextParser(),
|
||||
".txt": TextParser(),
|
||||
".html": TextParser(),
|
||||
".htm": TextParser(),
|
||||
".json": TextParser(),
|
||||
".xml": TextParser(),
|
||||
".log": TextParser(),
|
||||
".jpg": ImageParser(),
|
||||
".jpeg": ImageParser(),
|
||||
".png": ImageParser(),
|
||||
".bmp": ImageParser(),
|
||||
".gif": ImageParser(),
|
||||
}
|
||||
|
||||
|
||||
def get_parser(path: Path) -> BaseParser:
|
||||
ext = path.suffix.lower()
|
||||
if ext not in PARSERS:
|
||||
raise ValueError(f"Unsupported file type: {ext}")
|
||||
return PARSERS[ext]
|
||||
@@ -0,0 +1,123 @@
|
||||
"""Plain-text and markup parsers."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import json
|
||||
import re
|
||||
from html.parser import HTMLParser
|
||||
from pathlib import Path
|
||||
|
||||
from rag_cut.models import Block, BlockType
|
||||
from rag_cut.parsers.base import BaseParser
|
||||
|
||||
|
||||
class _HTMLTextExtractor(HTMLParser):
|
||||
def __init__(self) -> None:
|
||||
super().__init__()
|
||||
self._parts: list[str] = []
|
||||
self._heading: tuple[int, str] | None = None
|
||||
self._blocks: list[Block] = []
|
||||
self._current: list[str] = []
|
||||
self._in_heading = False
|
||||
|
||||
def handle_starttag(self, tag: str, attrs) -> None:
|
||||
if tag in ("h1", "h2", "h3", "h4", "h5", "h6"):
|
||||
self._flush_paragraph()
|
||||
self._in_heading = True
|
||||
self._heading_level = int(tag[1])
|
||||
|
||||
def handle_endtag(self, tag: str) -> None:
|
||||
if tag in ("h1", "h2", "h3", "h4", "h5", "h6"):
|
||||
text = "".join(self._current).strip()
|
||||
self._current = []
|
||||
self._in_heading = False
|
||||
if text:
|
||||
self._blocks.append(
|
||||
Block(type=BlockType.HEADING, text=text, level=self._heading_level)
|
||||
)
|
||||
elif tag in ("p", "div", "br", "li"):
|
||||
self._flush_paragraph()
|
||||
|
||||
def handle_data(self, data: str) -> None:
|
||||
self._current.append(data)
|
||||
|
||||
def _flush_paragraph(self) -> None:
|
||||
text = "".join(self._current).strip()
|
||||
self._current = []
|
||||
if text:
|
||||
self._blocks.append(Block(type=BlockType.PARAGRAPH, text=text))
|
||||
|
||||
def get_blocks(self) -> list[Block]:
|
||||
self._flush_paragraph()
|
||||
return self._blocks
|
||||
|
||||
|
||||
def _parse_markdown(text: str) -> list[Block]:
|
||||
blocks: list[Block] = []
|
||||
for line in text.splitlines():
|
||||
stripped = line.strip()
|
||||
if not stripped:
|
||||
continue
|
||||
m = re.match(r"^(#{1,6})\s+(.+)$", stripped)
|
||||
if m:
|
||||
blocks.append(
|
||||
Block(type=BlockType.HEADING, text=m.group(2).strip(), level=len(m.group(1)))
|
||||
)
|
||||
else:
|
||||
blocks.append(Block(type=BlockType.PARAGRAPH, text=stripped))
|
||||
return blocks
|
||||
|
||||
|
||||
def _parse_json(text: str) -> list[Block]:
|
||||
data = json.loads(text)
|
||||
blocks: list[Block] = []
|
||||
if isinstance(data, list):
|
||||
for i, item in enumerate(data):
|
||||
blocks.append(
|
||||
Block(
|
||||
type=BlockType.CODE,
|
||||
text=json.dumps(item, ensure_ascii=False, indent=2),
|
||||
meta={"json_index": i},
|
||||
)
|
||||
)
|
||||
elif isinstance(data, dict):
|
||||
for key, value in data.items():
|
||||
blocks.append(
|
||||
Block(
|
||||
type=BlockType.CODE,
|
||||
text=json.dumps({key: value}, ensure_ascii=False, indent=2),
|
||||
meta={"json_key": key},
|
||||
)
|
||||
)
|
||||
else:
|
||||
blocks.append(Block(type=BlockType.PARAGRAPH, text=str(data)))
|
||||
return blocks
|
||||
|
||||
|
||||
class TextParser(BaseParser):
|
||||
def parse(self, path: Path, assets_dir: Path) -> list[Block]:
|
||||
for encoding in ("utf-8-sig", "utf-8", "gbk", "latin-1"):
|
||||
try:
|
||||
text = path.read_text(encoding=encoding)
|
||||
break
|
||||
except UnicodeDecodeError:
|
||||
continue
|
||||
else:
|
||||
raise ValueError(f"Cannot decode text file: {path}")
|
||||
|
||||
ext = path.suffix.lower()
|
||||
if ext == ".md":
|
||||
return _parse_markdown(text)
|
||||
if ext in (".html", ".htm"):
|
||||
parser = _HTMLTextExtractor()
|
||||
parser.feed(text)
|
||||
return parser.get_blocks()
|
||||
if ext == ".json":
|
||||
return _parse_json(text)
|
||||
# txt, xml, log — paragraph split on blank lines
|
||||
blocks: list[Block] = []
|
||||
for para in re.split(r"\n\s*\n", text):
|
||||
para = para.strip()
|
||||
if para:
|
||||
blocks.append(Block(type=BlockType.PARAGRAPH, text=para))
|
||||
return blocks
|
||||
@@ -0,0 +1,29 @@
|
||||
"""DOC/DOCX parser: convert to PDF, then reuse PdfParser."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
from pathlib import Path
|
||||
|
||||
from rag_cut.models import Block
|
||||
from rag_cut.parsers.base import BaseParser
|
||||
from rag_cut.parsers.office_to_pdf import convert_to_pdf
|
||||
from rag_cut.parsers.pdf_parser import PdfParser
|
||||
|
||||
|
||||
class WordParser(BaseParser):
|
||||
"""Parse Word documents by converting to PDF and delegating to PdfParser."""
|
||||
|
||||
def __init__(self) -> None:
|
||||
self._pdf_parser = PdfParser()
|
||||
|
||||
def parse(self, path: Path, assets_dir: Path) -> list[Block]:
|
||||
assets_dir.mkdir(parents=True, exist_ok=True)
|
||||
pdf_dir = assets_dir / "_conversion"
|
||||
pdf_path = convert_to_pdf(path, pdf_dir)
|
||||
|
||||
blocks = self._pdf_parser.parse(pdf_path, assets_dir)
|
||||
source_fmt = path.suffix.lower().lstrip(".")
|
||||
for block in blocks:
|
||||
block.meta.setdefault("source_format", source_fmt)
|
||||
block.meta.setdefault("converted_from", source_fmt)
|
||||
return blocks
|
||||
@@ -0,0 +1,89 @@
|
||||
"""Spreadsheet parser (xlsx/xls/csv) producing row-oriented table blocks."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import csv
|
||||
from pathlib import Path
|
||||
|
||||
from rag_cut.models import Block, BlockType
|
||||
from rag_cut.parsers.base import BaseParser
|
||||
from rag_cut.parsers.pdf.tables import (
|
||||
build_table_embedding_text,
|
||||
detect_spreadsheet_layout,
|
||||
extract_table_keywords,
|
||||
normalize_rows,
|
||||
rows_to_markdown,
|
||||
)
|
||||
|
||||
|
||||
def _read_csv(path: Path) -> list[list[str]]:
|
||||
for encoding in ("utf-8-sig", "utf-8", "gbk", "latin-1"):
|
||||
try:
|
||||
with open(path, newline="", encoding=encoding) as f:
|
||||
return [list(row) for row in csv.reader(f)]
|
||||
except UnicodeDecodeError:
|
||||
continue
|
||||
raise ValueError(f"Cannot decode CSV: {path}")
|
||||
|
||||
|
||||
def _read_xlsx(path: Path, sheet_name: str | None = None) -> tuple[str, list[list[str]]]:
|
||||
import openpyxl
|
||||
|
||||
wb = openpyxl.load_workbook(path, read_only=True, data_only=True)
|
||||
name = sheet_name or wb.sheetnames[0]
|
||||
ws = wb[name]
|
||||
rows: list[list[str]] = []
|
||||
for row in ws.iter_rows(values_only=True):
|
||||
rows.append(["" if v is None else str(v) for v in row])
|
||||
wb.close()
|
||||
# trim trailing empty rows/cols
|
||||
while rows and all(not c for c in rows[-1]):
|
||||
rows.pop()
|
||||
return name, rows
|
||||
|
||||
|
||||
class SpreadsheetParser(BaseParser):
|
||||
def parse(self, path: Path, assets_dir: Path) -> list[Block]:
|
||||
ext = path.suffix.lower()
|
||||
if ext == ".csv":
|
||||
rows = _read_csv(path)
|
||||
sheet_name = path.stem
|
||||
else:
|
||||
sheet_name, rows = _read_xlsx(path)
|
||||
|
||||
if not rows:
|
||||
return []
|
||||
|
||||
normalized = normalize_rows(rows)
|
||||
layout = detect_spreadsheet_layout(normalized)
|
||||
preamble = layout["preamble_rows"]
|
||||
header_rows = layout["header_rows"]
|
||||
display_rows = normalized[preamble:]
|
||||
md = rows_to_markdown(display_rows, header_rows=header_rows)
|
||||
description = ""
|
||||
if preamble:
|
||||
description = " ".join(cell for cell in normalized[0] if cell)[:500]
|
||||
keywords = extract_table_keywords(sheet_name, md, description)
|
||||
embedding_text = build_table_embedding_text(
|
||||
table_title=sheet_name,
|
||||
markdown=md,
|
||||
description=description,
|
||||
keywords=keywords,
|
||||
)
|
||||
return [
|
||||
Block(
|
||||
type=BlockType.TABLE,
|
||||
markdown=md,
|
||||
meta={
|
||||
"sheet": sheet_name,
|
||||
"table_title": sheet_name,
|
||||
"row_count": len(normalized),
|
||||
"col_count": max(len(r) for r in normalized),
|
||||
"rows": normalized,
|
||||
"keywords": keywords,
|
||||
"embedding_text": embedding_text,
|
||||
"table_description": description or None,
|
||||
**layout,
|
||||
},
|
||||
)
|
||||
]
|
||||
@@ -0,0 +1,120 @@
|
||||
"""End-to-end document chunking pipeline."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import hashlib
|
||||
import shutil
|
||||
import uuid
|
||||
from pathlib import Path
|
||||
|
||||
from rag_cut.layout_meta import enrich_layout_metadata
|
||||
from rag_cut.models import Chunk, ChunkResult, SplitConfig, SplitMode
|
||||
from rag_cut.parsers.pdf.noise_filter import filter_toc_blocks
|
||||
from rag_cut.parsers.pdf.table_merge import merge_cross_page_tables
|
||||
from rag_cut.parsers.registry import get_parser
|
||||
from rag_cut.renderer import render_blocks
|
||||
from rag_cut.split_policy import choose_split_config, split_config_summary
|
||||
from rag_cut.splitters import split_by_delimiter, split_by_row
|
||||
from rag_cut.splitters.default_splitter import split_default_with_meta
|
||||
from rag_cut.splitters.heading_splitter import assign_parent_chunk_ids, chunk_groups_to_block_groups
|
||||
from rag_cut.splitters.parent_child import CHUNK_STRATEGY as PARENT_CHILD_STRATEGY
|
||||
from rag_cut.splitters.parent_child import split_by_parent_child
|
||||
from rag_cut.splitters.pdf_semantic import CHUNK_STRATEGY, split_pdf_semantic
|
||||
from rag_cut.splitters.pdf_strategy import choose_pdf_chunk_strategy
|
||||
|
||||
STORAGE_ROOT = Path(__file__).resolve().parent.parent.parent / "storage"
|
||||
PDF_SEMANTIC_EXTS = {".pdf", ".doc", ".docx"}
|
||||
|
||||
|
||||
def _doc_id(path: Path) -> str:
|
||||
digest = hashlib.md5(f"{path.name}-{path.stat().st_mtime}".encode()).hexdigest()[:12]
|
||||
return digest
|
||||
|
||||
|
||||
def chunk_document(
|
||||
path: Path | str,
|
||||
config: SplitConfig | None = None,
|
||||
storage_root: Path | None = None,
|
||||
) -> ChunkResult:
|
||||
path = Path(path)
|
||||
if not path.exists():
|
||||
raise FileNotFoundError(path)
|
||||
|
||||
root = storage_root or STORAGE_ROOT
|
||||
doc_id = _doc_id(path)
|
||||
assets_dir = root / "assets" / doc_id
|
||||
uploads_dir = root / "uploads" / doc_id
|
||||
uploads_dir.mkdir(parents=True, exist_ok=True)
|
||||
|
||||
stored = uploads_dir / path.name
|
||||
if path.resolve() != stored.resolve():
|
||||
shutil.copy2(path, stored)
|
||||
|
||||
parser = get_parser(path)
|
||||
blocks = merge_cross_page_tables(parser.parse(stored, assets_dir))
|
||||
blocks = enrich_layout_metadata(blocks)
|
||||
# All formats: never parse/chunk document directories (目录 / Contents).
|
||||
blocks = filter_toc_blocks(blocks)
|
||||
config = config or choose_split_config(path, blocks)
|
||||
|
||||
for block in blocks:
|
||||
if block.image_path:
|
||||
rel = Path(block.image_path)
|
||||
if "crops" in rel.parts:
|
||||
block.image_path = f"assets/{doc_id}/crops/{rel.name}"
|
||||
else:
|
||||
block.image_path = f"assets/{doc_id}/{rel.name}"
|
||||
crop = block.meta.get("crop_path")
|
||||
if crop:
|
||||
crop_name = Path(crop).name
|
||||
url = f"assets/{doc_id}/crops/{crop_name}"
|
||||
block.meta["crop_path"] = url
|
||||
if block.type.value == "table" and not block.image_path:
|
||||
block.image_path = url
|
||||
|
||||
ext = path.suffix.lower()
|
||||
pdf_strategy = None
|
||||
if ext in PDF_SEMANTIC_EXTS and config.mode == SplitMode.DEFAULT:
|
||||
pdf_strategy = choose_pdf_chunk_strategy(path, blocks)
|
||||
|
||||
group_metas: list[dict] = []
|
||||
if ext in PDF_SEMANTIC_EXTS and config.mode == SplitMode.DEFAULT:
|
||||
chunks = split_pdf_semantic(blocks, config)
|
||||
elif config.mode == SplitMode.BY_ROW:
|
||||
groups = split_by_row(blocks, config)
|
||||
chunks = []
|
||||
elif config.mode == SplitMode.DELIMITER:
|
||||
groups = split_by_delimiter(blocks, config)
|
||||
chunks = []
|
||||
elif config.mode == SplitMode.PARENT_CHILD:
|
||||
parent_child_groups = split_by_parent_child(blocks, config)
|
||||
groups, group_metas = chunk_groups_to_block_groups(parent_child_groups)
|
||||
chunks = []
|
||||
else:
|
||||
groups, group_metas = split_default_with_meta(blocks, config)
|
||||
chunks = []
|
||||
|
||||
if not chunks:
|
||||
for i, group in enumerate(groups):
|
||||
meta: dict = dict(group_metas[i]) if i < len(group_metas) else {}
|
||||
chunks.append(render_blocks(group, index=i, meta=meta))
|
||||
|
||||
chunks = assign_parent_chunk_ids(chunks)
|
||||
|
||||
split_config = split_config_summary(config)
|
||||
if pdf_strategy:
|
||||
split_config["pdf_chunk_strategy"] = pdf_strategy
|
||||
split_config["chunk_strategy"] = CHUNK_STRATEGY
|
||||
elif config.mode == SplitMode.PARENT_CHILD:
|
||||
split_config["chunk_strategy"] = PARENT_CHILD_STRATEGY
|
||||
|
||||
return ChunkResult(
|
||||
filename=path.name,
|
||||
doc_id=doc_id,
|
||||
split_mode=config.mode,
|
||||
split_config=split_config,
|
||||
block_count=len(blocks),
|
||||
chunk_count=len(chunks),
|
||||
chunks=chunks,
|
||||
assets_dir=str(assets_dir) if assets_dir.exists() else None,
|
||||
)
|
||||
@@ -0,0 +1,164 @@
|
||||
"""Render block groups into chunk markdown strings with layout metadata."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
from rag_cut.models import Block, BlockType, Chunk
|
||||
from rag_cut.parsers.pdf.tables import table_meta_summary
|
||||
|
||||
|
||||
def block_to_layout_dict(block: Block) -> dict:
|
||||
"""Serialize a block for chunk metadata and frontend positional rendering."""
|
||||
entry: dict = {
|
||||
"type": block.type.value,
|
||||
"order_index": block.meta.get("order_index"),
|
||||
"page": block.meta.get("page"),
|
||||
"pages": block.meta.get("pages"),
|
||||
"bbox": block.meta.get("bbox"),
|
||||
"bboxes": block.meta.get("bboxes"),
|
||||
"parent_heading": block.meta.get("parent_heading"),
|
||||
"nearest_heading": block.meta.get("nearest_heading"),
|
||||
"bound_heading": block.meta.get("bound_heading"),
|
||||
"preceding_text": block.meta.get("preceding_text"),
|
||||
"following_text": block.meta.get("following_text"),
|
||||
}
|
||||
if block.type == BlockType.HEADING:
|
||||
entry["text"] = block.text
|
||||
entry["level"] = block.level
|
||||
elif block.type == BlockType.IMAGE:
|
||||
entry["text"] = block.text
|
||||
entry["image_path"] = block.image_path
|
||||
entry["image_id"] = block.image_id
|
||||
entry["ocr_text"] = block.ocr_text
|
||||
elif block.type == BlockType.TABLE:
|
||||
entry["text"] = block.markdown or block.text
|
||||
entry["markdown"] = block.markdown or block.text
|
||||
entry["ocr_text"] = block.ocr_text
|
||||
entry["image_path"] = block.image_path
|
||||
entry["image_id"] = block.image_id
|
||||
entry["crop_path"] = block.meta.get("crop_path")
|
||||
entry.update(table_meta_summary(block.meta))
|
||||
entry["embedding_text"] = block.meta.get("embedding_text")
|
||||
else:
|
||||
entry["text"] = block.text or block.markdown
|
||||
return entry
|
||||
|
||||
|
||||
def collect_chunk_layout_meta(blocks: list[Block]) -> dict:
|
||||
"""Aggregate page/bbox/image/table metadata for a chunk group."""
|
||||
pages = sorted({b.meta.get("page") for b in blocks if b.meta.get("page") is not None})
|
||||
for b in blocks:
|
||||
for p in b.meta.get("pages") or []:
|
||||
if p is not None:
|
||||
pages.append(p)
|
||||
pages = sorted(set(pages))
|
||||
|
||||
bboxes = [
|
||||
{
|
||||
"order_index": b.meta.get("order_index"),
|
||||
"page": b.meta.get("page"),
|
||||
"bbox": b.meta.get("bbox"),
|
||||
"type": b.type.value,
|
||||
}
|
||||
for b in blocks
|
||||
if b.meta.get("bbox")
|
||||
]
|
||||
images = [
|
||||
{
|
||||
"order_index": b.meta.get("order_index"),
|
||||
"image_id": b.image_id,
|
||||
"image_path": b.image_path,
|
||||
"page": b.meta.get("page"),
|
||||
"bbox": b.meta.get("bbox"),
|
||||
"ocr_text": b.ocr_text,
|
||||
"bound_heading": b.meta.get("bound_heading"),
|
||||
"preceding_text": b.meta.get("preceding_text"),
|
||||
"following_text": b.meta.get("following_text"),
|
||||
}
|
||||
for b in blocks
|
||||
if b.type == BlockType.IMAGE
|
||||
]
|
||||
tables = [
|
||||
{
|
||||
"order_index": b.meta.get("order_index"),
|
||||
"table_title": b.meta.get("table_title"),
|
||||
"image_path": b.image_path or b.meta.get("crop_path"),
|
||||
"crop_path": b.meta.get("crop_path"),
|
||||
"page": b.meta.get("page"),
|
||||
"pages": b.meta.get("pages"),
|
||||
"bbox": b.meta.get("bbox"),
|
||||
"bboxes": b.meta.get("bboxes"),
|
||||
"markdown": b.markdown,
|
||||
"ocr_text": b.ocr_text,
|
||||
"footnotes": b.meta.get("footnotes"),
|
||||
"keywords": b.meta.get("keywords"),
|
||||
"nearest_heading": b.meta.get("nearest_heading"),
|
||||
"chapter": b.meta.get("chapter"),
|
||||
"row_count": b.meta.get("row_count"),
|
||||
"col_count": b.meta.get("col_count"),
|
||||
"header_rows": b.meta.get("header_rows"),
|
||||
"table_source": b.meta.get("table_source"),
|
||||
"preceding_text": b.meta.get("preceding_text"),
|
||||
"following_text": b.meta.get("following_text"),
|
||||
"cross_page": b.meta.get("cross_page"),
|
||||
"embedding_text": b.meta.get("embedding_text"),
|
||||
}
|
||||
for b in blocks
|
||||
if b.type == BlockType.TABLE
|
||||
]
|
||||
|
||||
meta: dict = {
|
||||
"blocks": [block_to_layout_dict(b) for b in blocks],
|
||||
"bboxes": bboxes,
|
||||
"images": images,
|
||||
"tables": tables,
|
||||
}
|
||||
if pages:
|
||||
meta["pages"] = pages
|
||||
if len(pages) == 1:
|
||||
meta["page"] = pages[0]
|
||||
|
||||
headings = [b.text for b in blocks if b.type == BlockType.HEADING]
|
||||
if headings:
|
||||
meta["heading"] = headings[0]
|
||||
meta["nearest_heading"] = headings[0]
|
||||
elif blocks and blocks[0].meta.get("nearest_heading"):
|
||||
meta["nearest_heading"] = blocks[0].meta.get("nearest_heading")
|
||||
|
||||
table_blocks = [b for b in blocks if b.type == BlockType.TABLE]
|
||||
if table_blocks:
|
||||
primary = table_blocks[0]
|
||||
meta["table_title"] = primary.meta.get("table_title") or meta.get("nearest_heading")
|
||||
if not meta.get("chunk_strategy"):
|
||||
meta["chunk_strategy"] = "table_with_context"
|
||||
meta["retrieval"] = meta.get("retrieval", True)
|
||||
if primary.meta.get("embedding_text"):
|
||||
meta["embedding_text"] = primary.meta["embedding_text"]
|
||||
if primary.meta.get("keywords"):
|
||||
meta["keywords"] = primary.meta["keywords"]
|
||||
|
||||
order_indices = [b.meta.get("order_index") for b in blocks if b.meta.get("order_index") is not None]
|
||||
if order_indices:
|
||||
meta["order_range"] = meta.get("order_range") or [min(order_indices), max(order_indices)]
|
||||
|
||||
return meta
|
||||
|
||||
|
||||
def render_blocks(blocks: list[Block], index: int, meta: dict | None = None) -> Chunk:
|
||||
"""Render blocks in reading order: heading → body → table/image → notes."""
|
||||
parts: list[str] = []
|
||||
for block in blocks:
|
||||
rendered = block.render().strip()
|
||||
if rendered:
|
||||
parts.append(rendered)
|
||||
content = "\n\n".join(parts)
|
||||
|
||||
layout_meta = collect_chunk_layout_meta(blocks)
|
||||
chunk_meta = {**(meta or {}), **layout_meta}
|
||||
|
||||
return Chunk(
|
||||
index=index,
|
||||
content=content,
|
||||
char_count=len(content),
|
||||
block_types=[b.type.value for b in blocks],
|
||||
meta=chunk_meta,
|
||||
)
|
||||
@@ -0,0 +1,78 @@
|
||||
"""Small dependency-free lexical retriever for the recall demo."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import math
|
||||
import re
|
||||
from collections import Counter
|
||||
|
||||
from rag_cut.models import Chunk
|
||||
|
||||
LATIN_TOKEN_RE = re.compile(r"[a-z0-9_]+", re.I)
|
||||
CJK_RE = re.compile(r"[\u3400-\u9fff]")
|
||||
|
||||
|
||||
def _tokens(text: str) -> list[str]:
|
||||
normalized = text.lower()
|
||||
tokens = LATIN_TOKEN_RE.findall(normalized)
|
||||
cjk = CJK_RE.findall(normalized)
|
||||
tokens.extend(cjk)
|
||||
tokens.extend("".join(cjk[i : i + 2]) for i in range(len(cjk) - 1))
|
||||
return tokens
|
||||
|
||||
|
||||
def _search_text(chunk: Chunk) -> str:
|
||||
meta = chunk.meta
|
||||
fields = [
|
||||
meta.get("heading") or "",
|
||||
meta.get("nearest_heading") or "",
|
||||
meta.get("embedding_text") or "",
|
||||
" ".join(meta.get("keywords") or []),
|
||||
chunk.content,
|
||||
]
|
||||
return "\n".join(str(value) for value in fields if value)
|
||||
|
||||
|
||||
def recall_chunks(query: str, chunks: list[Chunk], top_k: int = 5) -> tuple[list[dict], int]:
|
||||
"""Rank retrievable chunks with a compact BM25-style lexical score."""
|
||||
candidates = [chunk for chunk in chunks if chunk.meta.get("retrieval", True)]
|
||||
query_tokens = _tokens(query)
|
||||
if not candidates or not query_tokens:
|
||||
return [], len(candidates)
|
||||
|
||||
documents = [_tokens(_search_text(chunk)) for chunk in candidates]
|
||||
document_frequency = Counter(token for tokens in documents for token in set(tokens))
|
||||
average_length = sum(len(tokens) for tokens in documents) / len(documents)
|
||||
query_frequency = Counter(query_tokens)
|
||||
scored: list[tuple[float, Chunk]] = []
|
||||
|
||||
for chunk, tokens in zip(candidates, documents):
|
||||
frequency = Counter(tokens)
|
||||
length_normalizer = 1.2 * (0.25 + 0.75 * len(tokens) / max(average_length, 1))
|
||||
score = 0.0
|
||||
for token, query_count in query_frequency.items():
|
||||
term_count = frequency[token]
|
||||
if not term_count:
|
||||
continue
|
||||
inverse_frequency = math.log(1 + (len(documents) - document_frequency[token] + 0.5) / (document_frequency[token] + 0.5))
|
||||
score += inverse_frequency * ((term_count * 2.2) / (term_count + length_normalizer)) * min(query_count, 2)
|
||||
if score > 0:
|
||||
scored.append((score, chunk))
|
||||
|
||||
scored.sort(key=lambda item: (-item[0], item[1].index))
|
||||
results = []
|
||||
for rank, (score, chunk) in enumerate(scored[:top_k], start=1):
|
||||
results.append(
|
||||
{
|
||||
"rank": rank,
|
||||
"chunk_index": chunk.index,
|
||||
"score": round(score, 6),
|
||||
"content": chunk.content,
|
||||
"heading": chunk.meta.get("heading") or chunk.meta.get("nearest_heading"),
|
||||
"pages": chunk.meta.get("pages") or ([chunk.meta["page"]] if chunk.meta.get("page") is not None else []),
|
||||
"block_types": chunk.block_types,
|
||||
"parent_chunk_id": chunk.meta.get("parent_chunk_id"),
|
||||
"is_sub_chunk": bool(chunk.meta.get("is_sub_chunk")),
|
||||
}
|
||||
)
|
||||
return results, len(candidates)
|
||||
@@ -0,0 +1,82 @@
|
||||
"""Automatic split policy selection based on parsed document shape."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
from pathlib import Path
|
||||
|
||||
from rag_cut.models import Block, BlockType, SplitConfig, SplitMode
|
||||
from rag_cut.parsers.pdf.tables import detect_spreadsheet_layout, is_qa_style_table
|
||||
|
||||
SPREADSHEET_EXTS = {".xlsx", ".xls", ".csv"}
|
||||
PRESENTATION_EXTS = {".ppt", ".pptx", ".ppsx"}
|
||||
TEXT_EXTS = {".md", ".txt", ".html", ".htm", ".json", ".xml", ".log"}
|
||||
IMAGE_EXTS = {".jpg", ".jpeg", ".png", ".bmp", ".gif"}
|
||||
|
||||
|
||||
def _table_rows(blocks: list[Block]) -> int:
|
||||
if len(blocks) != 1 or blocks[0].type != BlockType.TABLE:
|
||||
return 0
|
||||
rows = blocks[0].meta.get("rows") or []
|
||||
return len(rows)
|
||||
|
||||
|
||||
def _rows_per_chunk(data_row_count: int) -> int:
|
||||
if data_row_count <= 20:
|
||||
return max(1, data_row_count)
|
||||
if data_row_count <= 80:
|
||||
return 10
|
||||
if data_row_count <= 300:
|
||||
return 20
|
||||
return 40
|
||||
|
||||
|
||||
def choose_split_config(path: Path, blocks: list[Block]) -> SplitConfig:
|
||||
"""Choose conservative defaults that preserve document structure first."""
|
||||
ext = path.suffix.lower()
|
||||
row_count = _table_rows(blocks)
|
||||
|
||||
if ext in SPREADSHEET_EXTS or row_count:
|
||||
rows = blocks[0].meta.get("rows") or [] if blocks else []
|
||||
layout = detect_spreadsheet_layout(rows) if rows else {
|
||||
"header_row_start": 1,
|
||||
"header_row_end": 1,
|
||||
"data_start_row": 2,
|
||||
}
|
||||
data_row_count = max(0, row_count - layout["data_start_row"] + 1)
|
||||
rows_per = 1 if is_qa_style_table(rows, layout) else _rows_per_chunk(data_row_count)
|
||||
return SplitConfig(
|
||||
mode=SplitMode.BY_ROW,
|
||||
max_chunk_size=2400,
|
||||
overlap=0,
|
||||
header_row_start=layout["header_row_start"],
|
||||
header_row_end=layout["header_row_end"],
|
||||
start_row=layout["data_start_row"],
|
||||
rows_per_chunk=rows_per,
|
||||
)
|
||||
|
||||
if ext == ".pdf" or ext in PRESENTATION_EXTS:
|
||||
return SplitConfig(mode=SplitMode.DEFAULT, max_chunk_size=2600, overlap=120)
|
||||
|
||||
if ext in IMAGE_EXTS:
|
||||
return SplitConfig(mode=SplitMode.DEFAULT, max_chunk_size=2200, overlap=0)
|
||||
|
||||
if ext in TEXT_EXTS:
|
||||
return SplitConfig(mode=SplitMode.DEFAULT, max_chunk_size=1800, overlap=120)
|
||||
|
||||
return SplitConfig(mode=SplitMode.DEFAULT, max_chunk_size=2200, overlap=120)
|
||||
|
||||
|
||||
def split_config_summary(config: SplitConfig) -> dict[str, int | str | None]:
|
||||
return {
|
||||
"mode": config.mode.value,
|
||||
"delimiter": config.delimiter,
|
||||
"parent_delimiter": config.parent_delimiter,
|
||||
"child_delimiter": config.child_delimiter,
|
||||
"max_chunk_size": config.max_chunk_size,
|
||||
"child_max_size": config.child_max_size,
|
||||
"overlap": config.overlap,
|
||||
"header_row_start": config.header_row_start,
|
||||
"header_row_end": config.header_row_end,
|
||||
"start_row": config.start_row,
|
||||
"rows_per_chunk": config.rows_per_chunk,
|
||||
}
|
||||
@@ -0,0 +1,8 @@
|
||||
"""Chunk splitting strategies."""
|
||||
|
||||
from rag_cut.splitters.by_row import split_by_row
|
||||
from rag_cut.splitters.default_splitter import split_default
|
||||
from rag_cut.splitters.delimiter import split_by_delimiter
|
||||
from rag_cut.splitters.parent_child import split_by_parent_child
|
||||
|
||||
__all__ = ["split_default", "split_by_delimiter", "split_by_parent_child", "split_by_row"]
|
||||
@@ -0,0 +1,87 @@
|
||||
"""Row-based splitting for spreadsheet documents."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
from rag_cut.models import Block, BlockType, SplitConfig
|
||||
from rag_cut.parsers.pdf.tables import (
|
||||
build_table_embedding_text,
|
||||
detect_spreadsheet_layout,
|
||||
extract_table_keywords,
|
||||
rows_to_markdown,
|
||||
)
|
||||
|
||||
|
||||
def _chunk_meta(table_block: Block, chunk_rows: list[list[str]], md: str, row_range: list[int]) -> dict:
|
||||
"""Build per-chunk metadata without leaking the full source table."""
|
||||
header_rows = table_block.meta.get("header_rows") or 1
|
||||
keywords = extract_table_keywords(
|
||||
table_block.meta.get("table_title") or "",
|
||||
md,
|
||||
table_block.meta.get("table_description") or "",
|
||||
)
|
||||
embedding_text = build_table_embedding_text(
|
||||
table_title=table_block.meta.get("table_title") or "",
|
||||
markdown=md,
|
||||
description=table_block.meta.get("table_description") or "",
|
||||
keywords=keywords,
|
||||
)
|
||||
return {
|
||||
"sheet": table_block.meta.get("sheet"),
|
||||
"table_title": table_block.meta.get("table_title"),
|
||||
"table_description": table_block.meta.get("table_description"),
|
||||
"header_rows": header_rows,
|
||||
"header_row_start": table_block.meta.get("header_row_start"),
|
||||
"header_row_end": table_block.meta.get("header_row_end"),
|
||||
"data_start_row": table_block.meta.get("data_start_row"),
|
||||
"preamble_rows": table_block.meta.get("preamble_rows", 0),
|
||||
"row_count": len(chunk_rows),
|
||||
"col_count": max((len(r) for r in chunk_rows), default=0),
|
||||
"chunk_rows": chunk_rows,
|
||||
"row_range": row_range,
|
||||
"keywords": keywords,
|
||||
"embedding_text": embedding_text,
|
||||
}
|
||||
|
||||
|
||||
def split_by_row(blocks: list[Block], config: SplitConfig) -> list[list[Block]]:
|
||||
table_block = next((b for b in blocks if b.type == BlockType.TABLE and b.meta.get("rows")), None)
|
||||
if not table_block:
|
||||
return [blocks] if blocks else []
|
||||
|
||||
rows: list[list[str]] = table_block.meta["rows"]
|
||||
layout = {
|
||||
"header_row_start": table_block.meta.get("header_row_start"),
|
||||
"header_row_end": table_block.meta.get("header_row_end"),
|
||||
"data_start_row": table_block.meta.get("data_start_row"),
|
||||
"header_rows": table_block.meta.get("header_rows"),
|
||||
}
|
||||
if not layout["header_row_start"]:
|
||||
layout = detect_spreadsheet_layout(rows)
|
||||
|
||||
h_start = max(1, config.header_row_start) - 1
|
||||
h_end = max(h_start + 1, config.header_row_end)
|
||||
header = rows[h_start:h_end]
|
||||
header_rows = layout.get("header_rows") or len(header)
|
||||
data_start = max(config.start_row - 1, h_end)
|
||||
data_rows = rows[data_start:]
|
||||
rows_per = max(1, config.rows_per_chunk)
|
||||
|
||||
groups: list[list[Block]] = []
|
||||
for i in range(0, len(data_rows), rows_per):
|
||||
slice_rows = data_rows[i : i + rows_per]
|
||||
chunk_rows = header + slice_rows
|
||||
md = rows_to_markdown(chunk_rows, header_rows=header_rows)
|
||||
row_range = [
|
||||
data_start + i + 1,
|
||||
data_start + i + len(slice_rows),
|
||||
]
|
||||
groups.append(
|
||||
[
|
||||
Block(
|
||||
type=BlockType.TABLE,
|
||||
markdown=md,
|
||||
meta=_chunk_meta(table_block, chunk_rows, md, row_range),
|
||||
)
|
||||
]
|
||||
)
|
||||
return groups
|
||||
@@ -0,0 +1,210 @@
|
||||
"""Default structure-aware splitting."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
from rag_cut.models import Block, BlockType, SplitConfig
|
||||
from rag_cut.splitters.heading_splitter import (
|
||||
chunk_groups_to_block_groups,
|
||||
has_meaningful_headings,
|
||||
split_by_heading_hierarchy,
|
||||
)
|
||||
|
||||
ATOMIC_TYPES = {BlockType.TABLE, BlockType.IMAGE}
|
||||
|
||||
|
||||
def _same_layout_context(prev: Block, curr: Block) -> bool:
|
||||
"""True when blocks should stay together to preserve image/text position."""
|
||||
if prev.meta.get("page") != curr.meta.get("page"):
|
||||
return False
|
||||
if prev.type == BlockType.PARAGRAPH and curr.type in {BlockType.IMAGE, BlockType.TABLE}:
|
||||
return True
|
||||
if prev.type == BlockType.HEADING and curr.type in {BlockType.PARAGRAPH, BlockType.IMAGE, BlockType.TABLE}:
|
||||
return prev.meta.get("parent_heading") == curr.meta.get("parent_heading") or not prev.meta.get("parent_heading")
|
||||
if prev.type == BlockType.IMAGE and curr.type == BlockType.PARAGRAPH:
|
||||
return True
|
||||
if prev.type == BlockType.TABLE and curr.type == BlockType.PARAGRAPH:
|
||||
return True
|
||||
if prev.type == BlockType.IMAGE and curr.type == BlockType.IMAGE:
|
||||
return True
|
||||
return False
|
||||
|
||||
|
||||
def _is_heading(block: Block) -> bool:
|
||||
return block.type == BlockType.HEADING
|
||||
|
||||
|
||||
def _meaningful_headings(blocks: list[Block]) -> bool:
|
||||
headings = [b for b in blocks if _is_heading(b)]
|
||||
if len(headings) < 2:
|
||||
return False
|
||||
substantial = [h for h in headings if len((h.text or "").strip()) >= 8]
|
||||
return len(substantial) >= 2
|
||||
|
||||
|
||||
def _split_by_headings(blocks: list[Block]) -> list[list[Block]]:
|
||||
"""Outline-aware: split when a heading of same-or-higher level appears."""
|
||||
if not any(_is_heading(b) for b in blocks):
|
||||
return []
|
||||
|
||||
sections: list[list[Block]] = []
|
||||
current: list[Block] = []
|
||||
stack: list[int] = []
|
||||
|
||||
for block in blocks:
|
||||
if _is_heading(block):
|
||||
level = block.level or 1
|
||||
while stack and stack[-1] >= level:
|
||||
stack.pop()
|
||||
if current:
|
||||
sections.append(current)
|
||||
current = []
|
||||
stack.append(level)
|
||||
current.append(block)
|
||||
else:
|
||||
current.append(block)
|
||||
|
||||
if current:
|
||||
sections.append(current)
|
||||
return sections
|
||||
|
||||
|
||||
def _split_by_page(blocks: list[Block], config: SplitConfig) -> list[list[Block]]:
|
||||
"""Prefer page boundaries for PDF/manual style documents."""
|
||||
if not any(b.meta.get("page") for b in blocks):
|
||||
return []
|
||||
|
||||
groups: list[list[Block]] = []
|
||||
current: list[Block] = []
|
||||
current_page: int | None = None
|
||||
|
||||
for block in blocks:
|
||||
page = block.meta.get("page")
|
||||
if current and page != current_page:
|
||||
groups.append(current)
|
||||
current = []
|
||||
current_page = page
|
||||
current.append(block)
|
||||
|
||||
if current:
|
||||
groups.append(current)
|
||||
|
||||
return _merge_oversized_sections(groups, config)
|
||||
|
||||
|
||||
def _split_by_size(blocks: list[Block], config: SplitConfig) -> list[list[Block]]:
|
||||
"""Fallback: pack blocks up to max_chunk_size without splitting atomic blocks."""
|
||||
groups: list[list[Block]] = []
|
||||
current: list[Block] = []
|
||||
current_len = 0
|
||||
|
||||
def flush() -> None:
|
||||
nonlocal current, current_len
|
||||
if current:
|
||||
groups.append(current)
|
||||
current = []
|
||||
current_len = 0
|
||||
|
||||
for block in blocks:
|
||||
rendered = block.render()
|
||||
block_len = len(rendered) + 2
|
||||
page = block.meta.get("page")
|
||||
|
||||
if block.type in ATOMIC_TYPES and current_len + block_len > config.max_chunk_size and current:
|
||||
if not _same_layout_context(current[-1], block):
|
||||
flush()
|
||||
|
||||
if block.type not in ATOMIC_TYPES and block_len > config.max_chunk_size:
|
||||
if current:
|
||||
flush()
|
||||
text = block.text or block.markdown
|
||||
start = 0
|
||||
while start < len(text):
|
||||
end = min(start + config.max_chunk_size, len(text))
|
||||
piece = Block(type=block.type, text=text[start:end], level=block.level, meta=block.meta)
|
||||
groups.append([piece])
|
||||
if end >= len(text):
|
||||
break
|
||||
start = max(end - config.overlap, start + 1)
|
||||
continue
|
||||
|
||||
if current_len + block_len > config.max_chunk_size and current:
|
||||
# Keep image with preceding heading/body on the same page
|
||||
if _same_layout_context(current[-1], block):
|
||||
pass
|
||||
else:
|
||||
flush()
|
||||
elif (
|
||||
current
|
||||
and page is not None
|
||||
and current[-1].meta.get("page") != page
|
||||
and current_len >= min(400, config.max_chunk_size // 3)
|
||||
):
|
||||
flush()
|
||||
|
||||
current.append(block)
|
||||
current_len += block_len
|
||||
|
||||
flush()
|
||||
return groups
|
||||
|
||||
|
||||
def _merge_oversized_sections(sections: list[list[Block]], config: SplitConfig) -> list[list[Block]]:
|
||||
result: list[list[Block]] = []
|
||||
for section in sections:
|
||||
rendered_len = sum(len(b.render()) + 2 for b in section)
|
||||
if rendered_len <= config.max_chunk_size:
|
||||
result.append(section)
|
||||
else:
|
||||
result.extend(_split_by_size(section, config))
|
||||
return result
|
||||
|
||||
|
||||
def split_default(blocks: list[Block], config: SplitConfig) -> list[list[Block]]:
|
||||
if not blocks:
|
||||
return []
|
||||
|
||||
# Spreadsheet: single table block — default = chunk by groups of rows with header
|
||||
if len(blocks) == 1 and blocks[0].type == BlockType.TABLE and blocks[0].meta.get("rows"):
|
||||
from rag_cut.splitters.by_row import split_by_row
|
||||
|
||||
row_config = SplitConfig(
|
||||
mode=config.mode,
|
||||
header_row_start=1,
|
||||
header_row_end=1,
|
||||
start_row=2,
|
||||
rows_per_chunk=max(1, min(10, len(blocks[0].meta["rows"]) // 5 or 1)),
|
||||
max_chunk_size=config.max_chunk_size,
|
||||
overlap=config.overlap,
|
||||
)
|
||||
return split_by_row(blocks, row_config)
|
||||
|
||||
# Heading hierarchy first: same section keeps body/images/tables/captions together
|
||||
if has_meaningful_headings(blocks):
|
||||
heading_groups = split_by_heading_hierarchy(blocks, config)
|
||||
if heading_groups:
|
||||
block_groups, _ = chunk_groups_to_block_groups(heading_groups)
|
||||
return block_groups
|
||||
|
||||
page_sections = _split_by_page(blocks, config)
|
||||
if len(page_sections) > 1:
|
||||
return page_sections
|
||||
|
||||
return _split_by_size(blocks, config)
|
||||
|
||||
|
||||
def split_default_with_meta(blocks: list[Block], config: SplitConfig) -> tuple[list[list[Block]], list[dict]]:
|
||||
"""Like split_default but also returns per-group metadata (heading sections)."""
|
||||
if not blocks:
|
||||
return [], []
|
||||
|
||||
if len(blocks) == 1 and blocks[0].type == BlockType.TABLE and blocks[0].meta.get("rows"):
|
||||
groups = split_default(blocks, config)
|
||||
return groups, [{} for _ in groups]
|
||||
|
||||
if has_meaningful_headings(blocks):
|
||||
heading_groups = split_by_heading_hierarchy(blocks, config)
|
||||
if heading_groups:
|
||||
return chunk_groups_to_block_groups(heading_groups)
|
||||
|
||||
groups = split_default(blocks, config)
|
||||
return groups, [{} for _ in groups]
|
||||
@@ -0,0 +1,63 @@
|
||||
"""Delimiter-based splitting for non-tabular documents."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
from rag_cut.models import Block, BlockType, SplitConfig
|
||||
from rag_cut.splitters.default_splitter import _split_by_size
|
||||
|
||||
ATOMIC_TYPES = {BlockType.TABLE, BlockType.IMAGE}
|
||||
|
||||
|
||||
def partition_blocks_by_delimiter(blocks: list[Block], delimiter: str) -> list[list[Block]]:
|
||||
"""Split block stream on delimiter; delimiter text is discarded from chunks."""
|
||||
if not delimiter:
|
||||
return [blocks] if blocks else []
|
||||
|
||||
groups: list[list[Block]] = []
|
||||
current: list[Block] = []
|
||||
|
||||
def flush() -> None:
|
||||
nonlocal current
|
||||
if current:
|
||||
groups.append(current)
|
||||
current = []
|
||||
|
||||
for block in blocks:
|
||||
if block.type in ATOMIC_TYPES:
|
||||
current.append(block)
|
||||
continue
|
||||
|
||||
text = block.text or block.markdown
|
||||
if delimiter not in text:
|
||||
current.append(block)
|
||||
continue
|
||||
|
||||
parts = text.split(delimiter)
|
||||
for i, part in enumerate(parts):
|
||||
part = part.strip()
|
||||
if part:
|
||||
piece = Block(type=block.type, text=part, level=block.level, meta=dict(block.meta))
|
||||
current.append(piece)
|
||||
if i < len(parts) - 1:
|
||||
flush()
|
||||
|
||||
flush()
|
||||
return groups
|
||||
|
||||
|
||||
def split_by_delimiter(blocks: list[Block], config: SplitConfig) -> list[list[Block]]:
|
||||
if not config.delimiter:
|
||||
raise ValueError("delimiter is required for delimiter split mode")
|
||||
|
||||
groups = partition_blocks_by_delimiter(blocks, config.delimiter)
|
||||
if not groups:
|
||||
return _split_by_size(blocks, config)
|
||||
|
||||
sized: list[list[Block]] = []
|
||||
for group in groups:
|
||||
rendered_len = sum(len(b.render()) + 2 for b in group)
|
||||
if rendered_len <= config.max_chunk_size:
|
||||
sized.append(group)
|
||||
else:
|
||||
sized.extend(_split_by_size(group, config))
|
||||
return sized
|
||||
@@ -0,0 +1,344 @@
|
||||
"""Heading-hierarchy-first document splitting."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import re
|
||||
from dataclasses import dataclass, field
|
||||
|
||||
from rag_cut.models import Block, BlockType, SplitConfig
|
||||
|
||||
# e.g. "1.2 ACCOUNT STATUS CODE MASTER", "10.上升三角形態" (space after '.' optional)
|
||||
NUMBERED_HEADING_RE = re.compile(
|
||||
r"^\s*(\d+(?:\.\d+)*)(?:\.|.)?\s*([A-Za-z0-9\u4e00-\u9fff][A-Za-z0-9\u4e00-\u9fff&/ \-_::]{2,})\s*$"
|
||||
)
|
||||
FIGURE_TABLE_RE = re.compile(
|
||||
r"^\s*(?:Figure|Fig\.|图|表|Table)\s*[\d.]+",
|
||||
re.I,
|
||||
)
|
||||
STEP_RE = re.compile(
|
||||
r"^\s*(?:Step\s*\d+|步骤\s*\d+|\d{1,2}[..、]\s*(?:点击|點擊|选择|選擇|输入|輸入))",
|
||||
re.I,
|
||||
)
|
||||
ATOMIC_TYPES = {BlockType.TABLE, BlockType.IMAGE}
|
||||
MAX_HEADING_CHARS = 100
|
||||
|
||||
|
||||
@dataclass
|
||||
class ChunkGroup:
|
||||
blocks: list[Block]
|
||||
meta: dict = field(default_factory=dict)
|
||||
|
||||
|
||||
def _text(block: Block) -> str:
|
||||
return (block.text or block.markdown or "").strip()
|
||||
|
||||
|
||||
def _rendered_len(blocks: list[Block]) -> int:
|
||||
return sum(len(b.render()) + 2 for b in blocks)
|
||||
|
||||
|
||||
def numbered_heading_level(text: str) -> int | None:
|
||||
match = NUMBERED_HEADING_RE.match(text.strip())
|
||||
if not match:
|
||||
return None
|
||||
return match.group(1).count(".") + 1
|
||||
|
||||
|
||||
def infer_heading_level(block: Block) -> int:
|
||||
if block.type == BlockType.HEADING and block.level:
|
||||
numbered = numbered_heading_level(block.text)
|
||||
if numbered:
|
||||
return numbered
|
||||
return block.level
|
||||
numbered = numbered_heading_level(_text(block))
|
||||
if numbered:
|
||||
return numbered
|
||||
return block.level or 1
|
||||
|
||||
|
||||
def is_heading_block(block: Block) -> bool:
|
||||
text = _text(block)
|
||||
if not text or len(text) > MAX_HEADING_CHARS:
|
||||
return False
|
||||
if block.type == BlockType.HEADING:
|
||||
return True
|
||||
if NUMBERED_HEADING_RE.match(text):
|
||||
return True
|
||||
if block.meta.get("font_size") and block.meta.get("body_font_size"):
|
||||
return block.meta["font_size"] >= block.meta["body_font_size"] + 1.5
|
||||
return False
|
||||
|
||||
|
||||
def normalize_heading_block(block: Block) -> Block:
|
||||
text = _text(block)
|
||||
if block.type == BlockType.HEADING and len(text) > MAX_HEADING_CHARS:
|
||||
# Parser sometimes merges title+body then marks the blob as heading.
|
||||
return Block(type=BlockType.PARAGRAPH, text=text, meta=dict(block.meta))
|
||||
numbered = numbered_heading_level(text)
|
||||
if block.type == BlockType.HEADING:
|
||||
level = numbered or block.level or 1
|
||||
return block.model_copy(update={"level": level})
|
||||
if numbered and NUMBERED_HEADING_RE.match(text):
|
||||
return Block(
|
||||
type=BlockType.HEADING,
|
||||
text=text,
|
||||
level=numbered,
|
||||
meta=dict(block.meta),
|
||||
)
|
||||
return block
|
||||
|
||||
|
||||
def has_meaningful_headings(blocks: list[Block]) -> bool:
|
||||
headings = [normalize_heading_block(b) for b in blocks]
|
||||
count = sum(1 for b in headings if is_heading_block(b) or b.type == BlockType.HEADING)
|
||||
return count >= 2
|
||||
|
||||
|
||||
def _section_key(block: Block | None, fallback: int) -> str:
|
||||
if block is None:
|
||||
return f"section-{fallback}"
|
||||
oi = block.meta.get("order_index", fallback)
|
||||
title = re.sub(r"\W+", "-", (_text(block) or "heading"))[:48]
|
||||
return f"h-{oi}-{title}"
|
||||
|
||||
|
||||
@dataclass
|
||||
class _OpenSection:
|
||||
level: int
|
||||
start_index: int
|
||||
blocks: list[Block]
|
||||
|
||||
|
||||
def _split_primary_sections(blocks: list[Block]) -> list[list[Block]]:
|
||||
"""
|
||||
Split so each heading owns its content until the next same-or-higher-level heading.
|
||||
Example: 1.2 section runs until 1.3 (same level) or 2.0 (higher level).
|
||||
Nested sub-headings (1.2.1) stay inside the 1.2 section.
|
||||
"""
|
||||
if not blocks:
|
||||
return []
|
||||
|
||||
open_sections: list[_OpenSection] = []
|
||||
finished: list[tuple[int, list[Block]]] = []
|
||||
|
||||
for raw in blocks:
|
||||
block = normalize_heading_block(raw)
|
||||
if is_heading_block(block) or block.type == BlockType.HEADING:
|
||||
level = infer_heading_level(block)
|
||||
while open_sections and open_sections[-1].level >= level:
|
||||
sec = open_sections.pop()
|
||||
finished.append((sec.start_index, sec.blocks))
|
||||
start = int(block.meta.get("order_index", len(finished)))
|
||||
open_sections.append(_OpenSection(level=level, start_index=start, blocks=[block]))
|
||||
elif open_sections:
|
||||
open_sections[-1].blocks.append(block)
|
||||
|
||||
while open_sections:
|
||||
sec = open_sections.pop()
|
||||
finished.append((sec.start_index, sec.blocks))
|
||||
|
||||
finished.sort(key=lambda item: item[0])
|
||||
return [sec_blocks for _, sec_blocks in finished]
|
||||
|
||||
|
||||
def _section_heading(section: list[Block]) -> Block | None:
|
||||
for block in section:
|
||||
nb = normalize_heading_block(block)
|
||||
if nb.type == BlockType.HEADING or is_heading_block(nb):
|
||||
return nb
|
||||
return None
|
||||
|
||||
|
||||
def _split_by_child_headings(section: list[Block], parent_level: int) -> list[list[Block]]:
|
||||
"""Split an oversized section by deeper sub-headings."""
|
||||
child_sections: list[list[Block]] = []
|
||||
current: list[Block] = []
|
||||
parent_heading = _section_heading(section)
|
||||
|
||||
for block in section:
|
||||
nb = normalize_heading_block(block)
|
||||
if (
|
||||
block is not parent_heading
|
||||
and (nb.type == BlockType.HEADING or is_heading_block(nb))
|
||||
and infer_heading_level(nb) > parent_level
|
||||
):
|
||||
if current:
|
||||
child_sections.append(current)
|
||||
current = [block]
|
||||
else:
|
||||
current.append(block)
|
||||
|
||||
if current:
|
||||
child_sections.append(current)
|
||||
return child_sections if len(child_sections) > 1 else [section]
|
||||
|
||||
|
||||
def _is_split_marker(block: Block) -> bool:
|
||||
if block.type in ATOMIC_TYPES:
|
||||
return False
|
||||
text = _text(block)
|
||||
if not text:
|
||||
return False
|
||||
return bool(FIGURE_TABLE_RE.match(text) or STEP_RE.match(text))
|
||||
|
||||
|
||||
def _split_by_content_markers(section: list[Block], config: SplitConfig) -> list[list[Block]]:
|
||||
"""Fallback: split at figure/table/step markers while keeping atomic blocks intact."""
|
||||
if _rendered_len(section) <= config.max_chunk_size:
|
||||
return [section]
|
||||
|
||||
groups: list[list[Block]] = []
|
||||
current: list[Block] = []
|
||||
current_len = 0
|
||||
|
||||
def flush() -> None:
|
||||
nonlocal current, current_len
|
||||
if current:
|
||||
groups.append(current)
|
||||
current = []
|
||||
current_len = 0
|
||||
|
||||
for block in section:
|
||||
blen = len(block.render()) + 2
|
||||
if (
|
||||
current
|
||||
and _is_split_marker(block)
|
||||
and current_len >= min(500, config.max_chunk_size // 4)
|
||||
and current_len + blen > config.max_chunk_size
|
||||
):
|
||||
flush()
|
||||
elif current_len + blen > config.max_chunk_size and current:
|
||||
if block.type in ATOMIC_TYPES:
|
||||
flush()
|
||||
elif not _is_split_marker(block):
|
||||
flush()
|
||||
|
||||
current.append(block)
|
||||
current_len += blen
|
||||
|
||||
flush()
|
||||
return groups if groups else [section]
|
||||
|
||||
|
||||
def _prepend_parent_heading(section: list[Block], parent: Block | None) -> list[Block]:
|
||||
if not parent:
|
||||
return section
|
||||
parent_text = _text(parent)
|
||||
if section and _text(normalize_heading_block(section[0])) == parent_text:
|
||||
return section
|
||||
return [parent] + section
|
||||
|
||||
|
||||
def _split_oversized_section(
|
||||
section: list[Block],
|
||||
config: SplitConfig,
|
||||
section_id: str,
|
||||
) -> list[ChunkGroup]:
|
||||
"""Split an oversized heading section by sub-headings/markers/size — no parent chunk."""
|
||||
parent_heading = _section_heading(section)
|
||||
parent_level = infer_heading_level(parent_heading) if parent_heading else 1
|
||||
parent_title = _text(parent_heading) if parent_heading else ""
|
||||
|
||||
child_sections = _split_by_child_headings(section, parent_level)
|
||||
if len(child_sections) == 1:
|
||||
child_sections = _split_by_content_markers(section, config)
|
||||
if len(child_sections) == 1:
|
||||
from rag_cut.splitters.default_splitter import _split_by_size
|
||||
|
||||
child_sections = _split_by_size(section, config)
|
||||
|
||||
parts: list[ChunkGroup] = []
|
||||
for idx, child in enumerate(child_sections):
|
||||
child_heading = _section_heading(child)
|
||||
blocks = _prepend_parent_heading(child, parent_heading)
|
||||
parts.append(
|
||||
ChunkGroup(
|
||||
blocks=blocks,
|
||||
meta={
|
||||
"section_id": f"{section_id}-part-{idx}",
|
||||
"heading": _text(child_heading) if child_heading else parent_title,
|
||||
"heading_level": infer_heading_level(child_heading) if child_heading else parent_level,
|
||||
"parent_heading": parent_title,
|
||||
"chunk_strategy": "heading_hierarchy_part",
|
||||
"part_index": idx,
|
||||
"is_sub_chunk": False,
|
||||
"retrieval": True,
|
||||
},
|
||||
)
|
||||
)
|
||||
return parts
|
||||
|
||||
|
||||
def split_by_heading_hierarchy(blocks: list[Block], config: SplitConfig) -> list[ChunkGroup]:
|
||||
"""
|
||||
Heading-first splitting:
|
||||
- Same heading section stays together (body, images, tables, captions).
|
||||
- Boundaries at same/higher-level headings.
|
||||
- Oversized sections are split by sub-headings / markers / length (no parent+child pair).
|
||||
"""
|
||||
if not blocks:
|
||||
return []
|
||||
|
||||
if not has_meaningful_headings(blocks):
|
||||
return []
|
||||
|
||||
groups: list[ChunkGroup] = []
|
||||
sections = _split_primary_sections(blocks)
|
||||
|
||||
for i, section in enumerate(sections):
|
||||
heading = _section_heading(section)
|
||||
sid = _section_key(heading, i)
|
||||
title = _text(heading) if heading else ""
|
||||
level = infer_heading_level(heading) if heading else 1
|
||||
|
||||
if _rendered_len(section) <= config.max_chunk_size:
|
||||
groups.append(
|
||||
ChunkGroup(
|
||||
blocks=section,
|
||||
meta={
|
||||
"section_id": sid,
|
||||
"heading": title,
|
||||
"heading_level": level,
|
||||
"is_sub_chunk": False,
|
||||
"chunk_strategy": "heading_hierarchy",
|
||||
"retrieval": True,
|
||||
"order_range": [
|
||||
section[0].meta.get("order_index"),
|
||||
section[-1].meta.get("order_index"),
|
||||
],
|
||||
},
|
||||
)
|
||||
)
|
||||
continue
|
||||
|
||||
groups.extend(_split_oversized_section(section, config, sid))
|
||||
|
||||
return groups
|
||||
|
||||
|
||||
def chunk_groups_to_block_groups(groups: list[ChunkGroup]) -> tuple[list[list[Block]], list[dict]]:
|
||||
"""Convert ChunkGroups to block groups + per-chunk meta for renderer."""
|
||||
block_groups: list[list[Block]] = []
|
||||
metas: list[dict] = []
|
||||
for group in groups:
|
||||
block_groups.append(group.blocks)
|
||||
metas.append(group.meta)
|
||||
return block_groups, metas
|
||||
|
||||
|
||||
def assign_parent_chunk_ids(chunks: list) -> list:
|
||||
"""Resolve parent_section_id -> parent_chunk_id (chunk index)."""
|
||||
section_index: dict[str, int] = {}
|
||||
for i, chunk in enumerate(chunks):
|
||||
sid = chunk.meta.get("section_id")
|
||||
if sid and chunk.meta.get("is_section_parent"):
|
||||
section_index[sid] = i
|
||||
|
||||
updated = []
|
||||
for chunk in chunks:
|
||||
meta = dict(chunk.meta)
|
||||
parent_sid = meta.get("parent_section_id")
|
||||
if parent_sid and parent_sid in section_index:
|
||||
meta["parent_chunk_id"] = section_index[parent_sid]
|
||||
updated.append(chunk.model_copy(update={"meta": meta}))
|
||||
return updated
|
||||
@@ -0,0 +1,103 @@
|
||||
"""Parent/child delimiter splitting for fine retrieval + coarse recall."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
from rag_cut.models import Block, SplitConfig
|
||||
from rag_cut.splitters.default_splitter import _split_by_size
|
||||
from rag_cut.splitters.delimiter import partition_blocks_by_delimiter
|
||||
from rag_cut.splitters.heading_splitter import ChunkGroup
|
||||
|
||||
CHUNK_STRATEGY = "parent_child_delimiter"
|
||||
CHILD_MAX_HARD_LIMIT = 1500
|
||||
|
||||
|
||||
def _rendered_len(blocks: list[Block]) -> int:
|
||||
return sum(len(b.render()) + 2 for b in blocks)
|
||||
|
||||
|
||||
def _validate(config: SplitConfig) -> tuple[str, str | None, int, int]:
|
||||
parent_delimiter = (config.parent_delimiter or config.delimiter or "").strip()
|
||||
if not parent_delimiter:
|
||||
raise ValueError("parent_delimiter is required for parent_child split mode")
|
||||
|
||||
child_delimiter = (config.child_delimiter or "").strip() or None
|
||||
parent_max = max(200, int(config.max_chunk_size or 1500))
|
||||
child_max = int(config.child_max_size or 512)
|
||||
child_max = max(50, min(child_max, CHILD_MAX_HARD_LIMIT, parent_max))
|
||||
return parent_delimiter, child_delimiter, parent_max, child_max
|
||||
|
||||
|
||||
def _size_cap(groups: list[list[Block]], max_size: int, overlap: int) -> list[list[Block]]:
|
||||
sized: list[list[Block]] = []
|
||||
size_config = SplitConfig(max_chunk_size=max_size, overlap=overlap)
|
||||
for group in groups:
|
||||
if _rendered_len(group) <= max_size:
|
||||
sized.append(group)
|
||||
else:
|
||||
sized.extend(_split_by_size(group, size_config))
|
||||
return sized or groups
|
||||
|
||||
|
||||
def split_by_parent_child(blocks: list[Block], config: SplitConfig) -> list[ChunkGroup]:
|
||||
"""
|
||||
Split into parent chunks (context) and child chunks (retrieval).
|
||||
|
||||
1. Partition by parent_delimiter (then cap by parent max length).
|
||||
2. For each parent: keep a full parent chunk (retrieval=false).
|
||||
3. Partition parent by child_delimiter (or by length) into children
|
||||
capped by child_max_size (retrieval=true, linked via parent_section_id).
|
||||
"""
|
||||
if not blocks:
|
||||
return []
|
||||
|
||||
parent_delimiter, child_delimiter, parent_max, child_max = _validate(config)
|
||||
overlap = max(0, int(config.overlap or 0))
|
||||
|
||||
parents = partition_blocks_by_delimiter(blocks, parent_delimiter)
|
||||
if not parents:
|
||||
parents = [blocks]
|
||||
parents = _size_cap(parents, parent_max, overlap)
|
||||
|
||||
groups: list[ChunkGroup] = []
|
||||
for parent_idx, parent_blocks in enumerate(parents):
|
||||
section_id = f"pc-{parent_idx}"
|
||||
groups.append(
|
||||
ChunkGroup(
|
||||
blocks=list(parent_blocks),
|
||||
meta={
|
||||
"section_id": section_id,
|
||||
"is_section_parent": True,
|
||||
"is_sub_chunk": False,
|
||||
"retrieval": False,
|
||||
"chunk_strategy": f"{CHUNK_STRATEGY}_parent",
|
||||
"parent_index": parent_idx,
|
||||
},
|
||||
)
|
||||
)
|
||||
|
||||
if child_delimiter:
|
||||
children = partition_blocks_by_delimiter(parent_blocks, child_delimiter)
|
||||
else:
|
||||
children = [parent_blocks]
|
||||
if not children:
|
||||
children = [parent_blocks]
|
||||
children = _size_cap(children, child_max, overlap)
|
||||
|
||||
for child_idx, child_blocks in enumerate(children):
|
||||
groups.append(
|
||||
ChunkGroup(
|
||||
blocks=list(child_blocks),
|
||||
meta={
|
||||
"section_id": f"{section_id}-sub-{child_idx}",
|
||||
"parent_section_id": section_id,
|
||||
"is_section_parent": False,
|
||||
"is_sub_chunk": True,
|
||||
"retrieval": True,
|
||||
"chunk_strategy": f"{CHUNK_STRATEGY}_child",
|
||||
"parent_index": parent_idx,
|
||||
"sub_chunk_index": child_idx,
|
||||
},
|
||||
)
|
||||
)
|
||||
|
||||
return groups
|
||||
@@ -0,0 +1,427 @@
|
||||
"""Generic heading/layout multimodal splitter for PDF-derived documents."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import re
|
||||
from dataclasses import dataclass, field
|
||||
|
||||
from rag_cut.models import Block, BlockType, Chunk, SplitConfig
|
||||
from rag_cut.parsers.pdf.noise_filter import is_toc_noise_text, is_toc_title_text
|
||||
from rag_cut.renderer import collect_chunk_layout_meta, render_blocks
|
||||
|
||||
CHUNK_STRATEGY = "heading_layout_multimodal"
|
||||
|
||||
PAGE_NUMBER_RE = re.compile(r"^\s*(?:[-\u2013\u2014]?\s*)?\d{1,4}(?:\s*/\s*\d{1,4})?\s*$")
|
||||
NUMBERED_HEADING_RE = re.compile(
|
||||
r"^\s*(?P<num>\d+(?:\.\d+)*)(?:\.|.)?\s*(?P<title>[A-Za-z0-9\u4e00-\u9fff][^\n]{1,120})\s*$"
|
||||
)
|
||||
LETTER_HEADING_RE = re.compile(
|
||||
r"^\s*(?P<letter>[A-Z])[\.)]\s+(?P<title>[A-Za-z0-9\u4e00-\u9fff][^\n]{1,100})\s*$"
|
||||
)
|
||||
# Procedural "Step N …" lines are body content, not section boundaries.
|
||||
# Promoting them to headings caused heading-only groups to be dropped on flush
|
||||
# (e.g. Steps 1–3 under 5.7.1 vanished while only Step 4 with following body survived).
|
||||
STEP_INSTRUCTION_RE = re.compile(
|
||||
r"^\s*(?:Step\s*\d+|STEP\s*\d+|步骤\s*\d+)(?:\s*[:.:)\-]?\s+\S|\s*$)",
|
||||
re.I,
|
||||
)
|
||||
CHAPTER_HEADING_RE = re.compile(r"^\s*Chapter\s+\d+(?:\s*[:.-]?\s+[^\n]{1,100})?\s*$", re.I)
|
||||
CN_HEADING_RE = re.compile(
|
||||
r"^\s*(?:[\u4e00-\u9fff]{1,3}[、..]|[((][\u4e00-\u9fff]{1,3}[))])\s*[^\n]{1,100}$"
|
||||
)
|
||||
|
||||
|
||||
@dataclass
|
||||
class _Group:
|
||||
heading_path: list[str] = field(default_factory=list)
|
||||
blocks: list[Block] = field(default_factory=list)
|
||||
|
||||
|
||||
@dataclass
|
||||
class _HeadingSignal:
|
||||
text: str
|
||||
level: int
|
||||
|
||||
|
||||
def _text(block: Block) -> str:
|
||||
return (block.text or block.markdown or "").strip()
|
||||
|
||||
|
||||
def _page(block: Block) -> int | None:
|
||||
page = block.meta.get("page")
|
||||
try:
|
||||
return int(page) if page is not None else None
|
||||
except (TypeError, ValueError):
|
||||
return None
|
||||
|
||||
|
||||
def _bbox(block: Block) -> list[float]:
|
||||
bbox = block.meta.get("bbox")
|
||||
return list(bbox) if isinstance(bbox, (list, tuple)) else []
|
||||
|
||||
|
||||
def _copy_with_meta(block: Block, **meta_updates) -> Block:
|
||||
meta = dict(block.meta)
|
||||
meta.update({k: v for k, v in meta_updates.items() if v not in (None, [], {})})
|
||||
return block.model_copy(update={"meta": meta})
|
||||
|
||||
|
||||
def _is_empty_text_block(block: Block) -> bool:
|
||||
return block.type not in {BlockType.IMAGE, BlockType.TABLE} and not _text(block)
|
||||
|
||||
|
||||
def _is_toc_text(text: str) -> bool:
|
||||
return is_toc_noise_text(text) or is_toc_title_text(text)
|
||||
|
||||
|
||||
def _is_decorative_image(block: Block) -> bool:
|
||||
bbox = _bbox(block)
|
||||
if len(bbox) != 4:
|
||||
return False
|
||||
width = bbox[2] - bbox[0]
|
||||
height = bbox[3] - bbox[1]
|
||||
if width <= 0 or height <= 0:
|
||||
return True
|
||||
if width < 28 or height < 16:
|
||||
return True
|
||||
page_height = block.meta.get("page_height") or 0
|
||||
if page_height and bbox[3] <= page_height * 0.10 and width * height < 12000:
|
||||
return True
|
||||
return False
|
||||
|
||||
|
||||
def _is_margin_noise(block: Block) -> bool:
|
||||
if block.type == BlockType.HEADING:
|
||||
return False
|
||||
text = _text(block)
|
||||
bbox = _bbox(block)
|
||||
page_height = block.meta.get("page_height") or 0
|
||||
if not bbox or not page_height:
|
||||
return False
|
||||
y0, y1 = bbox[1], bbox[3]
|
||||
in_top = y1 <= page_height * 0.08
|
||||
in_bottom = y0 >= page_height * 0.92
|
||||
if PAGE_NUMBER_RE.match(text) and (in_top or in_bottom):
|
||||
return True
|
||||
return len(text) <= 80 and (in_top or in_bottom) and block.meta.get("running_header")
|
||||
|
||||
|
||||
def _running_header_texts(blocks: list[Block]) -> set[str]:
|
||||
page_count = len({_page(b) for b in blocks if _page(b) is not None})
|
||||
if page_count < 3:
|
||||
return set()
|
||||
locations: dict[str, set[int]] = {}
|
||||
for block in blocks:
|
||||
if block.type in {BlockType.IMAGE, BlockType.TABLE, BlockType.HEADING}:
|
||||
continue
|
||||
text = " ".join(_text(block).split())
|
||||
page = _page(block)
|
||||
bbox = _bbox(block)
|
||||
page_height = block.meta.get("page_height") or 0
|
||||
if not text or page is None or not bbox or not page_height or len(text) > 100:
|
||||
continue
|
||||
if bbox[3] <= page_height * 0.10 or bbox[1] >= page_height * 0.90:
|
||||
locations.setdefault(text, set()).add(page)
|
||||
threshold = max(3, int(page_count * 0.5))
|
||||
return {text for text, pages in locations.items() if len(pages) >= threshold}
|
||||
|
||||
|
||||
def _is_noise(block: Block, running_headers: set[str]) -> bool:
|
||||
if _is_empty_text_block(block):
|
||||
return True
|
||||
text = " ".join(_text(block).split())
|
||||
if block.type == BlockType.IMAGE:
|
||||
return _is_decorative_image(block)
|
||||
if PAGE_NUMBER_RE.match(text):
|
||||
return True
|
||||
if _is_toc_text(text):
|
||||
return True
|
||||
if text in running_headers:
|
||||
return True
|
||||
return _is_margin_noise(block)
|
||||
|
||||
|
||||
def _heading_signal(block: Block, current_top_level: bool = False) -> _HeadingSignal | None:
|
||||
text = _text(block)
|
||||
if not text or len(text) > 180 or _is_toc_text(text):
|
||||
return None
|
||||
# Keep procedural steps inside the parent section; do not open a new group.
|
||||
if STEP_INSTRUCTION_RE.match(text):
|
||||
return None
|
||||
|
||||
if block.type == BlockType.HEADING:
|
||||
level = block.level or 1
|
||||
numbered = NUMBERED_HEADING_RE.match(text)
|
||||
if numbered:
|
||||
level = numbered.group("num").count(".") + 1
|
||||
elif LETTER_HEADING_RE.match(text):
|
||||
level = 2 if current_top_level else max(2, level)
|
||||
return _HeadingSignal(text=" ".join(text.split()), level=max(1, min(level, 6)))
|
||||
|
||||
numbered = NUMBERED_HEADING_RE.match(text)
|
||||
if numbered:
|
||||
return _HeadingSignal(text=" ".join(text.split()), level=numbered.group("num").count(".") + 1)
|
||||
if LETTER_HEADING_RE.match(text):
|
||||
return _HeadingSignal(text=" ".join(text.split()), level=2)
|
||||
if CHAPTER_HEADING_RE.match(text):
|
||||
return _HeadingSignal(text=" ".join(text.split()), level=1)
|
||||
if CN_HEADING_RE.match(text):
|
||||
return _HeadingSignal(text=" ".join(text.split()), level=2 if current_top_level else 1)
|
||||
|
||||
font_size = block.meta.get("font_size")
|
||||
body_size = block.meta.get("body_font_size")
|
||||
if font_size and body_size and font_size >= body_size + 1.5 and len(text) <= 100:
|
||||
level = block.level or 2
|
||||
# Short CJK section banners (形態指標 / 策略指標) are chapter peers, not
|
||||
# subsections of the preceding numbered person/indicator entry.
|
||||
if (
|
||||
font_size >= body_size + 3
|
||||
and re.fullmatch(r"[\u4e00-\u9fffA-Za-z0-9//\s]{2,24}", text)
|
||||
and not NUMBERED_HEADING_RE.match(text)
|
||||
):
|
||||
level = 1
|
||||
return _HeadingSignal(text=" ".join(text.split()), level=max(1, min(level, 6)))
|
||||
return None
|
||||
|
||||
|
||||
def _heading_block(block: Block, signal: _HeadingSignal) -> Block:
|
||||
meta = dict(block.meta)
|
||||
meta["section_boundary"] = True
|
||||
meta["heading_level"] = signal.level
|
||||
return Block(type=BlockType.HEADING, text=signal.text, level=signal.level, meta=meta)
|
||||
|
||||
|
||||
def _enrich_block(block: Block, heading_path: list[str], group_blocks: list[Block]) -> Block:
|
||||
meta = dict(block.meta)
|
||||
meta["heading_path"] = list(heading_path)
|
||||
if heading_path:
|
||||
meta["nearest_heading"] = heading_path[-1]
|
||||
meta["parent_heading"] = heading_path[-1]
|
||||
meta["chapter"] = heading_path[0]
|
||||
meta.setdefault("section_boundary", block.type == BlockType.HEADING)
|
||||
if block.type == BlockType.HEADING:
|
||||
meta["heading_level"] = block.level or len(heading_path) or 1
|
||||
if block.type in {BlockType.IMAGE, BlockType.TABLE}:
|
||||
meta.setdefault("bound_heading", heading_path[-1] if heading_path else "")
|
||||
_bind_adjacent_text(meta, block, group_blocks)
|
||||
return block.model_copy(update={"meta": meta})
|
||||
|
||||
|
||||
def _bind_adjacent_text(meta: dict, block: Block, group_blocks: list[Block]) -> None:
|
||||
page = _page(block)
|
||||
for prev in reversed(group_blocks):
|
||||
if prev.type == BlockType.PARAGRAPH and _page(prev) == page and _text(prev):
|
||||
meta.setdefault("preceding_text", _text(prev)[:400])
|
||||
break
|
||||
if prev.type == BlockType.HEADING:
|
||||
break
|
||||
if block.type == BlockType.TABLE and not meta.get("table_title"):
|
||||
for prev in reversed(group_blocks):
|
||||
if prev.type == BlockType.HEADING:
|
||||
meta["table_title"] = _text(prev)
|
||||
break
|
||||
if prev.type == BlockType.PARAGRAPH and _page(prev) == page and 0 < len(_text(prev)) <= 120:
|
||||
meta["table_title"] = _text(prev)
|
||||
break
|
||||
|
||||
|
||||
def _fill_following_text(group: _Group) -> _Group:
|
||||
blocks = list(group.blocks)
|
||||
for i, block in enumerate(blocks):
|
||||
if block.type not in {BlockType.IMAGE, BlockType.TABLE}:
|
||||
continue
|
||||
meta = dict(block.meta)
|
||||
page = _page(block)
|
||||
for nxt in blocks[i + 1 :]:
|
||||
if nxt.type == BlockType.HEADING:
|
||||
break
|
||||
if nxt.type == BlockType.PARAGRAPH and _page(nxt) == page and _text(nxt):
|
||||
meta.setdefault("following_text", _text(nxt)[:400])
|
||||
break
|
||||
blocks[i] = block.model_copy(update={"meta": meta})
|
||||
return _Group(heading_path=group.heading_path, blocks=blocks)
|
||||
|
||||
|
||||
def _group_has_body(group: _Group) -> bool:
|
||||
for block in group.blocks:
|
||||
if block.type in {BlockType.IMAGE, BlockType.TABLE}:
|
||||
return True
|
||||
if block.type != BlockType.HEADING and _text(block):
|
||||
return True
|
||||
# Safety net: long instructional "headings" are themselves searchable content.
|
||||
return any(block.type == BlockType.HEADING and len(_text(block)) >= 48 for block in group.blocks)
|
||||
|
||||
|
||||
def _attach_heading_only_to_previous(groups: list[_Group], orphan: _Group) -> None:
|
||||
"""Keep catalog-style heading-only groups instead of deleting them.
|
||||
|
||||
Example: after \"共包含以下11個形態指標說明:\", lines like \"1.頭肩頂形態\"
|
||||
briefly open a group with no body before the next number arrives. Flush used
|
||||
to drop them; fold those leaf titles into the previous section as paragraphs.
|
||||
"""
|
||||
if not groups or not orphan.blocks:
|
||||
return
|
||||
prev = groups[-1]
|
||||
prev_keys = {(b.type, _text(b), tuple(b.meta.get("bbox") or [])) for b in prev.blocks}
|
||||
path_set = set(prev.heading_path)
|
||||
for block in orphan.blocks:
|
||||
text = _text(block)
|
||||
if not text:
|
||||
continue
|
||||
# Skip copies of ancestor headings already injected into the orphan group.
|
||||
if text in path_set:
|
||||
continue
|
||||
key = (block.type, text, tuple(block.meta.get("bbox") or []))
|
||||
if key in prev_keys:
|
||||
continue
|
||||
if block.type == BlockType.HEADING:
|
||||
meta = dict(block.meta)
|
||||
meta["catalog_item"] = True
|
||||
meta["section_boundary"] = False
|
||||
demoted = Block(type=BlockType.PARAGRAPH, text=text, meta=meta)
|
||||
prev.blocks.append(_enrich_block(demoted, prev.heading_path, prev.blocks))
|
||||
else:
|
||||
prev.blocks.append(_enrich_block(block, prev.heading_path, prev.blocks))
|
||||
prev_keys.add(key)
|
||||
|
||||
|
||||
def _group_is_retrievable(group: _Group) -> bool:
|
||||
"""Return whether a rendered group contains searchable semantic context."""
|
||||
if group.heading_path:
|
||||
return True
|
||||
for block in group.blocks:
|
||||
if block.type == BlockType.TABLE:
|
||||
return True
|
||||
if block.type == BlockType.IMAGE:
|
||||
if block.ocr_text.strip():
|
||||
return True
|
||||
continue
|
||||
if block.type != BlockType.HEADING and _text(block):
|
||||
return True
|
||||
return False
|
||||
|
||||
|
||||
def _render_group(group: _Group, index: int, config: SplitConfig, meta: dict | None = None) -> Chunk:
|
||||
group = _fill_following_text(group)
|
||||
layout_meta = collect_chunk_layout_meta(group.blocks)
|
||||
heading_path = group.heading_path or layout_meta.get("heading_path") or []
|
||||
heading = heading_path[-1] if heading_path else layout_meta.get("heading") or "Untitled section"
|
||||
extra_meta = {
|
||||
**layout_meta,
|
||||
"chunk_strategy": CHUNK_STRATEGY,
|
||||
"heading": heading,
|
||||
"heading_path": heading_path,
|
||||
"retrieval": _group_is_retrievable(group),
|
||||
**(meta or {}),
|
||||
}
|
||||
if "order_range" not in extra_meta:
|
||||
order_indices = [b.meta.get("order_index") for b in group.blocks if b.meta.get("order_index") is not None]
|
||||
if order_indices:
|
||||
extra_meta["order_range"] = [min(order_indices), max(order_indices)]
|
||||
chunk = render_blocks(group.blocks, index=index, meta=extra_meta)
|
||||
chunk_meta = dict(chunk.meta)
|
||||
chunk_meta.update(extra_meta)
|
||||
return chunk.model_copy(update={"meta": chunk_meta})
|
||||
|
||||
|
||||
def _split_oversized_group(group: _Group, start_index: int, config: SplitConfig) -> list[Chunk]:
|
||||
"""Split an oversized section by length only (no parent+child pair)."""
|
||||
rendered_len = sum(len(b.render()) + 2 for b in group.blocks)
|
||||
if rendered_len <= config.max_chunk_size or len(group.blocks) <= 3:
|
||||
return [_render_group(group, start_index, config)]
|
||||
|
||||
heading_blocks = [b for b in group.blocks if b.type == BlockType.HEADING]
|
||||
prefix = heading_blocks[:1]
|
||||
chunks: list[Chunk] = []
|
||||
current: list[Block] = list(prefix)
|
||||
current_len = sum(len(b.render()) + 2 for b in current)
|
||||
part_index = 0
|
||||
|
||||
def flush() -> None:
|
||||
nonlocal current, current_len, part_index
|
||||
body = [b for b in current if b not in prefix]
|
||||
if not body:
|
||||
return
|
||||
part_group = _Group(group.heading_path, list(current))
|
||||
chunks.append(
|
||||
_render_group(
|
||||
part_group,
|
||||
start_index + len(chunks),
|
||||
config,
|
||||
meta={
|
||||
"chunk_strategy": f"{CHUNK_STRATEGY}_part",
|
||||
"part_index": part_index,
|
||||
"retrieval": True,
|
||||
},
|
||||
)
|
||||
)
|
||||
part_index += 1
|
||||
current = list(prefix)
|
||||
current_len = sum(len(b.render()) + 2 for b in current)
|
||||
|
||||
for block in group.blocks[len(prefix) :]:
|
||||
block_len = len(block.render()) + 2
|
||||
if current_len + block_len > config.max_chunk_size and len(current) > len(prefix):
|
||||
flush()
|
||||
current.append(block)
|
||||
current_len += block_len
|
||||
flush()
|
||||
return chunks or [_render_group(group, start_index, config)]
|
||||
|
||||
|
||||
def _build_groups(blocks: list[Block]) -> list[_Group]:
|
||||
running_headers = _running_header_texts(blocks)
|
||||
heading_stack: list[tuple[int, str, Block]] = []
|
||||
groups: list[_Group] = []
|
||||
current = _Group()
|
||||
|
||||
def flush() -> None:
|
||||
nonlocal current
|
||||
if _group_has_body(current):
|
||||
groups.append(current)
|
||||
elif current.blocks:
|
||||
# Explicit parser headings with no body are empty document sections,
|
||||
# not catalog items to fold into the preceding section.
|
||||
if not any(block.meta.get("source_heading") for block in current.blocks):
|
||||
_attach_heading_only_to_previous(groups, current)
|
||||
current = _Group()
|
||||
|
||||
for raw in blocks:
|
||||
if _is_noise(raw, running_headers):
|
||||
continue
|
||||
|
||||
signal = _heading_signal(raw, current_top_level=bool(heading_stack))
|
||||
if signal:
|
||||
flush()
|
||||
while heading_stack and heading_stack[-1][0] >= signal.level:
|
||||
heading_stack.pop()
|
||||
heading = _heading_block(raw, signal)
|
||||
heading_stack.append((signal.level, signal.text, heading))
|
||||
path = [item[1] for item in heading_stack]
|
||||
current = _Group(heading_path=path)
|
||||
for _, _, h_block in heading_stack:
|
||||
current.blocks.append(_enrich_block(h_block, path, current.blocks))
|
||||
continue
|
||||
|
||||
path = [item[1] for item in heading_stack]
|
||||
if not current.blocks and heading_stack:
|
||||
current.heading_path = path
|
||||
for _, _, h_block in heading_stack:
|
||||
current.blocks.append(_enrich_block(h_block, path, current.blocks))
|
||||
elif not current.heading_path:
|
||||
current.heading_path = path
|
||||
|
||||
current.blocks.append(_enrich_block(raw, current.heading_path, current.blocks))
|
||||
|
||||
flush()
|
||||
return groups
|
||||
|
||||
|
||||
def split_pdf_semantic(blocks: list[Block], config: SplitConfig) -> list[Chunk]:
|
||||
"""Split PDF/Word-derived blocks into heading/layout-preserving multimodal chunks."""
|
||||
groups = _build_groups(blocks)
|
||||
chunks: list[Chunk] = []
|
||||
for group in groups:
|
||||
for chunk in _split_oversized_group(group, len(chunks), config):
|
||||
chunks.append(chunk.model_copy(update={"index": len(chunks)}))
|
||||
return chunks
|
||||
@@ -0,0 +1,82 @@
|
||||
"""Choose a PDF chunking strategy from parsed document signals."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import re
|
||||
from pathlib import Path
|
||||
|
||||
from rag_cut.models import Block, BlockType
|
||||
|
||||
FEATURE_TITLE_RE = re.compile(r"^\s*\d{1,2}[..、]\s*[A-Za-z0-9\u4e00-\u9fff&/ -]{2,24}")
|
||||
OPERATION_TERMS = (
|
||||
"点击",
|
||||
"點擊",
|
||||
"选择",
|
||||
"選擇",
|
||||
"输入",
|
||||
"輸入",
|
||||
"打开",
|
||||
"打開",
|
||||
"登入",
|
||||
"用戶可",
|
||||
"用户可",
|
||||
"按<",
|
||||
"點撃",
|
||||
)
|
||||
REPORT_TERMS = (
|
||||
"年度报告",
|
||||
"年报",
|
||||
"財務報表",
|
||||
"财务报表",
|
||||
"公司治理",
|
||||
"董事会",
|
||||
"董事會",
|
||||
"审计报告",
|
||||
"審計報告",
|
||||
"合并资产负债表",
|
||||
"合併資產負債表",
|
||||
"经营情况",
|
||||
"經營情況",
|
||||
"营业收入",
|
||||
"營業收入",
|
||||
"现金流量",
|
||||
"現金流量",
|
||||
"股东",
|
||||
"股東",
|
||||
)
|
||||
REPORT_NAME_TERMS = ("annual", "report", "年度", "年报", "年報", "研报", "研報")
|
||||
|
||||
PDF_STRATEGY_FEATURE_STEPS = "pdf_feature_step_screenshot"
|
||||
PDF_STRATEGY_OUTLINE_REPORT = "pdf_outline_report"
|
||||
|
||||
|
||||
def _text(block: Block) -> str:
|
||||
return (block.text or block.markdown or "").strip()
|
||||
|
||||
|
||||
def _term_count(text: str, terms: tuple[str, ...]) -> int:
|
||||
return sum(text.count(term) for term in terms)
|
||||
|
||||
|
||||
def choose_pdf_chunk_strategy(path: Path, blocks: list[Block]) -> str:
|
||||
"""Classify PDFs as operation manuals or report-like documents."""
|
||||
text_blocks = [block for block in blocks if block.type != BlockType.IMAGE and _text(block)]
|
||||
image_count = sum(1 for block in blocks if block.type == BlockType.IMAGE)
|
||||
sample = "\n".join(_text(block) for block in text_blocks[:240])
|
||||
filename = path.name.lower()
|
||||
|
||||
report_score = _term_count(sample, REPORT_TERMS)
|
||||
if any(term in filename for term in REPORT_NAME_TERMS):
|
||||
report_score += 3
|
||||
|
||||
feature_title_count = sum(1 for block in text_blocks if FEATURE_TITLE_RE.match(_text(block)))
|
||||
operation_score = _term_count(sample, OPERATION_TERMS)
|
||||
screenshot_density = image_count / max(len(text_blocks), 1)
|
||||
|
||||
if report_score >= 3 and operation_score < 18:
|
||||
return PDF_STRATEGY_OUTLINE_REPORT
|
||||
|
||||
if feature_title_count >= 3 and operation_score >= 6 and image_count >= 3 and screenshot_density >= 0.12:
|
||||
return PDF_STRATEGY_FEATURE_STEPS
|
||||
|
||||
return PDF_STRATEGY_OUTLINE_REPORT
|
||||
@@ -0,0 +1,53 @@
|
||||
"""Table-aware chunk grouping helpers."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
from rag_cut.models import Block, BlockType
|
||||
|
||||
|
||||
def group_tables_with_context(blocks: list[Block]) -> list[list[Block]]:
|
||||
"""
|
||||
Group each table with its contextual title paragraph and footnote.
|
||||
Keeps: heading/intro → table → footnote as one atomic group when adjacent.
|
||||
"""
|
||||
if not blocks:
|
||||
return []
|
||||
|
||||
groups: list[list[Block]] = []
|
||||
current: list[Block] = []
|
||||
i = 0
|
||||
|
||||
while i < len(blocks):
|
||||
block = blocks[i]
|
||||
if block.type != BlockType.TABLE:
|
||||
current.append(block)
|
||||
i += 1
|
||||
continue
|
||||
|
||||
group: list[Block] = []
|
||||
if current:
|
||||
tail = current[-1]
|
||||
if tail.type in {BlockType.HEADING, BlockType.PARAGRAPH}:
|
||||
group.append(tail)
|
||||
current = current[:-1]
|
||||
if current:
|
||||
groups.append(current)
|
||||
current = []
|
||||
|
||||
group.append(block)
|
||||
j = i + 1
|
||||
while j < len(blocks):
|
||||
nxt = blocks[j]
|
||||
if nxt.type == BlockType.PARAGRAPH and len((nxt.text or "")) <= 320:
|
||||
if any(k in (nxt.text or "") for k in ("注", "备注", "说明", "Note", "※")):
|
||||
group.append(nxt)
|
||||
j += 1
|
||||
break
|
||||
break
|
||||
|
||||
groups.append(group)
|
||||
i = j
|
||||
|
||||
if current:
|
||||
groups.append(current)
|
||||
return groups
|
||||
@@ -0,0 +1,40 @@
|
||||
"""Start the RAG-cut backend API server."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import argparse
|
||||
import sys
|
||||
from pathlib import Path
|
||||
|
||||
BACKEND_DIR = Path(__file__).resolve().parent
|
||||
|
||||
|
||||
def main() -> None:
|
||||
parser = argparse.ArgumentParser(description="Start RAG-cut backend API")
|
||||
parser.add_argument("--host", default="127.0.0.1", help="Bind host (default: 127.0.0.1)")
|
||||
parser.add_argument("--port", type=int, default=8000, help="Bind port (default: 8000)")
|
||||
parser.add_argument(
|
||||
"--reload",
|
||||
action=argparse.BooleanOptionalAction,
|
||||
default=True,
|
||||
help="Auto-reload on code changes (default: on)",
|
||||
)
|
||||
args = parser.parse_args()
|
||||
|
||||
backend = str(BACKEND_DIR)
|
||||
if backend not in sys.path:
|
||||
sys.path.insert(0, backend)
|
||||
|
||||
import uvicorn
|
||||
|
||||
uvicorn.run(
|
||||
"api.main:app",
|
||||
host=args.host,
|
||||
port=args.port,
|
||||
reload=args.reload,
|
||||
reload_dirs=[backend] if args.reload else None,
|
||||
)
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
main()
|
||||
@@ -0,0 +1,244 @@
|
||||
"""API integration tests for chunk persistence and recall."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import tempfile
|
||||
import unittest
|
||||
from pathlib import Path
|
||||
from unittest.mock import patch
|
||||
|
||||
from fastapi.testclient import TestClient
|
||||
|
||||
from api.main import app
|
||||
from rag_cut.models import Chunk, ChunkResult, SplitMode
|
||||
|
||||
|
||||
def result(filename: str = "manual.txt") -> ChunkResult:
|
||||
content = "交易密码可在账户安全页面修改"
|
||||
return ChunkResult(
|
||||
filename=filename,
|
||||
doc_id="abcdef123456",
|
||||
split_mode=SplitMode.DEFAULT,
|
||||
block_count=2,
|
||||
chunk_count=2,
|
||||
chunks=[
|
||||
Chunk(index=0, content="", char_count=18, block_types=["image"], meta={"retrieval": False}),
|
||||
Chunk(index=1, content=content, char_count=len(content), block_types=["paragraph"], meta={"retrieval": True}),
|
||||
],
|
||||
)
|
||||
|
||||
|
||||
class ApiTest(unittest.TestCase):
|
||||
def setUp(self) -> None:
|
||||
self.client = TestClient(app)
|
||||
|
||||
def test_chunk_preserves_upload_filename_and_persists_result(self) -> None:
|
||||
with tempfile.TemporaryDirectory() as tmp, patch("api.main.RESULTS_DIR", Path(tmp)):
|
||||
with patch("api.main.chunk_document", side_effect=lambda path, config=None: result(path.name)):
|
||||
response = self.client.post("/api/chunk", files={"file": ("用户手册.txt", b"body", "text/plain")})
|
||||
|
||||
self.assertEqual(response.status_code, 200)
|
||||
self.assertEqual(response.json()["filename"], "用户手册.txt")
|
||||
self.assertTrue((Path(tmp) / "abcdef123456.json").exists())
|
||||
|
||||
def test_recall_endpoint_excludes_preview_only_chunk(self) -> None:
|
||||
with tempfile.TemporaryDirectory() as tmp, patch("api.main.RESULTS_DIR", Path(tmp)):
|
||||
(Path(tmp) / "abcdef123456.json").write_text(result().model_dump_json(), encoding="utf-8")
|
||||
response = self.client.post(
|
||||
"/api/recall",
|
||||
json={"doc_id": "abcdef123456", "query": "交易密码", "top_k": 5},
|
||||
)
|
||||
|
||||
self.assertEqual(response.status_code, 200)
|
||||
payload = response.json()
|
||||
self.assertEqual(payload["candidate_count"], 1)
|
||||
self.assertEqual(payload["results"][0]["chunk_index"], 1)
|
||||
|
||||
def test_recall_rejects_invalid_doc_id(self) -> None:
|
||||
response = self.client.post("/api/recall", json={"doc_id": "../secret", "query": "test"})
|
||||
self.assertEqual(response.status_code, 400)
|
||||
|
||||
def test_list_and_get_historical_results(self) -> None:
|
||||
with tempfile.TemporaryDirectory() as tmp:
|
||||
results_dir = Path(tmp) / "results"
|
||||
uploads_dir = Path(tmp) / "uploads"
|
||||
results_dir.mkdir()
|
||||
uploads_dir.mkdir()
|
||||
(results_dir / "abcdef123456.json").write_text(result().model_dump_json(), encoding="utf-8")
|
||||
upload_doc = uploads_dir / "abcdef123456"
|
||||
upload_doc.mkdir()
|
||||
(upload_doc / "manual.txt").write_text("hello original", encoding="utf-8")
|
||||
|
||||
with (
|
||||
patch("api.main.RESULTS_DIR", results_dir),
|
||||
patch("api.main.UPLOADS_DIR", uploads_dir),
|
||||
):
|
||||
listed = self.client.get("/api/results")
|
||||
self.assertEqual(listed.status_code, 200)
|
||||
body = listed.json()
|
||||
self.assertEqual(body["count"], 1)
|
||||
self.assertEqual(body["results"][0]["doc_id"], "abcdef123456")
|
||||
self.assertEqual(body["results"][0]["filename"], "manual.txt")
|
||||
self.assertTrue(body["results"][0]["has_original"])
|
||||
|
||||
detail = self.client.get("/api/results/abcdef123456")
|
||||
self.assertEqual(detail.status_code, 200)
|
||||
self.assertEqual(detail.json()["chunk_count"], 2)
|
||||
self.assertTrue(detail.json()["has_original"])
|
||||
|
||||
original = self.client.get("/api/results/abcdef123456/original")
|
||||
self.assertEqual(original.status_code, 200)
|
||||
self.assertEqual(original.content, b"hello original")
|
||||
|
||||
def test_get_result_not_found(self) -> None:
|
||||
with tempfile.TemporaryDirectory() as tmp, patch("api.main.RESULTS_DIR", Path(tmp)):
|
||||
response = self.client.get("/api/results/abcdef123456")
|
||||
self.assertEqual(response.status_code, 404)
|
||||
|
||||
def test_word_preview_serves_converted_pdf(self) -> None:
|
||||
with tempfile.TemporaryDirectory() as tmp:
|
||||
root = Path(tmp)
|
||||
uploads_dir = root / "uploads"
|
||||
doc_dir = uploads_dir / "abcdef123456"
|
||||
conversion_dir = root / "assets" / "abcdef123456" / "_conversion"
|
||||
doc_dir.mkdir(parents=True)
|
||||
conversion_dir.mkdir(parents=True)
|
||||
(doc_dir / "manual.docx").write_bytes(b"word")
|
||||
preview = conversion_dir / "manual.pdf"
|
||||
preview.write_bytes(b"%PDF-1.7 preview")
|
||||
|
||||
with (
|
||||
patch("api.main.UPLOADS_DIR", uploads_dir),
|
||||
patch("api.main.STORAGE_DIR", root),
|
||||
):
|
||||
response = self.client.get("/api/results/abcdef123456/preview")
|
||||
|
||||
self.assertEqual(response.status_code, 200)
|
||||
self.assertEqual(response.headers["content-type"], "application/pdf")
|
||||
self.assertEqual(response.content, b"%PDF-1.7 preview")
|
||||
|
||||
def test_word_preview_returns_not_found_without_conversion(self) -> None:
|
||||
with tempfile.TemporaryDirectory() as tmp:
|
||||
root = Path(tmp)
|
||||
uploads_dir = root / "uploads"
|
||||
doc_dir = uploads_dir / "abcdef123456"
|
||||
doc_dir.mkdir(parents=True)
|
||||
(doc_dir / "manual.doc").write_bytes(b"word")
|
||||
|
||||
with (
|
||||
patch("api.main.UPLOADS_DIR", uploads_dir),
|
||||
patch("api.main.STORAGE_DIR", root),
|
||||
):
|
||||
response = self.client.get("/api/results/abcdef123456/preview")
|
||||
|
||||
self.assertEqual(response.status_code, 404)
|
||||
|
||||
def test_delete_historical_result_removes_files(self) -> None:
|
||||
with tempfile.TemporaryDirectory() as tmp:
|
||||
root = Path(tmp)
|
||||
results_dir = root / "results"
|
||||
uploads_dir = root / "uploads"
|
||||
assets_dir = root / "assets" / "abcdef123456"
|
||||
results_dir.mkdir()
|
||||
uploads_dir.mkdir()
|
||||
assets_dir.mkdir(parents=True)
|
||||
(results_dir / "abcdef123456.json").write_text(result().model_dump_json(), encoding="utf-8")
|
||||
upload_doc = uploads_dir / "abcdef123456"
|
||||
upload_doc.mkdir()
|
||||
(upload_doc / "manual.txt").write_text("hello", encoding="utf-8")
|
||||
(assets_dir / "img.png").write_bytes(b"png")
|
||||
|
||||
with (
|
||||
patch("api.main.RESULTS_DIR", results_dir),
|
||||
patch("api.main.UPLOADS_DIR", uploads_dir),
|
||||
patch("api.main.STORAGE_DIR", root),
|
||||
):
|
||||
deleted = self.client.delete("/api/results/abcdef123456")
|
||||
self.assertEqual(deleted.status_code, 200)
|
||||
body = deleted.json()
|
||||
self.assertTrue(body["deleted"])
|
||||
self.assertTrue(body["removed"]["result"])
|
||||
self.assertTrue(body["removed"]["uploads"])
|
||||
self.assertTrue(body["removed"]["assets"])
|
||||
|
||||
self.assertFalse((results_dir / "abcdef123456.json").exists())
|
||||
self.assertFalse(upload_doc.exists())
|
||||
self.assertFalse(assets_dir.exists())
|
||||
|
||||
listed = self.client.get("/api/results")
|
||||
self.assertEqual(listed.json()["count"], 0)
|
||||
|
||||
missing = self.client.delete("/api/results/abcdef123456")
|
||||
self.assertEqual(missing.status_code, 404)
|
||||
|
||||
def test_delete_rejects_invalid_doc_id(self) -> None:
|
||||
response = self.client.delete("/api/results/not-a-valid")
|
||||
self.assertEqual(response.status_code, 400)
|
||||
|
||||
def test_get_original_rejects_invalid_doc_id(self) -> None:
|
||||
response = self.client.get("/api/results/../secret/original")
|
||||
self.assertIn(response.status_code, (400, 404))
|
||||
|
||||
def test_chunk_accepts_manual_mode_and_preserves_zero_overlap(self) -> None:
|
||||
captured: dict = {}
|
||||
|
||||
def fake_chunk(path, config=None):
|
||||
captured["config"] = config
|
||||
return result(path.name)
|
||||
|
||||
with tempfile.TemporaryDirectory() as tmp, patch("api.main.RESULTS_DIR", Path(tmp)):
|
||||
with patch("api.main.chunk_document", side_effect=fake_chunk):
|
||||
response = self.client.post(
|
||||
"/api/chunk",
|
||||
files={"file": ("sheet.csv", b"a,b\n1,2\n", "text/csv")},
|
||||
data={
|
||||
"mode": "by_row",
|
||||
"overlap": "0",
|
||||
"max_chunk_size": "2400",
|
||||
"header_row_start": "1",
|
||||
"header_row_end": "1",
|
||||
"start_row": "2",
|
||||
"rows_per_chunk": "5",
|
||||
},
|
||||
)
|
||||
|
||||
self.assertEqual(response.status_code, 200)
|
||||
config = captured["config"]
|
||||
self.assertIsNotNone(config)
|
||||
self.assertEqual(config.mode, SplitMode.BY_ROW)
|
||||
self.assertEqual(config.overlap, 0)
|
||||
self.assertEqual(config.rows_per_chunk, 5)
|
||||
|
||||
def test_chunk_accepts_parent_child_mode_fields(self) -> None:
|
||||
captured: dict = {}
|
||||
|
||||
def fake_chunk(path, config=None):
|
||||
captured["config"] = config
|
||||
return result(path.name)
|
||||
|
||||
with tempfile.TemporaryDirectory() as tmp, patch("api.main.RESULTS_DIR", Path(tmp)):
|
||||
with patch("api.main.chunk_document", side_effect=fake_chunk):
|
||||
response = self.client.post(
|
||||
"/api/chunk",
|
||||
files={"file": ("guide.md", b"a##b###c", "text/markdown")},
|
||||
data={
|
||||
"mode": "parent_child",
|
||||
"parent_delimiter": "##",
|
||||
"child_delimiter": "###",
|
||||
"max_chunk_size": "2000",
|
||||
"child_max_size": "512",
|
||||
"overlap": "0",
|
||||
},
|
||||
)
|
||||
|
||||
self.assertEqual(response.status_code, 200)
|
||||
config = captured["config"]
|
||||
self.assertEqual(config.mode, SplitMode.PARENT_CHILD)
|
||||
self.assertEqual(config.parent_delimiter, "##")
|
||||
self.assertEqual(config.child_delimiter, "###")
|
||||
self.assertEqual(config.child_max_size, 512)
|
||||
self.assertEqual(config.overlap, 0)
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
unittest.main()
|
||||
@@ -0,0 +1,290 @@
|
||||
"""Tests for generic heading/layout multimodal splitting."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import tempfile
|
||||
import unittest
|
||||
from pathlib import Path
|
||||
from unittest.mock import patch
|
||||
|
||||
from rag_cut.models import Block, BlockType, SplitConfig, SplitMode
|
||||
from rag_cut.pipeline import chunk_document
|
||||
from rag_cut.splitters.pdf_semantic import CHUNK_STRATEGY, split_pdf_semantic
|
||||
|
||||
|
||||
def h(text: str, page: int = 1, level: int = 0, y: int = 100) -> Block:
|
||||
return Block(
|
||||
type=BlockType.HEADING if level else BlockType.PARAGRAPH,
|
||||
text=text,
|
||||
level=level,
|
||||
meta={"page": page, "bbox": [72, y, 520, y + 20], "page_height": 800},
|
||||
)
|
||||
|
||||
|
||||
def p(text: str, page: int = 1, y: int = 130) -> Block:
|
||||
return Block(
|
||||
type=BlockType.PARAGRAPH,
|
||||
text=text,
|
||||
meta={"page": page, "bbox": [72, y, 520, y + 20], "page_height": 800},
|
||||
)
|
||||
|
||||
|
||||
def img(name: str, page: int = 1, y: int = 180) -> Block:
|
||||
return Block(
|
||||
type=BlockType.IMAGE,
|
||||
image_id=name,
|
||||
image_path=f"assets/test/{name}.png",
|
||||
ocr_text="Login Submit",
|
||||
meta={"page": page, "bbox": [100, y, 500, y + 180], "page_height": 800},
|
||||
)
|
||||
|
||||
|
||||
def table(page: int = 1, y: int = 220) -> Block:
|
||||
return Block(
|
||||
type=BlockType.TABLE,
|
||||
markdown="| Field | Description |\n| --- | --- |\n| status | Account status |",
|
||||
image_id="table1",
|
||||
image_path="assets/test/table1.png",
|
||||
meta={
|
||||
"page": page,
|
||||
"pages": [page],
|
||||
"bbox": [72, y, 520, y + 120],
|
||||
"bboxes": [{"page": page, "bbox": [72, y, 520, y + 120]}],
|
||||
"row_count": 2,
|
||||
"col_count": 2,
|
||||
"cross_page": False,
|
||||
"crop_path": "assets/test/table1.png",
|
||||
},
|
||||
)
|
||||
|
||||
|
||||
class HeadingLayoutMultimodalTest(unittest.TestCase):
|
||||
def test_numbered_headings_create_same_level_boundaries(self) -> None:
|
||||
chunks = split_pdf_semantic(
|
||||
[
|
||||
h("1 Overview"),
|
||||
p("Intro text."),
|
||||
h("1.1 Account Status", y=180),
|
||||
p("Account status details.", y=210),
|
||||
h("1.2 Trade Detail", y=260),
|
||||
p("Trade detail body.", y=290),
|
||||
],
|
||||
SplitConfig(mode=SplitMode.DEFAULT, max_chunk_size=2000),
|
||||
)
|
||||
|
||||
headings = [c.meta["heading"] for c in chunks]
|
||||
self.assertEqual(headings, ["1 Overview", "1.1 Account Status", "1.2 Trade Detail"])
|
||||
self.assertTrue(all(c.meta["chunk_strategy"] == CHUNK_STRATEGY for c in chunks))
|
||||
|
||||
def test_letter_subheadings_bind_nearest_images(self) -> None:
|
||||
chunks = split_pdf_semantic(
|
||||
[
|
||||
h("1 Getting Started"),
|
||||
h("A. Log in", y=140),
|
||||
p("Open the login page.", y=170),
|
||||
img("login", y=210),
|
||||
h("B) Authentication", y=430),
|
||||
p("Approve the authentication request.", y=460),
|
||||
img("auth", y=500),
|
||||
],
|
||||
SplitConfig(mode=SplitMode.DEFAULT, max_chunk_size=2000),
|
||||
)
|
||||
|
||||
self.assertEqual([c.meta["heading"] for c in chunks], ["A. Log in", "B) Authentication"])
|
||||
self.assertEqual(chunks[0].meta["heading_path"], ["1 Getting Started", "A. Log in"])
|
||||
self.assertEqual(chunks[0].meta["images"][0]["image_id"], "login")
|
||||
self.assertEqual(chunks[1].meta["images"][0]["image_id"], "auth")
|
||||
|
||||
def test_table_stays_atomic_with_markdown_and_position(self) -> None:
|
||||
chunks = split_pdf_semantic(
|
||||
[h("2 Settings"), p("The fields are listed below."), table(y=180)],
|
||||
SplitConfig(mode=SplitMode.DEFAULT, max_chunk_size=2000),
|
||||
)
|
||||
|
||||
self.assertEqual(len(chunks), 1)
|
||||
self.assertIn("| Field | Description |", chunks[0].content)
|
||||
self.assertEqual(chunks[0].meta["tables"][0]["row_count"], 2)
|
||||
self.assertEqual(chunks[0].meta["tables"][0]["bbox"], [72, 180, 520, 300])
|
||||
|
||||
def test_unlabelled_image_only_chunk_is_preview_only(self) -> None:
|
||||
cover_logo = img("cover-logo")
|
||||
cover_logo.ocr_text = ""
|
||||
|
||||
chunks = split_pdf_semantic(
|
||||
[cover_logo, h("1 Overview", page=2), p("Useful body.", page=2)],
|
||||
SplitConfig(mode=SplitMode.DEFAULT, max_chunk_size=2000),
|
||||
)
|
||||
|
||||
self.assertEqual(len(chunks), 2)
|
||||
self.assertFalse(chunks[0].meta["retrieval"])
|
||||
self.assertTrue(chunks[1].meta["retrieval"])
|
||||
self.assertIn("cover-logo", chunks[0].content)
|
||||
|
||||
def test_image_only_chunk_with_ocr_remains_retrievable(self) -> None:
|
||||
chunks = split_pdf_semantic(
|
||||
[img("workflow-screenshot")],
|
||||
SplitConfig(mode=SplitMode.DEFAULT, max_chunk_size=2000),
|
||||
)
|
||||
|
||||
self.assertEqual(len(chunks), 1)
|
||||
self.assertTrue(chunks[0].meta["retrieval"])
|
||||
|
||||
def test_noise_blocks_are_skipped(self) -> None:
|
||||
blocks = []
|
||||
for page in range(1, 5):
|
||||
blocks.append(p("Product Manual", page=page, y=20))
|
||||
blocks.append(p(str(page), page=page, y=760))
|
||||
blocks.extend(
|
||||
[
|
||||
p("Contents"),
|
||||
p("1 Intro ........ 3"),
|
||||
p("2 Setup ........ 8"),
|
||||
h("1 Intro", page=2),
|
||||
p("Useful body.", page=2),
|
||||
]
|
||||
)
|
||||
|
||||
chunks = split_pdf_semantic(blocks, SplitConfig(mode=SplitMode.DEFAULT, max_chunk_size=2000))
|
||||
|
||||
content = "\n".join(c.content for c in chunks)
|
||||
self.assertIn("Useful body.", content)
|
||||
self.assertNotIn("Product Manual", content)
|
||||
self.assertNotIn("Contents", content)
|
||||
self.assertNotIn("........", content)
|
||||
self.assertNotIn("2 Setup", content)
|
||||
|
||||
def test_cross_page_same_heading_is_one_chunk(self) -> None:
|
||||
chunks = split_pdf_semantic(
|
||||
[h("3 Client"), p("Page one text.", page=1), p("Page two continuation.", page=2)],
|
||||
SplitConfig(mode=SplitMode.DEFAULT, max_chunk_size=2000),
|
||||
)
|
||||
|
||||
self.assertEqual(len(chunks), 1)
|
||||
self.assertEqual(chunks[0].meta["pages"], [1, 2])
|
||||
self.assertIn("Page two continuation.", chunks[0].content)
|
||||
|
||||
def test_instructional_steps_stay_in_parent_section(self) -> None:
|
||||
"""Step 1/2/3 lines must not become headings that get flushed away."""
|
||||
chunks = split_pdf_semantic(
|
||||
[
|
||||
h("5.7 CRS SUBMISSION TO IRD", level=2),
|
||||
h("5.7.1 Submission at 1st time", level=3, y=140),
|
||||
p(
|
||||
"For CRS submission at first time by G3SB, prior consent has to be obtained "
|
||||
"from IRD by submitting test data file to the AEOI Portal for validation.",
|
||||
y=170,
|
||||
),
|
||||
img("workflow", y=210),
|
||||
p("Step 1 Users prepare the XML as per sections 5.1– 5.5.", y=420),
|
||||
p('Step 2 Set parameter "Export in test data format?" value to "Y".', y=450),
|
||||
p("Step 3 Check XML file tag DocTypeIndic was using OECD11.", y=480),
|
||||
p(
|
||||
"Step 4 Go to Registration and login page of AEOI Portal: "
|
||||
"https://aeoi1.ird.gov.hk/portal/landing/",
|
||||
y=510,
|
||||
),
|
||||
p("Download the encryption tools to encrypt the XML file.", y=540),
|
||||
],
|
||||
SplitConfig(mode=SplitMode.DEFAULT, max_chunk_size=4000),
|
||||
)
|
||||
|
||||
content = "\n".join(c.content for c in chunks)
|
||||
self.assertIn("Step 1 Users prepare the XML", content)
|
||||
self.assertIn("Export in test data format", content)
|
||||
self.assertIn("OECD11", content)
|
||||
self.assertIn("Step 4 Go to Registration", content)
|
||||
self.assertTrue(any(c.meta["heading"] == "5.7.1 Submission at 1st time" for c in chunks))
|
||||
|
||||
def test_oversized_section_splits_by_length_without_parent(self) -> None:
|
||||
blocks = [h("4 Reports")] + [p(f"Long paragraph {i} " + "x" * 80, y=130 + i) for i in range(8)]
|
||||
chunks = split_pdf_semantic(blocks, SplitConfig(mode=SplitMode.DEFAULT, max_chunk_size=260))
|
||||
|
||||
self.assertGreater(len(chunks), 1)
|
||||
self.assertTrue(all(c.meta.get("retrieval", True) for c in chunks))
|
||||
self.assertFalse(any(c.meta.get("is_section_parent") for c in chunks))
|
||||
self.assertFalse(any(c.meta.get("is_sub_chunk") for c in chunks))
|
||||
self.assertFalse(any(c.meta.get("parent_chunk_id") is not None for c in chunks))
|
||||
|
||||
def test_catalog_titles_fold_into_section_not_dropped(self) -> None:
|
||||
"""TOC-style '1.xxx' lines between catalog headings must not vanish on flush."""
|
||||
chunks = split_pdf_semantic(
|
||||
[
|
||||
h("14.W. Whitney George", level=1, y=100),
|
||||
p("Famous fund manager bio.", y=130),
|
||||
Block(
|
||||
type=BlockType.HEADING,
|
||||
text="形態指標",
|
||||
level=1,
|
||||
meta={
|
||||
"page": 1,
|
||||
"bbox": [72, 200, 200, 220],
|
||||
"page_height": 800,
|
||||
"font_size": 16,
|
||||
"body_font_size": 12,
|
||||
},
|
||||
),
|
||||
p("共包含以下11個形態指標說明:", y=240),
|
||||
h("1.頭肩頂形態", level=1, y=260),
|
||||
h("2.頭肩底形態", level=1, y=280),
|
||||
h("1.頭肩頂形態", level=1, page=2, y=120),
|
||||
p("整體介紹:頂部反轉形態說明。", page=2, y=150),
|
||||
],
|
||||
SplitConfig(mode=SplitMode.DEFAULT, max_chunk_size=4000),
|
||||
)
|
||||
|
||||
morph = next(c for c in chunks if c.meta.get("heading") == "形態指標")
|
||||
self.assertEqual(morph.meta.get("heading_path"), ["形態指標"])
|
||||
self.assertIn("共包含以下11個形態指標說明:", morph.content)
|
||||
self.assertIn("1.頭肩頂形態", morph.content)
|
||||
self.assertIn("2.頭肩底形態", morph.content)
|
||||
|
||||
detail = next(
|
||||
c for c in chunks if c.meta.get("heading") == "1.頭肩頂形態" and "整體介紹" in c.content
|
||||
)
|
||||
self.assertIn("整體介紹", detail.content)
|
||||
|
||||
def test_empty_explicit_section_does_not_pollute_previous_chunk(self) -> None:
|
||||
empty_heading = h("2 REFERENCES", level=1, page=3, y=100)
|
||||
empty_heading.meta["source_heading"] = True
|
||||
chunks = split_pdf_semantic(
|
||||
[
|
||||
h("1 GLOSSARY", level=1, page=2, y=100),
|
||||
table(page=2, y=140),
|
||||
empty_heading,
|
||||
h("3 DOCUMENT HISTORY", level=1, page=3, y=180),
|
||||
p("History body.", page=3, y=220),
|
||||
],
|
||||
SplitConfig(mode=SplitMode.DEFAULT, max_chunk_size=4000),
|
||||
)
|
||||
|
||||
glossary = next(c for c in chunks if c.meta.get("heading") == "1 GLOSSARY")
|
||||
self.assertNotIn("2 REFERENCES", glossary.content)
|
||||
self.assertFalse(any("2 REFERENCES" in c.content for c in chunks))
|
||||
|
||||
|
||||
class DummyParser:
|
||||
def parse(self, path: Path, assets_dir: Path) -> list[Block]:
|
||||
return [h("1 Overview"), p("Pipeline body.")]
|
||||
|
||||
|
||||
class PipelineSemanticIntegrationTest(unittest.TestCase):
|
||||
def test_pdf_default_mode_uses_heading_layout_multimodal(self) -> None:
|
||||
with tempfile.TemporaryDirectory() as tmp:
|
||||
tmp_root = Path(tmp)
|
||||
source = tmp_root / "sample.pdf"
|
||||
source.write_bytes(b"%PDF-1.4\n")
|
||||
|
||||
with patch("rag_cut.pipeline.get_parser", return_value=DummyParser()):
|
||||
result = chunk_document(
|
||||
source,
|
||||
config=SplitConfig(mode=SplitMode.DEFAULT, max_chunk_size=2000),
|
||||
storage_root=tmp_root / "storage",
|
||||
)
|
||||
|
||||
self.assertEqual(result.chunk_count, 1)
|
||||
self.assertEqual(result.split_config["chunk_strategy"], CHUNK_STRATEGY)
|
||||
self.assertEqual(result.chunks[0].meta["chunk_strategy"], CHUNK_STRATEGY)
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
unittest.main()
|
||||
@@ -0,0 +1,98 @@
|
||||
"""Tests for PDF text merge and heading classification."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import unittest
|
||||
|
||||
from rag_cut.layout_meta import enrich_layout_metadata
|
||||
from rag_cut.models import Block, BlockType
|
||||
from rag_cut.parsers.pdf.layout import TextLine, _merge_lines_to_paragraphs
|
||||
from rag_cut.parsers.pdf.text_extract import MAX_HEADING_CHARS, _font_heading_level, _looks_like_ui_label
|
||||
from rag_cut.parsers.pdf.noise_filter import is_margin_noise_block
|
||||
from rag_cut.splitters.heading_splitter import is_heading_block, normalize_heading_block, numbered_heading_level
|
||||
|
||||
|
||||
class ParagraphMergeTest(unittest.TestCase):
|
||||
def test_does_not_merge_title_and_body_with_different_font_sizes(self) -> None:
|
||||
lines = [
|
||||
TextLine(x0=90, y0=90, x1=400, y1=110, text="Master Collection/Pattern Scanning", font_size=18),
|
||||
TextLine(x0=90, y0=115, x1=480, y1=132, text="及所有大師/形態/策略指標的位置", font_size=17.5),
|
||||
TextLine(
|
||||
x0=90,
|
||||
y0=145,
|
||||
x1=500,
|
||||
y1=200,
|
||||
text="頁面左側【篩選】欄下方即是【Master Collection】文件夾。點擊此檔夾即可出現下拉頁面。",
|
||||
font_size=11,
|
||||
),
|
||||
]
|
||||
merged = _merge_lines_to_paragraphs(lines, page_width=600)
|
||||
texts = [ln.text for ln in merged]
|
||||
self.assertEqual(len(merged), 2)
|
||||
self.assertIn("Master Collection", texts[0])
|
||||
self.assertTrue(texts[1].startswith("頁面左側"))
|
||||
self.assertNotIn("頁面左側", texts[0])
|
||||
|
||||
|
||||
class FontHeadingTest(unittest.TestCase):
|
||||
def test_short_large_text_is_heading(self) -> None:
|
||||
level = _font_heading_level(18, 11, "Master Collection 位置說明")
|
||||
self.assertIsNotNone(level)
|
||||
|
||||
def test_title_plus_body_blob_is_not_heading(self) -> None:
|
||||
blob = (
|
||||
"Master Collection/Pattern Scanning/Strategy Scanning 及所有大師/形態/策略指標的位置 "
|
||||
"頁面左側【篩選】欄下方即是【Master Collection】文件夾。點擊此檔夾即可出現下拉頁面,"
|
||||
"其中包含了十五個大師的選股策略。如圖所示:"
|
||||
)
|
||||
self.assertGreater(len(blob), MAX_HEADING_CHARS)
|
||||
self.assertIsNone(_font_heading_level(18, 11, blob))
|
||||
|
||||
def test_compact_numbered_chinese_title_is_heading(self) -> None:
|
||||
# FAQ style: "10.上升三角形態" with no space after the dot.
|
||||
level = _font_heading_level(16, 12, "10.上升三角形態")
|
||||
self.assertEqual(level, 1)
|
||||
self.assertFalse(_looks_like_ui_label("10.上升三角形態"))
|
||||
|
||||
def test_cjk_section_banner_is_level1_not_ui_label(self) -> None:
|
||||
self.assertFalse(_looks_like_ui_label("形態指標"))
|
||||
self.assertEqual(_font_heading_level(16, 12, "形態指標"), 1)
|
||||
|
||||
|
||||
|
||||
class HeadingDemoteTest(unittest.TestCase):
|
||||
def test_normalize_demotes_overlong_heading(self) -> None:
|
||||
blob = "T" * (MAX_HEADING_CHARS + 20)
|
||||
block = Block(type=BlockType.HEADING, text=blob, level=1, meta={"page": 1})
|
||||
normalized = normalize_heading_block(block)
|
||||
self.assertEqual(normalized.type, BlockType.PARAGRAPH)
|
||||
self.assertFalse(is_heading_block(normalized))
|
||||
|
||||
def test_enrich_demotes_overlong_heading_block(self) -> None:
|
||||
blob = (
|
||||
"Master Collection/Pattern Scanning/Strategy Scanning Master Collection/"
|
||||
"Pattern Scanning/Strategy Scanning 及所有大師 /形態/策略指標的位置 "
|
||||
"頁面左側【篩選】欄下方即是【Master Collection】文件夾。點擊此檔夾即可出 "
|
||||
"現下拉頁面,其中包含了十五個大師的選股策略。"
|
||||
)
|
||||
blocks = [
|
||||
Block(type=BlockType.HEADING, text=blob, level=1, meta={"page": 1, "bbox": [90, 90, 500, 240]}),
|
||||
Block(type=BlockType.IMAGE, image_id="a.png", image_path="a.png", meta={"page": 1, "bbox": [90, 250, 500, 480]}),
|
||||
]
|
||||
enriched = enrich_layout_metadata(blocks)
|
||||
self.assertEqual(enriched[0].type, BlockType.PARAGRAPH)
|
||||
self.assertNotEqual(enriched[1].meta.get("bound_heading"), blob)
|
||||
|
||||
def test_top_of_page_numbered_title_not_margin_noise(self) -> None:
|
||||
block = Block(
|
||||
type=BlockType.PARAGRAPH,
|
||||
text="10.上升三角形態",
|
||||
meta={"page": 50, "bbox": [90, 74, 209, 90], "page_height": 842},
|
||||
)
|
||||
self.assertFalse(is_margin_noise_block(block, 842))
|
||||
self.assertEqual(numbered_heading_level("10.上升三角形態"), 1)
|
||||
self.assertTrue(is_heading_block(normalize_heading_block(block)))
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
unittest.main()
|
||||
@@ -0,0 +1,166 @@
|
||||
"""Tests for MinerU content_list → Block mapping."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import tempfile
|
||||
import subprocess
|
||||
import unittest
|
||||
from pathlib import Path
|
||||
from unittest.mock import Mock, patch
|
||||
|
||||
from rag_cut.models import BlockType
|
||||
from rag_cut.parsers.mineru_adapter import (
|
||||
_blocks_from_content_list,
|
||||
_find_content_list,
|
||||
_run_mineru,
|
||||
)
|
||||
|
||||
|
||||
class MineruAdapterProcessTest(unittest.TestCase):
|
||||
def test_default_timeout_allows_large_manual_to_finish(self) -> None:
|
||||
with patch.dict("os.environ", {}, clear=True):
|
||||
from rag_cut.parsers.mineru_adapter import _mineru_timeout_sec
|
||||
|
||||
self.assertEqual(_mineru_timeout_sec(), 540.0)
|
||||
|
||||
def test_configured_api_url_is_passed_to_mineru(self) -> None:
|
||||
process = Mock()
|
||||
process.communicate.return_value = ("", "")
|
||||
process.returncode = 0
|
||||
|
||||
with (
|
||||
tempfile.TemporaryDirectory() as tmp,
|
||||
patch("rag_cut.parsers.mineru_adapter._mineru_command", return_value="mineru"),
|
||||
patch.dict("os.environ", {"RAG_CUT_MINERU_API_URL": "http://127.0.0.1:30000"}),
|
||||
patch("rag_cut.parsers.mineru_adapter.subprocess.Popen", return_value=process) as popen,
|
||||
):
|
||||
ok = _run_mineru(Path(tmp) / "manual.pdf", Path(tmp) / "output")
|
||||
|
||||
self.assertTrue(ok)
|
||||
args = popen.call_args.args[0]
|
||||
self.assertEqual(args[-2:], ["--api-url", "http://127.0.0.1:30000"])
|
||||
|
||||
def test_timeout_terminates_windows_process_tree(self) -> None:
|
||||
process = Mock()
|
||||
process.pid = 4321
|
||||
process.communicate.side_effect = subprocess.TimeoutExpired("mineru", 30)
|
||||
process.poll.return_value = None
|
||||
|
||||
with (
|
||||
tempfile.TemporaryDirectory() as tmp,
|
||||
patch("rag_cut.parsers.mineru_adapter._mineru_command", return_value="mineru"),
|
||||
patch("rag_cut.parsers.mineru_adapter._mineru_timeout_sec", return_value=30),
|
||||
patch("rag_cut.parsers.mineru_adapter.os.name", "nt"),
|
||||
patch("rag_cut.parsers.mineru_adapter.subprocess.Popen", return_value=process),
|
||||
patch("rag_cut.parsers.mineru_adapter.subprocess.run") as run,
|
||||
):
|
||||
ok = _run_mineru(Path(tmp) / "manual.pdf", Path(tmp) / "output")
|
||||
|
||||
self.assertFalse(ok)
|
||||
run.assert_called_once_with(
|
||||
["taskkill", "/PID", "4321", "/T", "/F"],
|
||||
check=False,
|
||||
capture_output=True,
|
||||
timeout=10,
|
||||
)
|
||||
|
||||
|
||||
class MineruAdapterMappingTest(unittest.TestCase):
|
||||
def test_chart_becomes_image_block(self) -> None:
|
||||
with tempfile.TemporaryDirectory() as tmp:
|
||||
assets = Path(tmp)
|
||||
img = assets / "chart.jpg"
|
||||
img.write_bytes(b"fake")
|
||||
items = [
|
||||
{
|
||||
"type": "text",
|
||||
"text": "第二十節 TradingView",
|
||||
"text_level": 2,
|
||||
"page_idx": 30,
|
||||
"bbox": [127, 86, 363, 104],
|
||||
},
|
||||
{
|
||||
"type": "chart",
|
||||
"img_path": "chart.jpg",
|
||||
"page_idx": 30,
|
||||
"bbox": [129, 171, 878, 428],
|
||||
"image_caption": [],
|
||||
},
|
||||
]
|
||||
with patch("rag_cut.parsers.mineru_adapter._mineru_ocr_enabled", return_value=False):
|
||||
blocks = _blocks_from_content_list(items, assets / "content_list.json", assets)
|
||||
|
||||
types = [b.type for b in blocks]
|
||||
self.assertEqual(types, [BlockType.HEADING, BlockType.IMAGE])
|
||||
self.assertEqual(blocks[1].image_id, "chart.jpg")
|
||||
self.assertEqual(blocks[1].meta.get("mineru_type"), "chart")
|
||||
self.assertEqual(blocks[1].meta.get("page"), 31)
|
||||
|
||||
def test_table_keeps_markdown_and_screenshot(self) -> None:
|
||||
with tempfile.TemporaryDirectory() as tmp:
|
||||
assets = Path(tmp)
|
||||
img = assets / "table.png"
|
||||
img.write_bytes(b"png")
|
||||
items = [
|
||||
{
|
||||
"type": "table",
|
||||
"img_path": "table.png",
|
||||
"page_idx": 1,
|
||||
"bbox": [100, 100, 400, 300],
|
||||
"table_body": "<table><tr><td>A</td><td>B</td></tr></table>",
|
||||
}
|
||||
]
|
||||
with patch("rag_cut.parsers.mineru_adapter._mineru_ocr_enabled", return_value=False):
|
||||
blocks = _blocks_from_content_list(items, assets / "content_list.json", assets)
|
||||
|
||||
self.assertEqual(len(blocks), 1)
|
||||
self.assertEqual(blocks[0].type, BlockType.TABLE)
|
||||
self.assertIn("<table>", blocks[0].markdown or "")
|
||||
self.assertEqual(blocks[0].image_id, "table.png")
|
||||
self.assertTrue(blocks[0].image_path)
|
||||
|
||||
def test_page_footnote_kept_as_paragraph(self) -> None:
|
||||
items = [
|
||||
{
|
||||
"type": "page_footnote",
|
||||
"text": "<sup>1</sup> See Market Master.",
|
||||
"page_idx": 8,
|
||||
"bbox": [85, 889, 912, 916],
|
||||
}
|
||||
]
|
||||
with tempfile.TemporaryDirectory() as tmp:
|
||||
blocks = _blocks_from_content_list(items, Path(tmp) / "content_list.json", Path(tmp))
|
||||
self.assertEqual(len(blocks), 1)
|
||||
self.assertEqual(blocks[0].type, BlockType.PARAGRAPH)
|
||||
self.assertTrue(blocks[0].meta.get("is_footnote"))
|
||||
|
||||
def test_list_items_become_paragraph(self) -> None:
|
||||
items = [
|
||||
{
|
||||
"type": "list",
|
||||
"list_items": ["第一點說明", {"text": "第二點說明"}],
|
||||
"page_idx": 2,
|
||||
"bbox": [100, 200, 400, 260],
|
||||
}
|
||||
]
|
||||
with tempfile.TemporaryDirectory() as tmp:
|
||||
blocks = _blocks_from_content_list(items, Path(tmp) / "content_list.json", Path(tmp))
|
||||
self.assertEqual(len(blocks), 1)
|
||||
self.assertEqual(blocks[0].type, BlockType.PARAGRAPH)
|
||||
self.assertIn("第一點說明", blocks[0].text or "")
|
||||
self.assertIn("第二點說明", blocks[0].text or "")
|
||||
|
||||
def test_find_content_list_prefers_non_v2(self) -> None:
|
||||
with tempfile.TemporaryDirectory() as tmp:
|
||||
root = Path(tmp) / "doc" / "auto"
|
||||
root.mkdir(parents=True)
|
||||
v1 = root / "doc_content_list.json"
|
||||
v2 = root / "doc_content_list_v2.json"
|
||||
v1.write_text("[]", encoding="utf-8")
|
||||
v2.write_text("[]", encoding="utf-8")
|
||||
found = _find_content_list(Path(tmp))
|
||||
self.assertEqual(found, v1)
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
unittest.main()
|
||||
@@ -0,0 +1,80 @@
|
||||
"""Tests for parent/child delimiter splitting."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import tempfile
|
||||
import unittest
|
||||
from pathlib import Path
|
||||
|
||||
from rag_cut.models import Block, BlockType, SplitConfig, SplitMode
|
||||
from rag_cut.pipeline import chunk_document
|
||||
from rag_cut.splitters.parent_child import split_by_parent_child
|
||||
|
||||
|
||||
def p(text: str) -> Block:
|
||||
return Block(type=BlockType.PARAGRAPH, text=text)
|
||||
|
||||
|
||||
class ParentChildSplitTest(unittest.TestCase):
|
||||
def test_parent_and_child_chunks_are_linked(self) -> None:
|
||||
blocks = [p("Intro A##Detail A1###Detail A2##Intro B###Detail B1")]
|
||||
groups = split_by_parent_child(
|
||||
blocks,
|
||||
SplitConfig(
|
||||
mode=SplitMode.PARENT_CHILD,
|
||||
parent_delimiter="##",
|
||||
child_delimiter="###",
|
||||
max_chunk_size=2000,
|
||||
child_max_size=500,
|
||||
overlap=0,
|
||||
),
|
||||
)
|
||||
|
||||
parents = [g for g in groups if g.meta.get("is_section_parent")]
|
||||
children = [g for g in groups if g.meta.get("is_sub_chunk")]
|
||||
self.assertGreaterEqual(len(parents), 2)
|
||||
self.assertGreaterEqual(len(children), 2)
|
||||
self.assertTrue(all(g.meta.get("retrieval") is False for g in parents))
|
||||
self.assertTrue(all(g.meta.get("retrieval") is True for g in children))
|
||||
self.assertTrue(all(g.meta.get("parent_section_id") for g in children))
|
||||
|
||||
def test_requires_parent_delimiter(self) -> None:
|
||||
with self.assertRaises(ValueError):
|
||||
split_by_parent_child(
|
||||
[p("hello")],
|
||||
SplitConfig(mode=SplitMode.PARENT_CHILD, parent_delimiter=None),
|
||||
)
|
||||
|
||||
def test_pipeline_persists_parent_chunk_ids(self) -> None:
|
||||
with tempfile.TemporaryDirectory() as tmp:
|
||||
source = Path(tmp) / "pc.md"
|
||||
source.write_text(
|
||||
"Alpha parent##A1 child###A2 child##Beta parent###B1 child",
|
||||
encoding="utf-8",
|
||||
)
|
||||
result = chunk_document(
|
||||
source,
|
||||
config=SplitConfig(
|
||||
mode=SplitMode.PARENT_CHILD,
|
||||
parent_delimiter="##",
|
||||
child_delimiter="###",
|
||||
max_chunk_size=2000,
|
||||
child_max_size=400,
|
||||
overlap=0,
|
||||
),
|
||||
storage_root=Path(tmp) / "storage",
|
||||
)
|
||||
|
||||
self.assertEqual(result.split_mode, SplitMode.PARENT_CHILD)
|
||||
self.assertEqual(result.split_config.get("chunk_strategy"), "parent_child_delimiter")
|
||||
parents = [c for c in result.chunks if c.meta.get("is_section_parent")]
|
||||
children = [c for c in result.chunks if c.meta.get("is_sub_chunk")]
|
||||
self.assertTrue(parents)
|
||||
self.assertTrue(children)
|
||||
for child in children:
|
||||
self.assertIn("parent_chunk_id", child.meta)
|
||||
self.assertIsInstance(child.meta["parent_chunk_id"], int)
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
unittest.main()
|
||||
@@ -0,0 +1,315 @@
|
||||
"""Tests for PDF margin noise filtering."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import unittest
|
||||
from pathlib import Path
|
||||
|
||||
from rag_cut.layout_meta import enrich_layout_metadata, sort_blocks_reading_order
|
||||
from rag_cut.models import Block, BlockType
|
||||
from rag_cut.parsers.mineru_adapter import _blocks_from_content_list
|
||||
from rag_cut.parsers.pdf.noise_filter import (
|
||||
detect_running_header_texts,
|
||||
filter_noise_blocks,
|
||||
filter_toc_blocks,
|
||||
is_margin_noise_block,
|
||||
is_tiny_image_block,
|
||||
is_toc_entry_line,
|
||||
is_toc_title_text,
|
||||
)
|
||||
|
||||
|
||||
class MineruNoiseFilterTest(unittest.TestCase):
|
||||
def test_skips_header_and_page_number_types(self) -> None:
|
||||
items = [
|
||||
{"type": "text", "text": "目錄", "text_level": 2, "page_idx": 1},
|
||||
{
|
||||
"type": "text",
|
||||
"text": "1. 登入 ...3\n2. 股票報價. ....4",
|
||||
"page_idx": 1,
|
||||
"bbox": [114, 190, 883, 517],
|
||||
},
|
||||
{"type": "header", "text": "H5 i-Trade 用戶使用手冊", "page_idx": 1},
|
||||
{"type": "header", "text": "NEN WAFE:SOLUTIONS", "page_idx": 1},
|
||||
{"type": "page_number", "text": "2", "page_idx": 1},
|
||||
]
|
||||
blocks = _blocks_from_content_list(items, Path("content_list.json"), Path("assets"))
|
||||
# MinerU adapter may still emit 目录 text; pipeline noise filter removes it.
|
||||
texts = [block.text for block in blocks]
|
||||
self.assertIn("目錄", texts)
|
||||
self.assertEqual(texts.count("H5 i-Trade 用戶使用手冊"), 0)
|
||||
self.assertEqual(texts.count("2"), 0)
|
||||
filtered = filter_noise_blocks(blocks)
|
||||
filtered_texts = [block.text for block in filtered]
|
||||
self.assertNotIn("目錄", filtered_texts)
|
||||
self.assertFalse(any("登入" in (t or "") for t in filtered_texts))
|
||||
|
||||
|
||||
class NoiseFilterHeuristicTest(unittest.TestCase):
|
||||
def test_margin_page_number_is_noise(self) -> None:
|
||||
block = Block(
|
||||
type=BlockType.PARAGRAPH,
|
||||
text="14",
|
||||
meta={"page": 8, "bbox": [867, 942, 882, 954], "page_height": 1000},
|
||||
)
|
||||
self.assertTrue(is_margin_noise_block(block, 1000))
|
||||
|
||||
def test_body_paragraph_is_kept(self) -> None:
|
||||
block = Block(
|
||||
type=BlockType.PARAGRAPH,
|
||||
text="開啟AFEH5 i-Trade網站,用戶無需登入即可查閱各項延遲15分鐘資訊。",
|
||||
meta={"page": 3, "bbox": [116, 200, 880, 260], "page_height": 1000},
|
||||
)
|
||||
self.assertFalse(is_margin_noise_block(block, 1000))
|
||||
|
||||
def test_running_header_detection(self) -> None:
|
||||
blocks = []
|
||||
for page in range(1, 11):
|
||||
blocks.append(
|
||||
Block(
|
||||
type=BlockType.PARAGRAPH,
|
||||
text="H5 i-Trade 用戶使用手冊",
|
||||
meta={"page": page, "bbox": [651, 79, 882, 97], "page_height": 1000},
|
||||
)
|
||||
)
|
||||
blocks.append(
|
||||
Block(
|
||||
type=BlockType.HEADING,
|
||||
text=f"{page}. 章節",
|
||||
level=2,
|
||||
meta={"page": page, "bbox": [116, 122, 191, 146], "page_height": 1000},
|
||||
)
|
||||
)
|
||||
running = detect_running_header_texts(blocks)
|
||||
self.assertIn("H5 i-Trade 用戶使用手冊", running)
|
||||
self.assertNotIn("1. 章節", running)
|
||||
|
||||
def test_filter_noise_blocks_removes_margin_and_running_text(self) -> None:
|
||||
blocks = [
|
||||
Block(
|
||||
type=BlockType.HEADING,
|
||||
text="目錄",
|
||||
level=2,
|
||||
meta={"page": 2, "bbox": [119, 123, 176, 146], "page_height": 1000},
|
||||
),
|
||||
Block(
|
||||
type=BlockType.PARAGRAPH,
|
||||
text="1. 登入 ...3",
|
||||
meta={"page": 2, "bbox": [114, 190, 883, 517], "page_height": 1000},
|
||||
),
|
||||
Block(
|
||||
type=BlockType.PARAGRAPH,
|
||||
text="2",
|
||||
meta={"page": 2, "bbox": [868, 942, 880, 954], "page_height": 1000},
|
||||
),
|
||||
]
|
||||
for page in range(1, 6):
|
||||
blocks.append(
|
||||
Block(
|
||||
type=BlockType.PARAGRAPH,
|
||||
text="H5 i-Trade 用戶使用手冊",
|
||||
meta={"page": page, "bbox": [651, 79, 882, 97], "page_height": 1000},
|
||||
)
|
||||
)
|
||||
|
||||
filtered = filter_noise_blocks(blocks)
|
||||
texts = [block.text for block in filtered]
|
||||
self.assertNotIn("目錄", texts)
|
||||
self.assertNotIn("1. 登入 ...3", texts)
|
||||
self.assertNotIn("2", texts)
|
||||
self.assertNotIn("H5 i-Trade 用戶使用手冊", texts)
|
||||
|
||||
def test_filter_toc_drops_contents_keeps_in_section_catalog(self) -> None:
|
||||
blocks = [
|
||||
Block(type=BlockType.HEADING, text="Contents", level=1, meta={"page": 1, "bbox": [72, 80, 200, 100]}),
|
||||
Block(
|
||||
type=BlockType.PARAGRAPH,
|
||||
text="1 Intro ........ 3",
|
||||
meta={"page": 1, "bbox": [72, 120, 400, 140]},
|
||||
),
|
||||
Block(
|
||||
type=BlockType.PARAGRAPH,
|
||||
text="2 Setup ........ 8",
|
||||
meta={"page": 1, "bbox": [72, 150, 400, 170]},
|
||||
),
|
||||
Block(
|
||||
type=BlockType.HEADING,
|
||||
text="1 Intro",
|
||||
level=1,
|
||||
meta={"page": 2, "bbox": [72, 100, 200, 120]},
|
||||
),
|
||||
Block(
|
||||
type=BlockType.PARAGRAPH,
|
||||
text="Useful body paragraph describing the product workflow in detail.",
|
||||
meta={"page": 2, "bbox": [72, 140, 500, 200]},
|
||||
),
|
||||
Block(
|
||||
type=BlockType.HEADING,
|
||||
text="形態指標",
|
||||
level=1,
|
||||
meta={"page": 45, "bbox": [72, 200, 200, 220]},
|
||||
),
|
||||
Block(
|
||||
type=BlockType.PARAGRAPH,
|
||||
text="共包含以下11個形態指標說明:",
|
||||
meta={"page": 45, "bbox": [72, 240, 400, 260]},
|
||||
),
|
||||
Block(
|
||||
type=BlockType.HEADING,
|
||||
text="1.頭肩頂形態",
|
||||
level=1,
|
||||
meta={"page": 45, "bbox": [72, 270, 220, 290]},
|
||||
),
|
||||
]
|
||||
self.assertTrue(is_toc_title_text("目錄"))
|
||||
self.assertTrue(is_toc_entry_line("1 Intro ........ 3"))
|
||||
self.assertFalse(is_toc_entry_line("1.頭肩頂形態"))
|
||||
|
||||
filtered = filter_toc_blocks(blocks)
|
||||
texts = [b.text for b in filtered]
|
||||
self.assertNotIn("Contents", texts)
|
||||
self.assertNotIn("1 Intro ........ 3", texts)
|
||||
self.assertIn("1 Intro", texts)
|
||||
self.assertIn("Useful body paragraph describing the product workflow in detail.", texts)
|
||||
self.assertIn("形態指標", texts)
|
||||
self.assertIn("1.頭肩頂形態", texts)
|
||||
|
||||
def test_filter_toc_drops_mineru_compacted_contents_block(self) -> None:
|
||||
contents = Block(
|
||||
type=BlockType.PARAGRAPH,
|
||||
text=(
|
||||
"CONTENTS..\n"
|
||||
"1 GLOSSARY ..2\n"
|
||||
"5.1 AEOI ID SETTING.. 4"
|
||||
),
|
||||
meta={"page": 2, "mineru_type": "text"},
|
||||
)
|
||||
|
||||
self.assertTrue(is_toc_title_text("CONTENTS.."))
|
||||
self.assertTrue(is_toc_entry_line("1 GLOSSARY ..2"))
|
||||
self.assertTrue(is_toc_entry_line("5.1 AEOI ID SETTING.. 4"))
|
||||
self.assertEqual(filter_toc_blocks([contents]), [])
|
||||
|
||||
def test_filter_toc_keeps_real_section_below_directory_on_same_page(self) -> None:
|
||||
blocks = [
|
||||
Block(
|
||||
type=BlockType.HEADING,
|
||||
text="CONTENTS",
|
||||
level=2,
|
||||
meta={"page": 2, "bbox": [115, 129, 284, 152]},
|
||||
),
|
||||
Block(
|
||||
type=BlockType.PARAGRAPH,
|
||||
text="CONTENTS..\n1 GLOSSARY ..2\n2 REFERENCES 3\n3 DOCUMENT HISTORY.. .3",
|
||||
meta={"page": 2, "bbox": [117, 167, 884, 718]},
|
||||
),
|
||||
Block(
|
||||
type=BlockType.HEADING,
|
||||
text="1 GLOSSARY",
|
||||
level=2,
|
||||
meta={"page": 2, "bbox": [117, 771, 321, 793]},
|
||||
),
|
||||
Block(
|
||||
type=BlockType.TABLE,
|
||||
markdown="| Abbreviation | Description |\n| --- | --- |",
|
||||
meta={"page": 2, "bbox": [127, 809, 885, 891]},
|
||||
),
|
||||
]
|
||||
|
||||
filtered = filter_toc_blocks(blocks)
|
||||
self.assertEqual([block.type for block in filtered], [BlockType.HEADING, BlockType.TABLE])
|
||||
self.assertEqual(filtered[0].text, "1 GLOSSARY")
|
||||
|
||||
def test_tiny_logo_image_is_filtered_wide_flowchart_kept(self) -> None:
|
||||
logo = Block(
|
||||
type=BlockType.IMAGE,
|
||||
image_id="logo",
|
||||
image_path="assets/logo.png",
|
||||
meta={"page": 14, "bbox": [121, 420, 156, 445], "page_height": 1000},
|
||||
)
|
||||
flowchart = Block(
|
||||
type=BlockType.IMAGE,
|
||||
image_id="flow",
|
||||
image_path="assets/flow.png",
|
||||
meta={"page": 13, "bbox": [119, 614, 949, 689], "page_height": 1000},
|
||||
)
|
||||
self.assertTrue(is_tiny_image_block(logo))
|
||||
self.assertFalse(is_tiny_image_block(flowchart))
|
||||
|
||||
filtered = filter_noise_blocks([logo, flowchart])
|
||||
ids = [block.image_id for block in filtered]
|
||||
self.assertEqual(ids, ["flow"])
|
||||
|
||||
def test_nested_image_fragment_dropped(self) -> None:
|
||||
outer = Block(
|
||||
type=BlockType.IMAGE,
|
||||
image_id="screenshot",
|
||||
image_path="assets/shot.png",
|
||||
meta={"page": 14, "bbox": [100, 400, 500, 700], "page_height": 1000},
|
||||
)
|
||||
nested = Block(
|
||||
type=BlockType.IMAGE,
|
||||
image_id="icon",
|
||||
image_path="assets/icon.png",
|
||||
meta={"page": 14, "bbox": [200, 450, 280, 530], "page_height": 1000},
|
||||
)
|
||||
filtered = filter_noise_blocks([outer, nested])
|
||||
ids = [block.image_id for block in filtered]
|
||||
self.assertEqual(ids, ["screenshot"])
|
||||
|
||||
|
||||
class LayoutOrderAndBindTest(unittest.TestCase):
|
||||
def test_sort_puts_page_top_before_lower_fragment(self) -> None:
|
||||
misordered = [
|
||||
Block(
|
||||
type=BlockType.IMAGE,
|
||||
image_id="logo",
|
||||
image_path="assets/logo.png",
|
||||
meta={"page": 14, "bbox": [121, 420, 156, 445]},
|
||||
),
|
||||
Block(
|
||||
type=BlockType.PARAGRAPH,
|
||||
text="5.8 APPENDIX",
|
||||
meta={"page": 14, "bbox": [114, 85, 324, 107]},
|
||||
),
|
||||
Block(
|
||||
type=BlockType.PARAGRAPH,
|
||||
text="5.9 FAQ",
|
||||
meta={"page": 14, "bbox": [114, 334, 231, 355]},
|
||||
),
|
||||
]
|
||||
ordered = sort_blocks_reading_order(misordered)
|
||||
texts = [(b.image_id or b.text) for b in ordered]
|
||||
self.assertEqual(texts, ["5.8 APPENDIX", "5.9 FAQ", "logo"])
|
||||
|
||||
def test_enrich_binds_image_to_spatial_heading(self) -> None:
|
||||
blocks = [
|
||||
Block(
|
||||
type=BlockType.HEADING,
|
||||
text="5.7.2Subsequent submissions",
|
||||
level=3,
|
||||
meta={"page": 13, "bbox": [115, 468, 465, 488]},
|
||||
),
|
||||
Block(
|
||||
type=BlockType.IMAGE,
|
||||
image_id="wrong_early",
|
||||
image_path="assets/x.png",
|
||||
meta={"page": 14, "bbox": [341, 513, 431, 648]},
|
||||
),
|
||||
Block(
|
||||
type=BlockType.PARAGRAPH,
|
||||
text="5.9 FAQ",
|
||||
meta={"page": 14, "bbox": [114, 334, 231, 355]},
|
||||
),
|
||||
]
|
||||
enriched = enrich_layout_metadata(blocks)
|
||||
faq_img = next(b for b in enriched if b.type == BlockType.IMAGE)
|
||||
self.assertEqual(faq_img.meta.get("bound_heading"), "5.9 FAQ")
|
||||
self.assertLess(
|
||||
next(b for b in enriched if b.text == "5.9 FAQ").meta["order_index"],
|
||||
faq_img.meta["order_index"],
|
||||
)
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
unittest.main()
|
||||
@@ -0,0 +1,51 @@
|
||||
"""Tests for recall ranking and retrieval eligibility."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import unittest
|
||||
|
||||
from rag_cut.models import Chunk
|
||||
from rag_cut.retrieval import recall_chunks
|
||||
|
||||
|
||||
def chunk(index: int, content: str, *, retrieval: bool = True, heading: str = "") -> Chunk:
|
||||
return Chunk(
|
||||
index=index,
|
||||
content=content,
|
||||
char_count=len(content),
|
||||
block_types=["paragraph"],
|
||||
meta={"retrieval": retrieval, "heading": heading},
|
||||
)
|
||||
|
||||
|
||||
class RecallChunksTest(unittest.TestCase):
|
||||
def test_relevant_chunk_ranks_first(self) -> None:
|
||||
results, candidate_count = recall_chunks(
|
||||
"股票交易密码",
|
||||
[
|
||||
chunk(0, "登录后可以修改股票交易密码", heading="账户安全"),
|
||||
chunk(1, "年度报告及公司治理", heading="公司资料"),
|
||||
],
|
||||
top_k=2,
|
||||
)
|
||||
|
||||
self.assertEqual(candidate_count, 2)
|
||||
self.assertEqual(results[0]["chunk_index"], 0)
|
||||
self.assertGreater(results[0]["score"], 0)
|
||||
|
||||
def test_preview_only_chunks_are_not_candidates(self) -> None:
|
||||
results, candidate_count = recall_chunks(
|
||||
"logo",
|
||||
[chunk(0, "", retrieval=False), chunk(1, "Useful body")],
|
||||
)
|
||||
|
||||
self.assertEqual(candidate_count, 1)
|
||||
self.assertEqual(results, [])
|
||||
|
||||
def test_top_k_is_respected(self) -> None:
|
||||
results, _ = recall_chunks("account", [chunk(i, f"account details {i}") for i in range(5)], top_k=2)
|
||||
self.assertEqual(len(results), 2)
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
unittest.main()
|
||||
@@ -0,0 +1,80 @@
|
||||
"""Tests for spreadsheet layout detection and row splitting."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import unittest
|
||||
|
||||
from rag_cut.parsers.pdf.tables import detect_spreadsheet_layout, is_qa_style_table
|
||||
from rag_cut.pipeline import chunk_document
|
||||
from rag_cut.splitters.by_row import split_by_row
|
||||
from rag_cut.models import Block, BlockType, SplitConfig, SplitMode
|
||||
|
||||
|
||||
BACKMAN_HEADER = [
|
||||
[
|
||||
"Session会话(必填):用于标识1个对话",
|
||||
"query 用户输入(必填):消息内容",
|
||||
"用户ID(必填)",
|
||||
"使用的大语言模型(必填)",
|
||||
"要求AI回复的语言(必填)",
|
||||
"reference_output 标准答案(可选)",
|
||||
],
|
||||
["session", "query", "userid", "model", "lang", "reference_output"],
|
||||
["1", "账户余额是多少?", "SUPPORT", "gpt-4o-mini", "zh", "SELECT 1"],
|
||||
["2", "今日有哪些账户透支?", "SUPPORT", "gpt-4o-mini", "zh", "SELECT 2"],
|
||||
]
|
||||
|
||||
|
||||
class SpreadsheetLayoutTest(unittest.TestCase):
|
||||
def test_detect_template_description_and_header_rows(self) -> None:
|
||||
layout = detect_spreadsheet_layout(BACKMAN_HEADER)
|
||||
self.assertEqual(layout["preamble_rows"], 1)
|
||||
self.assertEqual(layout["header_row_start"], 2)
|
||||
self.assertEqual(layout["header_row_end"], 2)
|
||||
self.assertEqual(layout["data_start_row"], 3)
|
||||
self.assertTrue(is_qa_style_table(BACKMAN_HEADER, layout))
|
||||
|
||||
def test_split_by_row_uses_real_header_and_one_row_per_chunk(self) -> None:
|
||||
layout = detect_spreadsheet_layout(BACKMAN_HEADER)
|
||||
block = Block(
|
||||
type=BlockType.TABLE,
|
||||
markdown="",
|
||||
meta={"rows": BACKMAN_HEADER, "table_title": "testset", **layout},
|
||||
)
|
||||
groups = split_by_row(
|
||||
[block],
|
||||
SplitConfig(
|
||||
mode=SplitMode.BY_ROW,
|
||||
header_row_start=layout["header_row_start"],
|
||||
header_row_end=layout["header_row_end"],
|
||||
start_row=layout["data_start_row"],
|
||||
rows_per_chunk=1,
|
||||
),
|
||||
)
|
||||
self.assertEqual(len(groups), 2)
|
||||
first_md = groups[0][0].markdown
|
||||
self.assertIn("| session | query | userid | model | lang | reference_output |", first_md)
|
||||
self.assertIn("账户余额是多少?", first_md)
|
||||
self.assertNotIn("Session会话(必填)", first_md)
|
||||
|
||||
|
||||
class BackmanFixtureTest(unittest.TestCase):
|
||||
def test_backman_upload_chunks_one_row_each(self) -> None:
|
||||
from pathlib import Path
|
||||
|
||||
uploads = list((Path(__file__).resolve().parents[2] / "storage" / "uploads").rglob("BackmanAI*.xlsx"))
|
||||
if not uploads:
|
||||
self.skipTest("BackmanAI fixture not uploaded")
|
||||
result = chunk_document(uploads[0])
|
||||
self.assertEqual(result.split_config["rows_per_chunk"], 1)
|
||||
self.assertEqual(result.split_config["header_row_start"], 2)
|
||||
self.assertEqual(result.split_config["start_row"], 3)
|
||||
self.assertGreaterEqual(result.chunk_count, 40)
|
||||
first = result.chunks[0].content
|
||||
self.assertIn("| session | query |", first)
|
||||
self.assertNotIn("Session会话(必填)", first)
|
||||
self.assertLess(result.chunks[0].char_count, 1200)
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
unittest.main()
|
||||
@@ -0,0 +1,40 @@
|
||||
Pages: 3
|
||||
Path: C:\Users\24019\Desktop\RAG-cut\docx\自研搭建AI助手知识库.pdf
|
||||
|
||||
============================================================
|
||||
PAGE 1 | images=1 text_blocks=17
|
||||
============================================================
|
||||
自研搭建AI助手知识库
|
||||
背景
|
||||
AFE有自建自有知识库功能,但知识库的切片效果不佳,存在两个问题:
|
||||
1、文档处理能力不足:包括word/pdf/excel文档中的图片、表格无法有效提取处理;
|
||||
2、切片规则不佳:如下图一段文本被强硬拆分在两个不同的片段;
|
||||
任务
|
||||
搭建一个AI助手知识库demo,能支持上传文件,查看切片效果;可以测试召回效果,查看召回入参和
|
||||
回参;
|
||||
目标
|
||||
目标:首要做好切片,其次是召回。
|
||||
支持文档类型:
|
||||
pdf、doc、docx、ppt、pptx、wps、ppsx
|
||||
xlsx、xls、csv、md、txt、html、json、xml、log
|
||||
jpg、png、jpeg、bmp、gif
|
||||
切片规则:
|
||||
表格文档:默认切分/按行切分
|
||||
其他文档:默认切分/通用标识符切分
|
||||
|
||||
============================================================
|
||||
PAGE 2 | images=2 text_blocks=6
|
||||
============================================================
|
||||
切片内表格:Markdown格式
|
||||
期望
|
||||
期望效果(基础):
|
||||
1. 图片展示在原文本展示的问题,不会丢失或者移动到其他位置
|
||||
2. 表格内容正确提取,并整理为markdown文本
|
||||
3. 切片规则合理,对于word至少同一个标题下的内容在一个切片中
|
||||
|
||||
============================================================
|
||||
PAGE 3 | images=4 text_blocks=3
|
||||
============================================================
|
||||
期望效果(高级):
|
||||
1. 对图片图形能够提取为图片,且识别文本信息转为文字
|
||||
2. 对pdf水平分布的栏目文本能够识别为正常顺序
|
||||
@@ -0,0 +1,103 @@
|
||||
# MinerU 解析层接入说明
|
||||
|
||||
RAG-cut 将 MinerU 作为可选的高质量文档解析后端,用于提升 PDF 的版面分析、OCR、图片/表格提取质量;切割策略仍由 RAG-cut 负责。
|
||||
|
||||
## 启用方式
|
||||
|
||||
默认模式:
|
||||
|
||||
```bash
|
||||
RAG_CUT_PDF_ENGINE=auto
|
||||
```
|
||||
|
||||
含义:
|
||||
|
||||
- 如果本机可用 `mineru` 或 `magic-pdf` 命令,优先调用 MinerU。
|
||||
- 如果 MinerU 未安装或解析失败,自动回退到现有 PyMuPDF/pdfplumber 管线。
|
||||
|
||||
强制使用 MinerU:
|
||||
|
||||
```bash
|
||||
RAG_CUT_PDF_ENGINE=mineru
|
||||
```
|
||||
|
||||
强制使用原 PyMuPDF 管线:
|
||||
|
||||
```bash
|
||||
RAG_CUT_PDF_ENGINE=pymupdf
|
||||
```
|
||||
|
||||
如果命令不在 PATH 中,可指定:
|
||||
|
||||
```bash
|
||||
RAG_CUT_MINERU_CMD=/path/to/mineru
|
||||
```
|
||||
|
||||
## 大文档推荐配置
|
||||
|
||||
`mineru` CLI 默认会为每次调用临时启动 API 和模型进程。处理页数较多的 Office/PDF
|
||||
文档时,建议单独启动一个常驻 MinerU API,避免重复加载模型。
|
||||
|
||||
先在一个终端启动服务:
|
||||
|
||||
```powershell
|
||||
python -m mineru.cli.fast_api --host 127.0.0.1 --port 30000
|
||||
```
|
||||
|
||||
再在启动 RAG-cut 后端的终端中配置并启动:
|
||||
|
||||
```powershell
|
||||
$env:RAG_CUT_MINERU_API_URL = "http://127.0.0.1:30000"
|
||||
$env:RAG_CUT_MINERU_TIMEOUT = "540"
|
||||
python backend/run.py
|
||||
```
|
||||
|
||||
未配置常驻 API 时,RAG-cut 仍可使用临时服务;若解析超时,会结束 MinerU 的完整
|
||||
进程树,避免模型子进程残留并拖慢后续请求。
|
||||
|
||||
## 数据流
|
||||
|
||||
```text
|
||||
PDF
|
||||
-> MinerU 解析 content_list.json / 图片资产
|
||||
-> 转换为 RAG-cut Block
|
||||
-> RAG-cut 自动判断 PDF 策略
|
||||
-> feature_step_screenshot 或 outline_report 切割
|
||||
-> Chunk + metadata + embedding_text
|
||||
```
|
||||
|
||||
## 统一 Block 映射
|
||||
|
||||
| MinerU 内容 | RAG-cut Block |
|
||||
| --- | --- |
|
||||
| title / heading / text_level | heading |
|
||||
| text | paragraph |
|
||||
| image / figure / **chart** / diagram / equation… | image(复制 img 资产) |
|
||||
| table(含可选截图) | table(markdown + 可选 image_path) |
|
||||
| code(有图则按图,否则按正文) | image / paragraph |
|
||||
| page_footnote | paragraph(`is_footnote`) |
|
||||
| header / footer / page_number | 丢弃 |
|
||||
|
||||
图片若无 MinerU OCR,默认用本地 Tesseract 回填(繁体优先):
|
||||
|
||||
```bash
|
||||
RAG_CUT_MINERU_OCR=1 # 默认开启;设为 0 可关闭以加快大批量切分
|
||||
```
|
||||
|
||||
保留字段:
|
||||
|
||||
- page
|
||||
- bbox
|
||||
- image_path
|
||||
- ocr_text
|
||||
- caption
|
||||
- mineru_type
|
||||
- parser=mineru
|
||||
|
||||
## 设计原则
|
||||
|
||||
MinerU 只提升解析质量,不决定 chunk 语义边界。不同文档类型的切割仍由 RAG-cut 策略层处理:
|
||||
|
||||
- 操作手册:功能章节 + 操作步骤 + 截图区域
|
||||
- 年报/研报:章节报告
|
||||
- 表格:表头 + 行组
|
||||

Binary file not shown.
|
After Width: | Height: | Size: 366 KiB |

Binary file not shown.
|
After Width: | Height: | Size: 304 KiB |

Binary file not shown.
|
After Width: | Height: | Size: 629 KiB |
@@ -0,0 +1,189 @@
|
||||
# 腾讯云智能体开发平台:文档切分设置
|
||||
|
||||
> 来源页面:[腾讯云文档 - 文档切分设置](https://cloud.tencent.com/document/product/1759/122551)
|
||||
> 页面最近更新时间:2025-12-31 16:49:32
|
||||
> 整理说明:本文为根据页面内容整理的 Markdown 版,保留核心概念、功能入口、规则对比和关键参数说明,并非网页原文逐字复制。
|
||||
|
||||
## 1. 功能概述
|
||||
|
||||
文档切分是指系统按照一定规则,将上传到知识库的文档拆分为多个独立切片。切片会被索引并存储,是 RAG(Retrieval-Augmented Generation,检索增强生成)流程中的关键环节。
|
||||
|
||||
在问答场景中,系统通常会先根据用户问题检索相关切片,再把命中的切片作为外部知识放入大模型上下文,从而辅助模型生成答案。
|
||||
|
||||
切分粒度会直接影响检索质量和回答效果:
|
||||
|
||||
- 切片过大:容易包含无关内容,降低检索精度,也会增加上下文和计算资源消耗。
|
||||
- 切片过小:上下文不完整,知识片段更碎片化,可能导致回答不够全面。
|
||||
- 合理切分:需要在检索效率、上下文完整性和生成质量之间取得平衡。
|
||||
|
||||
## 2. 切分规则类型
|
||||
|
||||
平台支持两类文档切分方式:
|
||||
|
||||
- 默认切分规则:由平台使用模型能力自动切分,用户不能直接干预具体规则。
|
||||
- 自定义切分规则:用户可根据业务需求设置切分方式,主要包括通用标识符切分、父子标识符切分和按行切分。
|
||||
|
||||
## 3. 切分规则对比
|
||||
|
||||
| 切分方式 | 适用文档类型 | 典型使用场景 | 核心逻辑 |
|
||||
|---|---|---|---|
|
||||
| 默认切分 | 平台支持导入的全部文档类型 | 对切分无特殊要求的知识库文档 | 基于切分模型处理,关注语义完整性、复杂元素解析和表格处理 |
|
||||
| 通用标识符切分 | 非表格类文档,不包括 xlsx、xls、csv | 需要按页码、自定义符号或业务段落进行切分 | 用户设置标识符、最大长度和重叠长度,切片同时用于检索和召回 |
|
||||
| 父子标识符切分 | 非表格类文档,不包括 xlsx、xls、csv | 检索粒度和召回粒度需要分离的场景 | 子级切片用于检索,命中后召回对应父级切片给大模型 |
|
||||
| 按行切分 | 表格类文档,包括 xlsx、xls、csv | 表格每行或每几行相对独立,如商品 SKU 文档 | 用户设置表头范围、起始行和每个切片包含的行数 |
|
||||
|
||||
## 4. 默认切分能力
|
||||
|
||||
默认切分由平台模型完成,适合大多数不需要精细控制切片边界的文档。
|
||||
|
||||
平台默认切分能力包括:
|
||||
|
||||
- 支持按语义完整性切分。
|
||||
- 支持跨页表格合并。
|
||||
- 支持解析表格中的图片信息。
|
||||
- 支持解析有线表格和无线表格。
|
||||
- 支持解析数据图、流程图、架构图、思维导图。
|
||||
- 支持处理多栏、公式、子图等复杂版式元素。
|
||||
|
||||
## 5. 功能入口
|
||||
|
||||
### 入口一:上传文档时设置
|
||||
|
||||
在知识库中上传文档时,流程通常包括:
|
||||
|
||||
1. 上传文档。
|
||||
2. 设置文档切片。
|
||||
3. 按文档类型对同一批上传文档生效。
|
||||
|
||||
图示来源:
|
||||
|
||||
|
||||
|
||||
### 入口二:已导入文档重新设置
|
||||
|
||||
对已经导入知识库的文档,可以重新设置切分规则:
|
||||
|
||||
1. 进入知识库。
|
||||
2. 找到指定文档。
|
||||
3. 点击文档右侧的“更多”。
|
||||
4. 选择“解析切分干预”。
|
||||
5. 查看解析切分结果。
|
||||
6. 点击“文档切分设置”重新配置切分规则。
|
||||
|
||||
图示来源:
|
||||
|
||||

|
||||
|
||||
|
||||
|
||||
注意:重新设置文档切分规则后,系统会按照原文档重新切分,并覆盖之前干预过的切分结果。
|
||||
|
||||
## 6. 表格文档切分
|
||||
|
||||
表格类文档包括 xlsx、xls、csv。平台对表格文档支持默认切分和按行切分。
|
||||
|
||||
### 6.1 默认切分
|
||||
|
||||
默认切分会使用平台切分模型,根据表格行数、语义完整性等因素自动处理。
|
||||
|
||||
### 6.2 按行切分
|
||||
|
||||
按行切分适合每行或每几行数据相对独立的表格,例如商品 SKU 表、配置清单、结构化数据表等。
|
||||
|
||||
关键参数如下:
|
||||
|
||||
| 参数 | 说明 |
|
||||
|---|---|
|
||||
| 表头范围 | 选择表格中的表头行,每个切片都会包含表头数据;区间最大支持 5 行 |
|
||||
| 切分起始行 | 指定从哪一行开始切分;起始行不能与表头范围重复 |
|
||||
| 切分行数 | 指定每个切片从起始行开始包含多少行数据 |
|
||||
|
||||
示例:如果表头为第 1 行,切分起始行为第 2 行,切分行数为 1,则第一个切片为“表头 + 第 2 行”,第二个切片为“表头 + 第 3 行”,依此类推。
|
||||
|
||||
图示来源:
|
||||
|
||||
|
||||
|
||||
## 7. 非表格文档切分
|
||||
|
||||
非表格类文档指知识库中除 xlsx、xls、csv 之外的文档类型。平台支持默认切分、通用标识符切分和父子级标识符切分。
|
||||
|
||||
### 7.1 默认切分
|
||||
|
||||
默认切分会使用平台切分模型,根据语义完整性进行自动切分。
|
||||
|
||||
### 7.2 通用标识符切分
|
||||
|
||||
通用标识符切分适合需要按特定符号或业务结构拆分文档的场景,例如按照 `###`、`***`、章节分隔符或自定义标记切分。
|
||||
|
||||
关键参数如下:
|
||||
|
||||
| 参数 | 说明 |
|
||||
|---|---|
|
||||
| 标识符 | 系统按照用户设置的标识符切分文档;切分标识符不会出现在最终切片中 |
|
||||
| 切分最大长度 | 每个切片允许的最大字符数;如果按标识符切出的片段超过最大长度,会继续按长度拆分;最大不超过 4800 字符 |
|
||||
| 切分重叠长度 | 当片段超过最大长度需要继续拆分时,保留相邻切片之间的重叠字符,用于维持语义连续性 |
|
||||
|
||||
设置建议:
|
||||
|
||||
- 切分重叠长度可设置为切分最大长度的约 10%。
|
||||
- 切分重叠长度最高可设置为切分最大长度的 25%。
|
||||
|
||||
图示来源:
|
||||
|
||||
|
||||
|
||||
### 7.3 父子级标识符切分
|
||||
|
||||
父子级标识符切分适合需要“细粒度检索、粗粒度召回”的知识库场景。系统会先把文档拆成父级切片,再把父级切片拆成一个或多个子级切片。
|
||||
|
||||
工作方式:
|
||||
|
||||
1. 用户问题先检索子级切片。
|
||||
2. 命中子级切片后,系统找到对应父级切片。
|
||||
3. 父级切片被召回给大模型用于答案生成。
|
||||
|
||||
这种方式的优点是:
|
||||
|
||||
- 子级切片更短,有利于提升检索精度。
|
||||
- 父级切片保留更多上下文,有利于提高生成答案的完整性。
|
||||
|
||||
约束条件:
|
||||
|
||||
- 子级切片最大长度不能超过父级切片最大长度。
|
||||
- 子级切片最大可设置为 1500 字符。
|
||||
- 子级切片与父级切片是一对一或多对一关系。
|
||||
|
||||
图示来源:
|
||||
|
||||
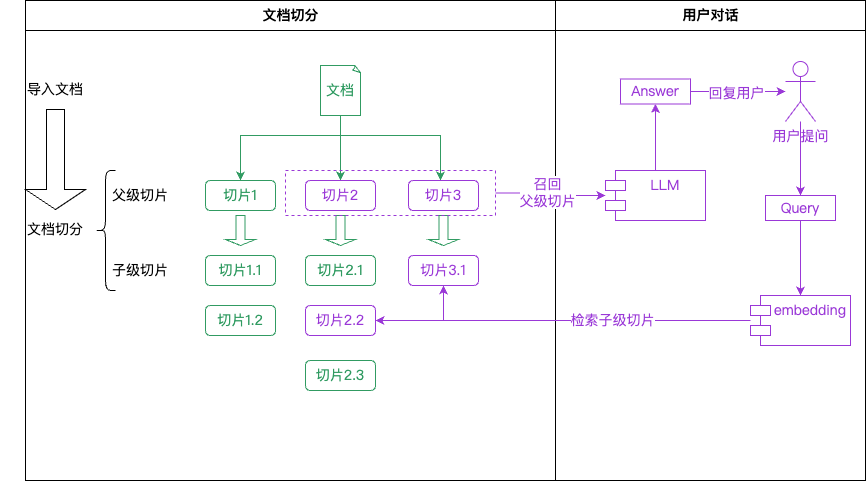
|
||||
|
||||
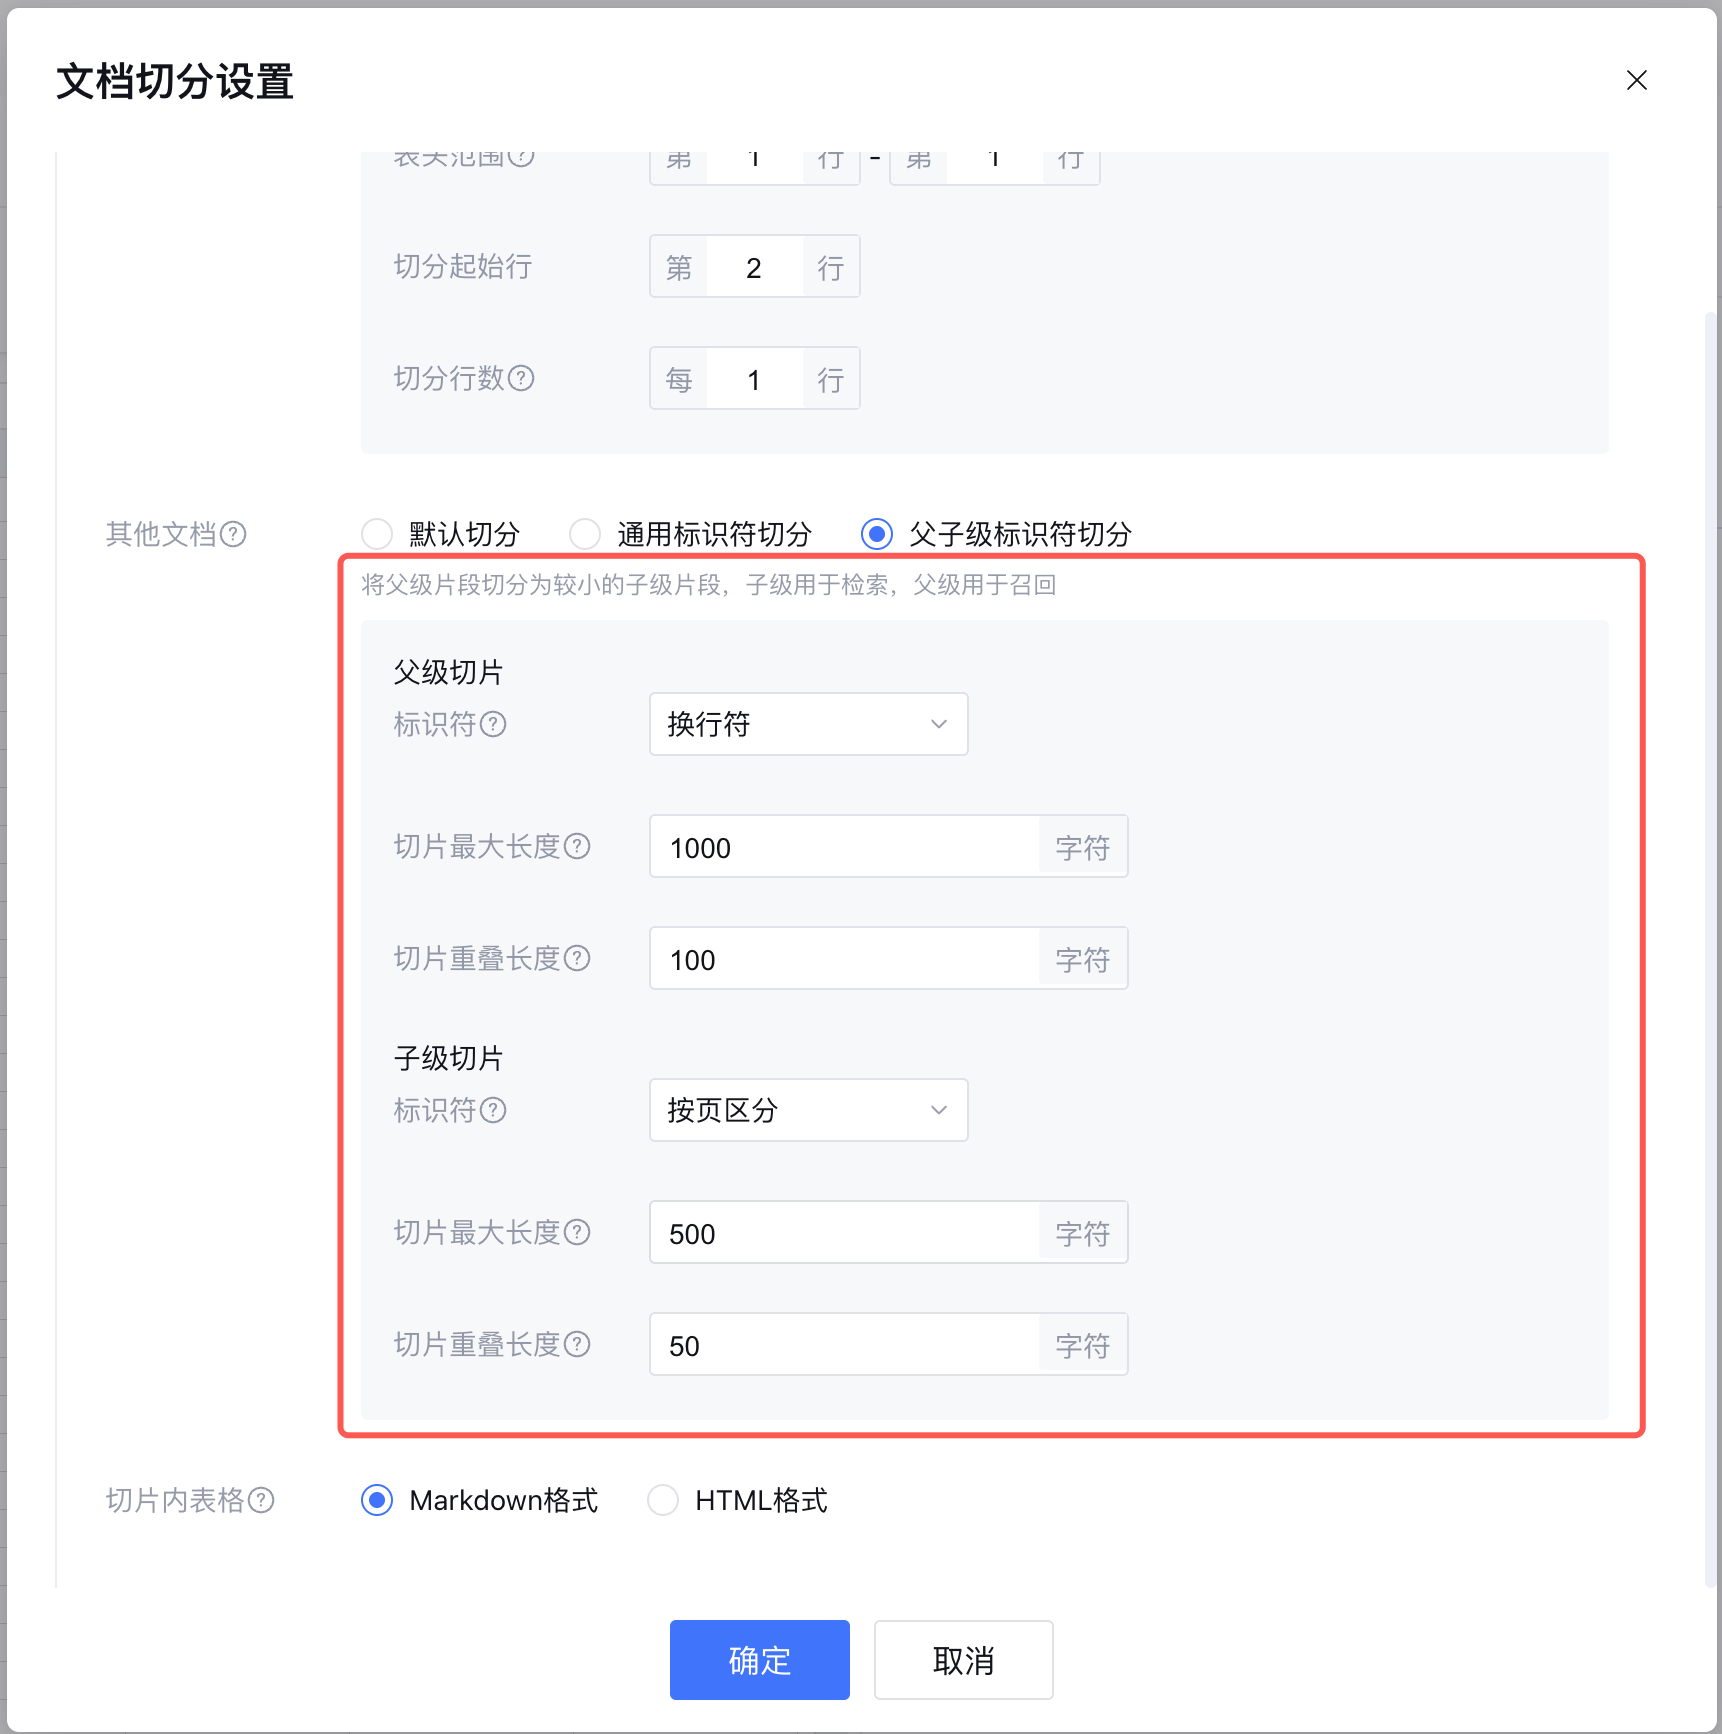
|
||||
|
||||
## 8. 切分内表格格式
|
||||
|
||||
平台支持设置文档中表格内容的切片格式:
|
||||
|
||||
| 格式 | 特点 |
|
||||
|---|---|
|
||||
| Markdown 格式 | 默认格式,通常效果更好,便于模型理解表格结构 |
|
||||
| HTML 格式 | token 消耗相对更少 |
|
||||
|
||||
该设置对普通文档中的表格内容,以及表格文档中的内容均可生效。
|
||||
|
||||
## 9. 使用建议
|
||||
|
||||
| 场景 | 推荐切分方式 |
|
||||
|---|---|
|
||||
| 普通知识库文档,无特殊切分要求 | 默认切分 |
|
||||
| 文档结构清晰,有固定章节、页码或分隔符 | 通用标识符切分 |
|
||||
| 希望检索更精准,同时召回更完整上下文 | 父子级标识符切分 |
|
||||
| 表格每行是独立数据,如商品、配置、SKU | 按行切分 |
|
||||
| 文档表格较多,且希望模型更好理解结构 | Markdown 表格格式 |
|
||||
| token 成本敏感,表格结构不复杂 | HTML 表格格式 |
|
||||
|
||||
## 10. 相关页面
|
||||
|
||||
- 上一篇:文档概述
|
||||
- 下一篇:解析切分干预
|
||||
- 原始页面:[文档切分设置](https://cloud.tencent.com/document/product/1759/122551)
|
||||
Binary file not shown.
@@ -0,0 +1,807 @@
|
||||
/* RAG-cut Design System — ui-ux-pro-max: Accessible & Ethical + Tech SaaS */
|
||||
|
||||
:root {
|
||||
--color-primary: #2563eb;
|
||||
--color-primary-hover: #1d4ed8;
|
||||
--color-secondary: #3b82f6;
|
||||
--color-cta: #f97316;
|
||||
--color-bg: #f8fafc;
|
||||
--color-surface: #ffffff;
|
||||
--color-border: #e2e8f0;
|
||||
--color-border-strong: #cbd5e1;
|
||||
--color-text: #1e293b;
|
||||
--color-text-muted: #64748b;
|
||||
--color-text-subtle: #94a3b8;
|
||||
--color-success: #16a34a;
|
||||
--color-error: #dc2626;
|
||||
--color-focus: #2563eb;
|
||||
--color-chunk-active: #eff6ff;
|
||||
--color-chunk-border: #93c5fd;
|
||||
|
||||
--font-heading: "Space Grotesk", system-ui, sans-serif;
|
||||
--font-body: "DM Sans", system-ui, sans-serif;
|
||||
--font-mono: "JetBrains Mono", ui-monospace, monospace;
|
||||
|
||||
--radius-sm: 6px;
|
||||
--radius-md: 8px;
|
||||
--radius-lg: 12px;
|
||||
--shadow-sm: 0 1px 2px rgba(15, 23, 42, 0.06);
|
||||
--shadow-md: 0 4px 12px rgba(15, 23, 42, 0.08);
|
||||
|
||||
--space-1: 4px;
|
||||
--space-2: 8px;
|
||||
--space-3: 12px;
|
||||
--space-4: 16px;
|
||||
--space-5: 24px;
|
||||
--space-6: 32px;
|
||||
|
||||
--transition: 180ms ease;
|
||||
--header-h: 64px;
|
||||
--sidebar-w: 300px;
|
||||
}
|
||||
|
||||
@media (prefers-reduced-motion: reduce) {
|
||||
*, *::before, *::after {
|
||||
animation-duration: 0.01ms !important;
|
||||
transition-duration: 0.01ms !important;
|
||||
}
|
||||
}
|
||||
|
||||
*, *::before, *::after { box-sizing: border-box; }
|
||||
|
||||
html { font-size: 16px; scroll-behavior: smooth; }
|
||||
|
||||
body {
|
||||
margin: 0;
|
||||
font-family: var(--font-body);
|
||||
color: var(--color-text);
|
||||
background: var(--color-bg);
|
||||
line-height: 1.5;
|
||||
min-height: 100dvh;
|
||||
}
|
||||
|
||||
.sr-only {
|
||||
position: absolute;
|
||||
width: 1px;
|
||||
height: 1px;
|
||||
padding: 0;
|
||||
margin: -1px;
|
||||
overflow: hidden;
|
||||
clip: rect(0, 0, 0, 0);
|
||||
white-space: nowrap;
|
||||
border: 0;
|
||||
}
|
||||
|
||||
.skip-link {
|
||||
position: absolute;
|
||||
top: -100%;
|
||||
left: var(--space-4);
|
||||
z-index: 1000;
|
||||
padding: var(--space-2) var(--space-4);
|
||||
background: var(--color-primary);
|
||||
color: #fff;
|
||||
border-radius: var(--radius-sm);
|
||||
text-decoration: none;
|
||||
font-weight: 600;
|
||||
}
|
||||
.skip-link:focus { top: var(--space-2); }
|
||||
|
||||
/* Header */
|
||||
.app-header {
|
||||
position: sticky;
|
||||
top: 0;
|
||||
z-index: 100;
|
||||
display: flex;
|
||||
align-items: center;
|
||||
justify-content: space-between;
|
||||
height: var(--header-h);
|
||||
padding: 0 var(--space-5);
|
||||
background: var(--color-surface);
|
||||
border-bottom: 1px solid var(--color-border);
|
||||
box-shadow: var(--shadow-sm);
|
||||
}
|
||||
|
||||
.brand {
|
||||
display: flex;
|
||||
align-items: center;
|
||||
gap: var(--space-3);
|
||||
}
|
||||
|
||||
.brand-icon { color: var(--color-primary); flex-shrink: 0; }
|
||||
|
||||
.brand h1 {
|
||||
margin: 0;
|
||||
font-family: var(--font-heading);
|
||||
font-size: 1.25rem;
|
||||
font-weight: 700;
|
||||
letter-spacing: -0.02em;
|
||||
}
|
||||
|
||||
.brand-sub {
|
||||
margin: 0;
|
||||
font-size: 0.8125rem;
|
||||
color: var(--color-text-muted);
|
||||
}
|
||||
|
||||
.badge {
|
||||
display: inline-flex;
|
||||
align-items: center;
|
||||
padding: var(--space-1) var(--space-3);
|
||||
border-radius: 999px;
|
||||
font-size: 0.8125rem;
|
||||
font-weight: 500;
|
||||
}
|
||||
.badge-idle { background: #f1f5f9; color: var(--color-text-muted); }
|
||||
.badge-loading { background: #fef3c7; color: #92400e; }
|
||||
.badge-success { background: #dcfce7; color: #166534; }
|
||||
.badge-error { background: #fee2e2; color: var(--color-error); }
|
||||
|
||||
/* Layout */
|
||||
.app-layout {
|
||||
display: grid;
|
||||
grid-template-columns: var(--sidebar-w) 1fr;
|
||||
min-height: calc(100dvh - var(--header-h));
|
||||
}
|
||||
|
||||
.config-panel {
|
||||
background: var(--color-surface);
|
||||
border-right: 1px solid var(--color-border);
|
||||
padding: var(--space-5);
|
||||
overflow-y: auto;
|
||||
max-height: calc(100dvh - var(--header-h));
|
||||
}
|
||||
|
||||
.panel-section { margin-bottom: var(--space-5); }
|
||||
.panel-section h2 {
|
||||
margin: 0 0 var(--space-3);
|
||||
font-family: var(--font-heading);
|
||||
font-size: 0.875rem;
|
||||
font-weight: 600;
|
||||
text-transform: uppercase;
|
||||
letter-spacing: 0.04em;
|
||||
color: var(--color-text-muted);
|
||||
}
|
||||
|
||||
/* Dropzone */
|
||||
.dropzone {
|
||||
display: flex;
|
||||
flex-direction: column;
|
||||
align-items: center;
|
||||
justify-content: center;
|
||||
gap: var(--space-2);
|
||||
min-height: 140px;
|
||||
padding: var(--space-5);
|
||||
border: 2px dashed var(--color-border-strong);
|
||||
border-radius: var(--radius-lg);
|
||||
background: var(--color-bg);
|
||||
cursor: pointer;
|
||||
transition: border-color var(--transition), background var(--transition);
|
||||
text-align: center;
|
||||
}
|
||||
.dropzone:hover, .dropzone:focus-visible, .dropzone.dragover {
|
||||
border-color: var(--color-primary);
|
||||
background: #eff6ff;
|
||||
outline: none;
|
||||
}
|
||||
.dropzone:focus-visible { box-shadow: 0 0 0 3px rgba(37, 99, 235, 0.35); }
|
||||
.dropzone svg { color: var(--color-text-subtle); }
|
||||
.dropzone-title { margin: 0; font-weight: 600; font-size: 0.9375rem; }
|
||||
.dropzone-hint { margin: 0; font-size: 0.8125rem; color: var(--color-text-muted); }
|
||||
.dropzone-file { margin: var(--space-2) 0 0; font-size: 0.8125rem; color: var(--color-primary); font-weight: 500; word-break: break-all; }
|
||||
|
||||
/* Form */
|
||||
.config-form { display: flex; flex-direction: column; gap: var(--space-3); }
|
||||
.field { display: flex; flex-direction: column; gap: var(--space-1); }
|
||||
.field-row { display: grid; grid-template-columns: 1fr 1fr; gap: var(--space-3); }
|
||||
.field label { font-size: 0.8125rem; font-weight: 500; color: var(--color-text); }
|
||||
.field input, .field select {
|
||||
height: 44px;
|
||||
padding: 0 var(--space-3);
|
||||
border: 1px solid var(--color-border-strong);
|
||||
border-radius: var(--radius-sm);
|
||||
font-family: var(--font-body);
|
||||
font-size: 0.9375rem;
|
||||
color: var(--color-text);
|
||||
background: var(--color-surface);
|
||||
transition: border-color var(--transition), box-shadow var(--transition);
|
||||
}
|
||||
.field input:focus, .field select:focus {
|
||||
outline: none;
|
||||
border-color: var(--color-primary);
|
||||
box-shadow: 0 0 0 3px rgba(37, 99, 235, 0.2);
|
||||
}
|
||||
.helper { font-size: 0.75rem; color: var(--color-text-muted); }
|
||||
.mode-options {
|
||||
display: flex;
|
||||
flex-direction: column;
|
||||
gap: var(--space-3);
|
||||
}
|
||||
.hidden { display: none !important; }
|
||||
|
||||
.auto-policy {
|
||||
display: flex;
|
||||
flex-direction: column;
|
||||
gap: var(--space-3);
|
||||
padding: var(--space-3);
|
||||
border: 1px solid var(--color-border);
|
||||
border-radius: var(--radius-md);
|
||||
background: #f8fafc;
|
||||
}
|
||||
.auto-policy-kicker {
|
||||
display: inline-flex;
|
||||
width: fit-content;
|
||||
padding: 2px 6px;
|
||||
border-radius: 4px;
|
||||
background: #dbeafe;
|
||||
color: #1e40af;
|
||||
font-family: var(--font-mono);
|
||||
font-size: 0.6875rem;
|
||||
font-weight: 700;
|
||||
letter-spacing: 0;
|
||||
}
|
||||
.auto-policy-title {
|
||||
margin: var(--space-2) 0 0;
|
||||
font-size: 0.875rem;
|
||||
font-weight: 600;
|
||||
color: var(--color-text);
|
||||
}
|
||||
.auto-policy-grid {
|
||||
display: grid;
|
||||
grid-template-columns: 1fr 1fr;
|
||||
gap: var(--space-2);
|
||||
margin: 0;
|
||||
}
|
||||
.auto-policy-grid div {
|
||||
min-width: 0;
|
||||
padding: var(--space-2);
|
||||
border: 1px solid var(--color-border);
|
||||
border-radius: var(--radius-sm);
|
||||
background: var(--color-surface);
|
||||
}
|
||||
.auto-policy-grid dt {
|
||||
margin: 0;
|
||||
font-size: 0.6875rem;
|
||||
color: var(--color-text-muted);
|
||||
}
|
||||
.auto-policy-grid dd {
|
||||
margin: 2px 0 0;
|
||||
font-size: 0.8125rem;
|
||||
font-weight: 600;
|
||||
color: var(--color-text);
|
||||
word-break: break-word;
|
||||
}
|
||||
|
||||
/* Button */
|
||||
.btn {
|
||||
display: inline-flex;
|
||||
align-items: center;
|
||||
justify-content: center;
|
||||
gap: var(--space-2);
|
||||
min-height: 44px;
|
||||
padding: 0 var(--space-4);
|
||||
border: none;
|
||||
border-radius: var(--radius-sm);
|
||||
font-family: var(--font-body);
|
||||
font-size: 0.9375rem;
|
||||
font-weight: 600;
|
||||
cursor: pointer;
|
||||
transition: background var(--transition), opacity var(--transition), transform 80ms ease;
|
||||
}
|
||||
.btn:active:not(:disabled) { transform: scale(0.98); }
|
||||
.btn:disabled { opacity: 0.5; cursor: not-allowed; }
|
||||
.btn-primary { background: var(--color-primary); color: #fff; width: 100%; }
|
||||
.btn-primary:hover:not(:disabled) { background: var(--color-primary-hover); }
|
||||
.btn-primary:focus-visible { outline: none; box-shadow: 0 0 0 3px rgba(37, 99, 235, 0.4); }
|
||||
|
||||
.btn-spinner {
|
||||
width: 18px;
|
||||
height: 18px;
|
||||
border: 2px solid rgba(255,255,255,0.3);
|
||||
border-top-color: #fff;
|
||||
border-radius: 50%;
|
||||
animation: spin 0.7s linear infinite;
|
||||
}
|
||||
@keyframes spin { to { transform: rotate(360deg); } }
|
||||
|
||||
/* Stats */
|
||||
.stats-grid {
|
||||
display: grid;
|
||||
grid-template-columns: 1fr 1fr;
|
||||
gap: var(--space-3);
|
||||
margin: 0;
|
||||
}
|
||||
.stats-grid div {
|
||||
padding: var(--space-3);
|
||||
background: var(--color-bg);
|
||||
border-radius: var(--radius-sm);
|
||||
border: 1px solid var(--color-border);
|
||||
}
|
||||
.stats-grid dt { margin: 0; font-size: 0.75rem; color: var(--color-text-muted); }
|
||||
.stats-grid dd { margin: var(--space-1) 0 0; font-family: var(--font-heading); font-size: 1.125rem; font-weight: 600; }
|
||||
.mono { font-family: var(--font-mono); font-size: 0.75rem !important; word-break: break-all; }
|
||||
|
||||
/* History */
|
||||
.history-header {
|
||||
display: flex;
|
||||
align-items: center;
|
||||
justify-content: space-between;
|
||||
gap: var(--space-2);
|
||||
margin-bottom: var(--space-2);
|
||||
}
|
||||
.history-header h2 { margin: 0; }
|
||||
.btn-ghost {
|
||||
background: transparent;
|
||||
color: var(--color-text-muted);
|
||||
border: 1px solid var(--color-border);
|
||||
width: auto;
|
||||
min-height: 32px;
|
||||
padding: 0 var(--space-3);
|
||||
font-size: 0.8125rem;
|
||||
font-weight: 500;
|
||||
}
|
||||
.btn-ghost:hover:not(:disabled) {
|
||||
background: var(--color-bg);
|
||||
color: var(--color-text);
|
||||
border-color: var(--color-border-strong);
|
||||
}
|
||||
.btn-sm { min-height: 32px; }
|
||||
.history-hint {
|
||||
margin: 0 0 var(--space-2);
|
||||
font-size: 0.75rem;
|
||||
color: var(--color-text-muted);
|
||||
}
|
||||
.history-list {
|
||||
display: flex;
|
||||
flex-direction: column;
|
||||
gap: var(--space-2);
|
||||
max-height: 280px;
|
||||
overflow-y: auto;
|
||||
}
|
||||
.history-item {
|
||||
display: flex;
|
||||
align-items: stretch;
|
||||
gap: var(--space-1);
|
||||
width: 100%;
|
||||
padding: var(--space-1);
|
||||
border: 1px solid var(--color-border);
|
||||
border-radius: var(--radius-sm);
|
||||
background: var(--color-surface);
|
||||
color: var(--color-text);
|
||||
transition: border-color var(--transition), background var(--transition);
|
||||
}
|
||||
.history-item:hover {
|
||||
border-color: var(--color-chunk-border);
|
||||
background: var(--color-chunk-active);
|
||||
}
|
||||
.history-item.active {
|
||||
border-color: var(--color-primary);
|
||||
background: var(--color-chunk-active);
|
||||
box-shadow: inset 3px 0 0 var(--color-primary);
|
||||
}
|
||||
.history-item-load {
|
||||
flex: 1;
|
||||
min-width: 0;
|
||||
display: flex;
|
||||
flex-direction: column;
|
||||
align-items: flex-start;
|
||||
gap: 2px;
|
||||
padding: var(--space-2);
|
||||
border: 0;
|
||||
background: transparent;
|
||||
text-align: left;
|
||||
cursor: pointer;
|
||||
font-family: var(--font-body);
|
||||
color: inherit;
|
||||
}
|
||||
.history-item-delete {
|
||||
flex-shrink: 0;
|
||||
align-self: center;
|
||||
margin-right: var(--space-1);
|
||||
min-height: 28px;
|
||||
padding: 0 var(--space-2);
|
||||
border: 1px solid transparent;
|
||||
border-radius: var(--radius-sm);
|
||||
background: transparent;
|
||||
color: var(--color-text-muted);
|
||||
font-family: var(--font-body);
|
||||
font-size: 0.75rem;
|
||||
cursor: pointer;
|
||||
transition: color var(--transition), border-color var(--transition), background var(--transition);
|
||||
}
|
||||
.history-item-delete:hover {
|
||||
color: #b42318;
|
||||
border-color: #fecdca;
|
||||
background: #fef3f2;
|
||||
}
|
||||
.history-item-name {
|
||||
font-size: 0.8125rem;
|
||||
font-weight: 600;
|
||||
word-break: break-all;
|
||||
line-height: 1.35;
|
||||
}
|
||||
.history-item-meta {
|
||||
font-size: 0.6875rem;
|
||||
color: var(--color-text-muted);
|
||||
font-family: var(--font-mono);
|
||||
}
|
||||
|
||||
/* Workspace */
|
||||
.workspace {
|
||||
padding: var(--space-5);
|
||||
overflow-y: auto;
|
||||
max-height: calc(100dvh - var(--header-h));
|
||||
display: flex;
|
||||
flex-direction: column;
|
||||
gap: var(--space-4);
|
||||
min-height: 0;
|
||||
}
|
||||
|
||||
.workspace:has(#workspacePane:not(.hidden)) {
|
||||
overflow: hidden;
|
||||
}
|
||||
|
||||
.empty-state {
|
||||
flex: 1;
|
||||
display: flex;
|
||||
flex-direction: column;
|
||||
align-items: center;
|
||||
justify-content: center;
|
||||
text-align: center;
|
||||
padding: var(--space-6);
|
||||
color: var(--color-text-muted);
|
||||
}
|
||||
.empty-state svg { color: var(--color-border-strong); margin-bottom: var(--space-4); }
|
||||
.empty-state h2 { margin: 0 0 var(--space-2); font-family: var(--font-heading); color: var(--color-text); }
|
||||
.empty-state p { max-width: 420px; margin: 0; }
|
||||
|
||||
/* Workspace panes: original | chunk list | preview */
|
||||
.workspace-pane {
|
||||
display: grid;
|
||||
grid-template-columns: minmax(0, 1fr) minmax(0, 0.95fr) minmax(0, 1.15fr);
|
||||
gap: var(--space-4);
|
||||
flex: 1;
|
||||
min-height: 0;
|
||||
}
|
||||
|
||||
.pane {
|
||||
display: flex;
|
||||
flex-direction: column;
|
||||
background: var(--color-surface);
|
||||
border: 1px solid var(--color-border);
|
||||
border-radius: var(--radius-lg);
|
||||
box-shadow: var(--shadow-sm);
|
||||
overflow: hidden;
|
||||
min-height: 0;
|
||||
max-height: 100%;
|
||||
}
|
||||
|
||||
.pane-header {
|
||||
display: flex;
|
||||
align-items: center;
|
||||
justify-content: space-between;
|
||||
padding: var(--space-3) var(--space-4);
|
||||
border-bottom: 1px solid var(--color-border);
|
||||
background: var(--color-bg);
|
||||
}
|
||||
.pane-header h2 {
|
||||
margin: 0;
|
||||
font-family: var(--font-heading);
|
||||
font-size: 0.9375rem;
|
||||
font-weight: 600;
|
||||
}
|
||||
.pane-tag {
|
||||
font-size: 0.75rem;
|
||||
font-weight: 500;
|
||||
color: var(--color-text-muted);
|
||||
background: var(--color-surface);
|
||||
padding: 2px 8px;
|
||||
border-radius: 999px;
|
||||
border: 1px solid var(--color-border);
|
||||
}
|
||||
|
||||
.pane-body {
|
||||
flex: 1;
|
||||
overflow: auto;
|
||||
padding: var(--space-4);
|
||||
min-height: 0;
|
||||
}
|
||||
.placeholder { color: var(--color-text-muted); font-size: 0.9375rem; }
|
||||
|
||||
/* Original preview */
|
||||
.original-docx { font-size: 0.9375rem; line-height: 1.6; }
|
||||
.original-docx img { max-width: 100%; height: auto; border-radius: var(--radius-sm); }
|
||||
.original-pdf { width: 100%; height: 100%; min-height: 240px; border: none; }
|
||||
.original-text {
|
||||
font-family: var(--font-mono);
|
||||
font-size: 0.8125rem;
|
||||
white-space: pre-wrap;
|
||||
word-break: break-word;
|
||||
color: var(--color-text);
|
||||
}
|
||||
.original-image { max-width: 100%; border-radius: var(--radius-sm); }
|
||||
|
||||
/* Chunk list */
|
||||
.chunk-list { padding: var(--space-2); display: flex; flex-direction: column; gap: var(--space-2); }
|
||||
|
||||
.chunk-card {
|
||||
padding: var(--space-3);
|
||||
border: 1px solid var(--color-border);
|
||||
border-radius: var(--radius-md);
|
||||
background: var(--color-surface);
|
||||
cursor: pointer;
|
||||
transition: border-color var(--transition), background var(--transition), box-shadow var(--transition);
|
||||
text-align: left;
|
||||
width: 100%;
|
||||
font-family: inherit;
|
||||
}
|
||||
.chunk-card:hover {
|
||||
border-color: var(--color-chunk-border);
|
||||
background: #f8fafc;
|
||||
}
|
||||
.chunk-card:focus-visible {
|
||||
outline: none;
|
||||
box-shadow: 0 0 0 3px rgba(37, 99, 235, 0.25);
|
||||
}
|
||||
.chunk-card.active {
|
||||
border-color: var(--color-primary);
|
||||
background: var(--color-chunk-active);
|
||||
box-shadow: var(--shadow-sm);
|
||||
}
|
||||
|
||||
.chunk-card-header {
|
||||
display: flex;
|
||||
align-items: center;
|
||||
justify-content: space-between;
|
||||
gap: var(--space-2);
|
||||
margin-bottom: var(--space-2);
|
||||
}
|
||||
.chunk-index {
|
||||
font-family: var(--font-heading);
|
||||
font-weight: 600;
|
||||
font-size: 0.875rem;
|
||||
color: var(--color-primary);
|
||||
}
|
||||
.chunk-meta { font-size: 0.75rem; color: var(--color-text-muted); }
|
||||
|
||||
.chunk-types {
|
||||
display: flex;
|
||||
flex-wrap: wrap;
|
||||
gap: var(--space-1);
|
||||
margin-bottom: var(--space-2);
|
||||
}
|
||||
.type-tag {
|
||||
font-size: 0.6875rem;
|
||||
font-weight: 500;
|
||||
padding: 2px 6px;
|
||||
border-radius: 4px;
|
||||
background: #f1f5f9;
|
||||
color: var(--color-text-muted);
|
||||
text-transform: uppercase;
|
||||
letter-spacing: 0.03em;
|
||||
}
|
||||
.type-tag-heading { background: #dbeafe; color: #1e40af; }
|
||||
.type-tag-image { background: #fce7f3; color: #9d174d; }
|
||||
.type-tag-table { background: #d1fae5; color: #065f46; }
|
||||
.type-tag-preview-only { background: #fef3c7; color: #92400e; }
|
||||
|
||||
.chunk-snippet {
|
||||
font-size: 0.8125rem;
|
||||
color: var(--color-text-muted);
|
||||
line-height: 1.4;
|
||||
display: -webkit-box;
|
||||
-webkit-line-clamp: 3;
|
||||
-webkit-box-orient: vertical;
|
||||
overflow: hidden;
|
||||
}
|
||||
|
||||
/* Markdown preview (right pane) */
|
||||
.pane-preview .markdown-body {
|
||||
font-size: 0.9375rem;
|
||||
line-height: 1.65;
|
||||
max-width: 75ch;
|
||||
}
|
||||
.markdown-body h1, .markdown-body h2, .markdown-body h3 {
|
||||
font-family: var(--font-heading);
|
||||
margin: 1.25em 0 0.5em;
|
||||
line-height: 1.3;
|
||||
}
|
||||
.markdown-body h1 { font-size: 1.375rem; }
|
||||
.markdown-body h2 { font-size: 1.125rem; }
|
||||
.markdown-body h3 { font-size: 1rem; }
|
||||
.markdown-body p { margin: 0.75em 0; }
|
||||
.markdown-body img {
|
||||
max-width: 100%;
|
||||
height: auto;
|
||||
border-radius: var(--radius-sm);
|
||||
border: 1px solid var(--color-border);
|
||||
margin: var(--space-3) 0;
|
||||
}
|
||||
.markdown-body table {
|
||||
width: 100%;
|
||||
border-collapse: collapse;
|
||||
font-size: 0.875rem;
|
||||
margin: var(--space-3) 0;
|
||||
}
|
||||
.markdown-body th, .markdown-body td {
|
||||
border: 1px solid var(--color-border);
|
||||
padding: var(--space-2) var(--space-3);
|
||||
text-align: left;
|
||||
}
|
||||
.markdown-body th { background: var(--color-bg); font-weight: 600; }
|
||||
.markdown-body code {
|
||||
font-family: var(--font-mono);
|
||||
font-size: 0.85em;
|
||||
background: #f1f5f9;
|
||||
padding: 2px 6px;
|
||||
border-radius: 4px;
|
||||
}
|
||||
|
||||
/* Structured chunk blocks — images at original layout positions */
|
||||
.chunk-blocks {
|
||||
display: flex;
|
||||
flex-direction: column;
|
||||
gap: var(--space-3);
|
||||
}
|
||||
.chunk-block-image {
|
||||
margin: 0;
|
||||
padding: var(--space-3);
|
||||
background: #f8fafc;
|
||||
border: 1px solid var(--color-border);
|
||||
border-radius: var(--radius-md);
|
||||
}
|
||||
.chunk-block-image img {
|
||||
display: block;
|
||||
max-width: 100%;
|
||||
height: auto;
|
||||
border-radius: var(--radius-sm);
|
||||
border: 1px solid var(--color-border);
|
||||
margin: var(--space-2) 0;
|
||||
}
|
||||
.chunk-block-image .block-context {
|
||||
font-size: 0.8125rem;
|
||||
font-weight: 600;
|
||||
color: var(--color-primary);
|
||||
margin-bottom: var(--space-2);
|
||||
}
|
||||
.chunk-block-image .ocr-caption {
|
||||
font-size: 0.8125rem;
|
||||
color: var(--color-text-muted);
|
||||
margin-top: var(--space-2);
|
||||
line-height: 1.45;
|
||||
}
|
||||
.block-meta {
|
||||
font-family: var(--font-mono);
|
||||
font-size: 0.6875rem;
|
||||
color: var(--color-text-subtle);
|
||||
margin-top: var(--space-1);
|
||||
}
|
||||
.chunk-block-heading {
|
||||
margin: var(--space-2) 0 var(--space-1);
|
||||
font-family: var(--font-heading);
|
||||
}
|
||||
.chunk-block-paragraph p {
|
||||
margin: 0;
|
||||
line-height: 1.6;
|
||||
}
|
||||
.chunk-block-table {
|
||||
overflow-x: auto;
|
||||
padding: var(--space-3);
|
||||
background: #f8fafc;
|
||||
border: 1px solid var(--color-border);
|
||||
border-radius: var(--radius-md);
|
||||
}
|
||||
.chunk-block-table .table-screenshot {
|
||||
margin: 0 0 var(--space-3);
|
||||
}
|
||||
.chunk-block-table .table-screenshot img {
|
||||
display: block;
|
||||
max-width: 100%;
|
||||
height: auto;
|
||||
border-radius: var(--radius-sm);
|
||||
border: 1px solid var(--color-border);
|
||||
}
|
||||
.chunk-block-table .table-markdown {
|
||||
overflow-x: auto;
|
||||
}
|
||||
.chunk-block-table .table-footnote {
|
||||
margin-top: var(--space-2);
|
||||
font-size: 0.8125rem;
|
||||
color: var(--color-text-muted);
|
||||
}
|
||||
|
||||
.api-panel {
|
||||
background: var(--color-surface);
|
||||
border: 1px solid var(--color-border);
|
||||
border-radius: var(--radius-lg);
|
||||
padding: var(--space-4);
|
||||
}
|
||||
|
||||
.recall-panel {
|
||||
background: var(--color-surface);
|
||||
border: 1px solid var(--color-border);
|
||||
border-radius: var(--radius-lg);
|
||||
padding: var(--space-4);
|
||||
}
|
||||
.recall-panel summary {
|
||||
cursor: pointer;
|
||||
font-weight: 600;
|
||||
font-family: var(--font-heading);
|
||||
}
|
||||
.recall-form {
|
||||
display: grid;
|
||||
grid-template-columns: minmax(240px, 1fr) 100px 140px;
|
||||
align-items: end;
|
||||
gap: var(--space-3);
|
||||
margin-top: var(--space-4);
|
||||
}
|
||||
.recall-form .field span { font-size: 0.8125rem; font-weight: 500; }
|
||||
.recall-submit { width: auto; }
|
||||
.recall-hint { margin: var(--space-3) 0; font-size: 0.8125rem; color: var(--color-text-muted); }
|
||||
.recall-results { display: flex; flex-direction: column; gap: var(--space-2); }
|
||||
.recall-result {
|
||||
display: grid;
|
||||
grid-template-columns: 36px minmax(0, 1fr) 64px;
|
||||
gap: var(--space-3);
|
||||
align-items: start;
|
||||
width: 100%;
|
||||
padding: var(--space-3);
|
||||
border: 1px solid var(--color-border);
|
||||
border-radius: var(--radius-md);
|
||||
background: var(--color-surface);
|
||||
color: var(--color-text);
|
||||
text-align: left;
|
||||
cursor: pointer;
|
||||
}
|
||||
.recall-result:hover { border-color: var(--color-primary); background: #f8fafc; }
|
||||
.recall-result-main { display: flex; flex-direction: column; gap: var(--space-1); min-width: 0; }
|
||||
.recall-result-main span { color: var(--color-text-muted); font-size: 0.8125rem; line-height: 1.4; }
|
||||
.recall-rank, .recall-score { font-family: var(--font-mono); font-size: 0.75rem; color: var(--color-primary); }
|
||||
.recall-score { text-align: right; }
|
||||
.api-panel summary {
|
||||
cursor: pointer;
|
||||
font-weight: 600;
|
||||
font-family: var(--font-heading);
|
||||
padding: var(--space-1) 0;
|
||||
}
|
||||
.api-panel summary:focus-visible { outline: 2px solid var(--color-focus); outline-offset: 2px; }
|
||||
.api-grid {
|
||||
display: grid;
|
||||
grid-template-columns: 1fr 1fr;
|
||||
gap: var(--space-4);
|
||||
margin-top: var(--space-4);
|
||||
}
|
||||
.api-grid h3 { margin: 0 0 var(--space-2); font-size: 0.8125rem; color: var(--color-text-muted); text-transform: uppercase; }
|
||||
.code-block {
|
||||
margin: 0;
|
||||
padding: var(--space-3);
|
||||
background: #0f172a;
|
||||
color: #e2e8f0;
|
||||
border-radius: var(--radius-sm);
|
||||
font-family: var(--font-mono);
|
||||
font-size: 0.75rem;
|
||||
line-height: 1.5;
|
||||
overflow: auto;
|
||||
max-height: 280px;
|
||||
white-space: pre-wrap;
|
||||
word-break: break-word;
|
||||
}
|
||||
|
||||
/* Responsive */
|
||||
@media (max-width: 1024px) {
|
||||
.app-layout { grid-template-columns: 1fr; }
|
||||
.config-panel {
|
||||
max-height: none;
|
||||
border-right: none;
|
||||
border-bottom: 1px solid var(--color-border);
|
||||
}
|
||||
.workspace-pane { grid-template-columns: 1fr; height: auto; }
|
||||
.workspace-pane .pane { max-height: 420px; }
|
||||
.api-grid { grid-template-columns: 1fr; }
|
||||
}
|
||||
|
||||
@media (max-width: 768px) {
|
||||
.app-header { padding: 0 var(--space-4); }
|
||||
.workspace { padding: var(--space-4); }
|
||||
.field-row { grid-template-columns: 1fr; }
|
||||
.recall-form { grid-template-columns: 1fr; }
|
||||
}
|
||||
@@ -0,0 +1,268 @@
|
||||
<!DOCTYPE html>
|
||||
<html lang="zh-CN">
|
||||
<head>
|
||||
<meta charset="UTF-8" />
|
||||
<meta name="viewport" content="width=device-width, initial-scale=1" />
|
||||
<meta name="api-base" content="http://127.0.0.1:8000" />
|
||||
<title>RAG-cut — 文档切片演示</title>
|
||||
<link rel="preconnect" href="https://fonts.googleapis.com" />
|
||||
<link rel="preconnect" href="https://fonts.gstatic.com" crossorigin />
|
||||
<link href="https://fonts.googleapis.com/css2?family=DM+Sans:wght@400;500;600;700&family=Space+Grotesk:wght@500;600;700&family=JetBrains+Mono:wght@400;500&display=swap" rel="stylesheet" />
|
||||
<link rel="stylesheet" href="/css/styles.css" />
|
||||
<script src="https://cdn.jsdelivr.net/npm/marked@15.0.12/marked.min.js"></script>
|
||||
<script src="https://cdn.jsdelivr.net/npm/mammoth@1.8.0/mammoth.browser.min.js"></script>
|
||||
</head>
|
||||
<body>
|
||||
<a class="skip-link" href="#main-content">跳到主要内容</a>
|
||||
|
||||
<header class="app-header">
|
||||
<div class="brand">
|
||||
<svg class="brand-icon" width="28" height="28" viewBox="0 0 24 24" fill="none" stroke="currentColor" stroke-width="2" aria-hidden="true">
|
||||
<path d="M14.5 2H6a2 2 0 0 0-2 2v16a2 2 0 0 0 2 2h12a2 2 0 0 0 2-2V7.5L14.5 2z"/>
|
||||
<polyline points="14 2 14 8 20 8"/>
|
||||
<line x1="8" y1="13" x2="16" y2="13"/>
|
||||
<line x1="8" y1="17" x2="13" y2="17"/>
|
||||
</svg>
|
||||
<div>
|
||||
<h1>RAG-cut</h1>
|
||||
<p class="brand-sub">AI 知识库 · 文档切片演示</p>
|
||||
</div>
|
||||
</div>
|
||||
<div class="header-meta" id="statusBadge" aria-live="polite">
|
||||
<span class="badge badge-idle">等待上传</span>
|
||||
</div>
|
||||
</header>
|
||||
|
||||
<div class="app-layout">
|
||||
<aside class="config-panel" aria-label="切分配置">
|
||||
<section class="panel-section">
|
||||
<h2>上传文档</h2>
|
||||
<div
|
||||
class="dropzone"
|
||||
id="dropzone"
|
||||
tabindex="0"
|
||||
role="button"
|
||||
aria-label="点击或拖拽上传文档"
|
||||
>
|
||||
<svg width="32" height="32" viewBox="0 0 24 24" fill="none" stroke="currentColor" stroke-width="1.5" aria-hidden="true">
|
||||
<path d="M21 15v4a2 2 0 0 1-2 2H5a2 2 0 0 1-2-2v-4"/>
|
||||
<polyline points="17 8 12 3 7 8"/>
|
||||
<line x1="12" y1="3" x2="12" y2="15"/>
|
||||
</svg>
|
||||
<p class="dropzone-title">拖拽文件到此处</p>
|
||||
<p class="dropzone-hint">或点击选择 · pdf docx ppt pptx xlsx md txt 等</p>
|
||||
<p class="dropzone-file" id="fileName"></p>
|
||||
</div>
|
||||
<input type="file" id="fileInput" class="sr-only" accept=".pdf,.doc,.docx,.ppt,.pptx,.ppsx,.xlsx,.xls,.csv,.md,.txt,.html,.json,.xml,.log,.jpg,.jpeg,.png,.bmp,.gif" />
|
||||
</section>
|
||||
|
||||
<section class="panel-section">
|
||||
<h2>切分设置</h2>
|
||||
<form id="configForm" class="config-form" novalidate>
|
||||
<div class="field">
|
||||
<label for="splitMode">切分模式</label>
|
||||
<select id="splitMode" name="mode">
|
||||
<option value="default" selected>默认切分(结构感知)</option>
|
||||
<option value="delimiter">通用标识符切分</option>
|
||||
<option value="parent_child">父子标识符切分</option>
|
||||
<option value="by_row">按行切分(表格)</option>
|
||||
</select>
|
||||
<p class="helper" id="modeHint">按标题/结构切分,适合 PDF、Word、PPT 等</p>
|
||||
</div>
|
||||
|
||||
<div class="mode-options" id="modeOptionsDefault">
|
||||
<div class="field-row">
|
||||
<div class="field">
|
||||
<label for="maxChunkSize">最大长度</label>
|
||||
<input type="number" id="maxChunkSize" name="max_chunk_size" min="200" max="8000" step="100" value="2200" />
|
||||
</div>
|
||||
<div class="field">
|
||||
<label for="overlap">重叠长度</label>
|
||||
<input type="number" id="overlap" name="overlap" min="0" max="2000" step="10" value="120" />
|
||||
</div>
|
||||
</div>
|
||||
</div>
|
||||
|
||||
<div class="mode-options hidden" id="modeOptionsDelimiter">
|
||||
<div class="field">
|
||||
<label for="delimiter">标识符</label>
|
||||
<input type="text" id="delimiter" name="delimiter" value="###" placeholder="例如 ### 或 \\n\\n" />
|
||||
<p class="helper">按该标识符切开;标识符本身不会写入切片</p>
|
||||
</div>
|
||||
<div class="field-row">
|
||||
<div class="field">
|
||||
<label for="delimiterMaxSize">最大长度</label>
|
||||
<input type="number" id="delimiterMaxSize" name="delimiter_max_chunk_size" min="200" max="8000" step="100" value="1500" />
|
||||
</div>
|
||||
<div class="field">
|
||||
<label for="delimiterOverlap">重叠长度</label>
|
||||
<input type="number" id="delimiterOverlap" name="delimiter_overlap" min="0" max="2000" step="10" value="150" />
|
||||
</div>
|
||||
</div>
|
||||
</div>
|
||||
|
||||
<div class="mode-options hidden" id="modeOptionsParentChild">
|
||||
<div class="field">
|
||||
<label for="parentDelimiter">父级标识符</label>
|
||||
<input type="text" id="parentDelimiter" name="parent_delimiter" value="##" placeholder="例如 ##" />
|
||||
</div>
|
||||
<div class="field">
|
||||
<label for="childDelimiter">子级标识符</label>
|
||||
<input type="text" id="childDelimiter" name="child_delimiter" value="###" placeholder="例如 ### 或 \\n\\n" />
|
||||
<p class="helper">先按父标识符切父片,再按子标识符切子片;检索用子片,父片作上下文</p>
|
||||
</div>
|
||||
<div class="field-row">
|
||||
<div class="field">
|
||||
<label for="parentMaxSize">父级最大长度</label>
|
||||
<input type="number" id="parentMaxSize" name="parent_max_chunk_size" min="200" max="8000" step="100" value="2000" />
|
||||
</div>
|
||||
<div class="field">
|
||||
<label for="childMaxSize">子级最大长度</label>
|
||||
<input type="number" id="childMaxSize" name="child_max_size" min="50" max="1500" step="50" value="512" />
|
||||
</div>
|
||||
</div>
|
||||
<div class="field">
|
||||
<label for="parentChildOverlap">重叠长度</label>
|
||||
<input type="number" id="parentChildOverlap" name="parent_child_overlap" min="0" max="2000" step="10" value="80" />
|
||||
</div>
|
||||
</div>
|
||||
|
||||
<div class="mode-options hidden" id="modeOptionsByRow">
|
||||
<div class="field-row">
|
||||
<div class="field">
|
||||
<label for="headerRowStart">表头起始行</label>
|
||||
<input type="number" id="headerRowStart" name="header_row_start" min="1" value="1" />
|
||||
</div>
|
||||
<div class="field">
|
||||
<label for="headerRowEnd">表头结束行</label>
|
||||
<input type="number" id="headerRowEnd" name="header_row_end" min="1" value="1" />
|
||||
</div>
|
||||
</div>
|
||||
<div class="field-row">
|
||||
<div class="field">
|
||||
<label for="startRow">数据起始行</label>
|
||||
<input type="number" id="startRow" name="start_row" min="1" value="2" />
|
||||
</div>
|
||||
<div class="field">
|
||||
<label for="rowsPerChunk">每片行数</label>
|
||||
<input type="number" id="rowsPerChunk" name="rows_per_chunk" min="1" max="500" value="10" />
|
||||
</div>
|
||||
</div>
|
||||
</div>
|
||||
|
||||
<div class="auto-policy" id="autoPolicy">
|
||||
<div>
|
||||
<span class="auto-policy-kicker" id="policyKicker">AUTO</span>
|
||||
<p class="auto-policy-title" id="policyTitle">系统根据上传文档自动选择切分参数</p>
|
||||
</div>
|
||||
<dl class="auto-policy-grid" id="autoPolicyGrid">
|
||||
<div><dt>模式</dt><dd>待上传后判断</dd></div>
|
||||
<div><dt>长度</dt><dd>自动</dd></div>
|
||||
<div><dt>重叠</dt><dd>自动</dd></div>
|
||||
<div><dt>策略</dt><dd>自动判断</dd></div>
|
||||
</dl>
|
||||
</div>
|
||||
|
||||
<button type="submit" class="btn btn-primary" id="submitBtn" disabled title="请先上传文档">
|
||||
<span class="btn-label">开始切分</span>
|
||||
<span class="btn-spinner hidden" aria-hidden="true"></span>
|
||||
</button>
|
||||
</form>
|
||||
</section>
|
||||
|
||||
<section class="panel-section history-section" aria-label="历史切片">
|
||||
<div class="history-header">
|
||||
<h2>历史切片</h2>
|
||||
<button type="button" class="btn btn-ghost btn-sm" id="historyRefreshBtn" title="刷新列表">刷新</button>
|
||||
</div>
|
||||
<p class="history-hint" id="historyHint">加载中…</p>
|
||||
<div class="history-list" id="historyList" role="listbox" aria-label="历史切片列表"></div>
|
||||
</section>
|
||||
|
||||
<section class="panel-section stats-section hidden" id="statsSection">
|
||||
<h2>切分概览</h2>
|
||||
<dl class="stats-grid">
|
||||
<div><dt>Blocks</dt><dd id="statBlocks">—</dd></div>
|
||||
<div><dt>Chunks</dt><dd id="statChunks">—</dd></div>
|
||||
<div><dt>模式</dt><dd id="statMode">—</dd></div>
|
||||
<div><dt>Doc ID</dt><dd id="statDocId" class="mono">—</dd></div>
|
||||
</dl>
|
||||
</section>
|
||||
</aside>
|
||||
|
||||
<main class="workspace" id="main-content">
|
||||
<div class="empty-state" id="emptyState">
|
||||
<svg width="64" height="64" viewBox="0 0 24 24" fill="none" stroke="currentColor" stroke-width="1" aria-hidden="true">
|
||||
<rect x="3" y="3" width="18" height="18" rx="2"/>
|
||||
<path d="M3 9h18M9 21V9"/>
|
||||
</svg>
|
||||
<h2>上传文档查看切片效果</h2>
|
||||
<p>支持 Word / PDF / Excel / Markdown 等格式。左侧原文、中间切片列表、右侧切片预览。</p>
|
||||
</div>
|
||||
|
||||
<div class="workspace-pane hidden" id="workspacePane">
|
||||
<section class="pane pane-original" aria-label="原文预览">
|
||||
<div class="pane-header">
|
||||
<h2>查看原文</h2>
|
||||
<span class="pane-tag" id="originalTag"></span>
|
||||
</div>
|
||||
<div class="pane-body" id="originalPreview">
|
||||
<p class="placeholder">原文加载中…</p>
|
||||
</div>
|
||||
</section>
|
||||
|
||||
<section class="pane pane-chunks" aria-label="切片列表">
|
||||
<div class="pane-header">
|
||||
<h2>管理切片</h2>
|
||||
<span class="pane-tag" id="chunkCountTag"></span>
|
||||
</div>
|
||||
<div class="pane-body chunk-list" id="chunkList" role="listbox" aria-label="切片列表"></div>
|
||||
</section>
|
||||
|
||||
<section class="pane pane-preview" id="previewPanel" aria-label="选中切片预览">
|
||||
<div class="pane-header">
|
||||
<h2>切片预览</h2>
|
||||
<span class="pane-tag" id="selectedChunkTag">未选择</span>
|
||||
</div>
|
||||
<div class="pane-body markdown-body" id="chunkPreview">
|
||||
<p class="placeholder">点击中间列表中的切片查看 Markdown 渲染结果</p>
|
||||
</div>
|
||||
</section>
|
||||
</div>
|
||||
|
||||
<details class="recall-panel hidden" id="recallPanel">
|
||||
<summary>召回测试</summary>
|
||||
<form class="recall-form" id="recallForm">
|
||||
<label class="field recall-query">
|
||||
<span>查询内容</span>
|
||||
<input id="recallQuery" type="search" maxlength="500" placeholder="输入要检索的问题或关键词" required />
|
||||
</label>
|
||||
<label class="field recall-top-k">
|
||||
<span>Top K</span>
|
||||
<input id="recallTopK" type="number" min="1" max="20" value="5" required />
|
||||
</label>
|
||||
<button class="btn btn-primary recall-submit" id="recallSubmit" type="submit">开始召回</button>
|
||||
</form>
|
||||
<p class="recall-hint" id="recallHint">仅检索有语义价值的切片,“仅展示”切片不会进入候选集。</p>
|
||||
<div class="recall-results" id="recallResults"></div>
|
||||
</details>
|
||||
|
||||
<details class="api-panel hidden" id="apiPanel">
|
||||
<summary>API 请求 / 响应</summary>
|
||||
<div class="api-grid">
|
||||
<div>
|
||||
<h3>Request</h3>
|
||||
<pre id="apiRequest" class="code-block"></pre>
|
||||
</div>
|
||||
<div>
|
||||
<h3>Response</h3>
|
||||
<pre id="apiResponse" class="code-block"></pre>
|
||||
</div>
|
||||
</div>
|
||||
</details>
|
||||
</main>
|
||||
</div>
|
||||
|
||||
<script src="/js/app.js"></script>
|
||||
</body>
|
||||
</html>
|
||||
@@ -0,0 +1,957 @@
|
||||
/**
|
||||
* RAG-cut Demo Frontend
|
||||
*/
|
||||
|
||||
const API_BASE = (() => {
|
||||
const meta = document.querySelector('meta[name="api-base"]')?.content?.trim();
|
||||
if (meta) return meta.replace(/\/$/, "");
|
||||
if (window.location.port && window.location.port !== "8000") {
|
||||
return "http://127.0.0.1:8000";
|
||||
}
|
||||
return "";
|
||||
})();
|
||||
|
||||
function apiUrl(path) {
|
||||
return `${API_BASE}${path}`;
|
||||
}
|
||||
|
||||
const $ = (sel) => document.querySelector(sel);
|
||||
const $$ = (sel) => document.querySelectorAll(sel);
|
||||
|
||||
const state = {
|
||||
file: null,
|
||||
result: null,
|
||||
selectedIndex: 0,
|
||||
objectUrl: null,
|
||||
history: [],
|
||||
activeHistoryId: null,
|
||||
};
|
||||
|
||||
const els = {
|
||||
dropzone: $("#dropzone"),
|
||||
fileInput: $("#fileInput"),
|
||||
fileName: $("#fileName"),
|
||||
configForm: $("#configForm"),
|
||||
submitBtn: $("#submitBtn"),
|
||||
splitMode: $("#splitMode"),
|
||||
modeHint: $("#modeHint"),
|
||||
modeOptionsDefault: $("#modeOptionsDefault"),
|
||||
modeOptionsDelimiter: $("#modeOptionsDelimiter"),
|
||||
modeOptionsParentChild: $("#modeOptionsParentChild"),
|
||||
modeOptionsByRow: $("#modeOptionsByRow"),
|
||||
maxChunkSize: $("#maxChunkSize"),
|
||||
overlap: $("#overlap"),
|
||||
delimiter: $("#delimiter"),
|
||||
delimiterMaxSize: $("#delimiterMaxSize"),
|
||||
delimiterOverlap: $("#delimiterOverlap"),
|
||||
parentDelimiter: $("#parentDelimiter"),
|
||||
childDelimiter: $("#childDelimiter"),
|
||||
parentMaxSize: $("#parentMaxSize"),
|
||||
childMaxSize: $("#childMaxSize"),
|
||||
parentChildOverlap: $("#parentChildOverlap"),
|
||||
headerRowStart: $("#headerRowStart"),
|
||||
headerRowEnd: $("#headerRowEnd"),
|
||||
startRow: $("#startRow"),
|
||||
rowsPerChunk: $("#rowsPerChunk"),
|
||||
autoPolicy: $("#autoPolicy"),
|
||||
policyKicker: $("#policyKicker"),
|
||||
policyTitle: $("#policyTitle"),
|
||||
autoPolicyGrid: $("#autoPolicyGrid"),
|
||||
statusBadge: $("#statusBadge"),
|
||||
emptyState: $("#emptyState"),
|
||||
dualPane: $("#workspacePane"),
|
||||
previewPanel: $("#previewPanel"),
|
||||
apiPanel: $("#apiPanel"),
|
||||
recallPanel: $("#recallPanel"),
|
||||
recallForm: $("#recallForm"),
|
||||
recallQuery: $("#recallQuery"),
|
||||
recallTopK: $("#recallTopK"),
|
||||
recallSubmit: $("#recallSubmit"),
|
||||
recallHint: $("#recallHint"),
|
||||
recallResults: $("#recallResults"),
|
||||
statsSection: $("#statsSection"),
|
||||
historyList: $("#historyList"),
|
||||
historyHint: $("#historyHint"),
|
||||
historyRefreshBtn: $("#historyRefreshBtn"),
|
||||
originalPreview: $("#originalPreview"),
|
||||
chunkList: $("#chunkList"),
|
||||
chunkPreview: $("#chunkPreview"),
|
||||
originalTag: $("#originalTag"),
|
||||
chunkCountTag: $("#chunkCountTag"),
|
||||
selectedChunkTag: $("#selectedChunkTag"),
|
||||
statBlocks: $("#statBlocks"),
|
||||
statChunks: $("#statChunks"),
|
||||
statMode: $("#statMode"),
|
||||
statDocId: $("#statDocId"),
|
||||
apiRequest: $("#apiRequest"),
|
||||
apiResponse: $("#apiResponse"),
|
||||
};
|
||||
|
||||
function setStatus(type, text) {
|
||||
els.statusBadge.innerHTML = `<span class="badge badge-${type}">${text}</span>`;
|
||||
}
|
||||
|
||||
function setFile(file) {
|
||||
if (state.objectUrl) {
|
||||
URL.revokeObjectURL(state.objectUrl);
|
||||
state.objectUrl = null;
|
||||
}
|
||||
state.file = file;
|
||||
state.result = null;
|
||||
state.activeHistoryId = null;
|
||||
els.fileName.textContent = file ? file.name : "";
|
||||
els.submitBtn.disabled = !file;
|
||||
els.submitBtn.title = file ? "开始切分已选文件" : "请先上传文档";
|
||||
highlightHistoryActive();
|
||||
if (file) setStatus("idle", "已选择文件");
|
||||
else setStatus("idle", "等待上传");
|
||||
}
|
||||
|
||||
function formatSavedAt(iso) {
|
||||
if (!iso) return "";
|
||||
try {
|
||||
const d = new Date(iso);
|
||||
if (Number.isNaN(d.getTime())) return "";
|
||||
return d.toLocaleString("zh-CN", { hour12: false });
|
||||
} catch {
|
||||
return "";
|
||||
}
|
||||
}
|
||||
|
||||
function highlightHistoryActive() {
|
||||
if (!els.historyList) return;
|
||||
els.historyList.querySelectorAll(".history-item").forEach((row) => {
|
||||
const active = row.dataset.docId === state.activeHistoryId;
|
||||
row.classList.toggle("active", active);
|
||||
row.setAttribute("aria-selected", active ? "true" : "false");
|
||||
});
|
||||
}
|
||||
|
||||
function clearWorkspace() {
|
||||
state.result = null;
|
||||
state.selectedIndex = 0;
|
||||
state.activeHistoryId = null;
|
||||
if (state.objectUrl) {
|
||||
URL.revokeObjectURL(state.objectUrl);
|
||||
state.objectUrl = null;
|
||||
}
|
||||
els.emptyState?.classList.remove("hidden");
|
||||
els.dualPane?.classList.add("hidden");
|
||||
els.apiPanel?.classList.add("hidden");
|
||||
els.recallPanel?.classList.add("hidden");
|
||||
els.statsSection?.classList.add("hidden");
|
||||
if (els.originalPreview) els.originalPreview.innerHTML = "";
|
||||
if (els.chunkList) els.chunkList.innerHTML = "";
|
||||
if (els.chunkPreview) els.chunkPreview.innerHTML = "";
|
||||
if (els.apiRequest) els.apiRequest.textContent = "";
|
||||
if (els.apiResponse) els.apiResponse.textContent = "";
|
||||
if (els.recallResults) els.recallResults.innerHTML = "";
|
||||
highlightHistoryActive();
|
||||
setStatus("idle", "等待上传");
|
||||
}
|
||||
|
||||
function renderHistoryList(items) {
|
||||
state.history = items || [];
|
||||
if (!els.historyList) return;
|
||||
|
||||
if (!state.history.length) {
|
||||
els.historyHint.textContent = "暂无历史记录,上传并切分后会出现在这里";
|
||||
els.historyList.innerHTML = "";
|
||||
return;
|
||||
}
|
||||
|
||||
els.historyHint.textContent = `共 ${state.history.length} 条 · 点击加载`;
|
||||
els.historyList.innerHTML = state.history.map((item) => {
|
||||
const when = formatSavedAt(item.saved_at);
|
||||
const orig = item.has_original ? "" : " · 无原文";
|
||||
const active = item.doc_id === state.activeHistoryId;
|
||||
return `
|
||||
<div class="history-item${active ? " active" : ""}" role="option"
|
||||
data-doc-id="${escapeHtml(item.doc_id)}"
|
||||
aria-selected="${active ? "true" : "false"}">
|
||||
<button type="button" class="history-item-load" data-doc-id="${escapeHtml(item.doc_id)}" title="加载此切片结果">
|
||||
<span class="history-item-name">${escapeHtml(item.filename || item.doc_id)}</span>
|
||||
<span class="history-item-meta">${item.chunk_count || 0} 片 · ${escapeHtml(item.split_mode || "—")}${when ? ` · ${escapeHtml(when)}` : ""}${orig}</span>
|
||||
</button>
|
||||
<button type="button" class="history-item-delete" data-doc-id="${escapeHtml(item.doc_id)}"
|
||||
title="删除此历史记录" aria-label="删除 ${escapeHtml(item.filename || item.doc_id)}">删除</button>
|
||||
</div>
|
||||
`;
|
||||
}).join("");
|
||||
|
||||
els.historyList.querySelectorAll(".history-item-load").forEach((btn) => {
|
||||
btn.addEventListener("click", () => loadHistoryResult(btn.dataset.docId));
|
||||
});
|
||||
els.historyList.querySelectorAll(".history-item-delete").forEach((btn) => {
|
||||
btn.addEventListener("click", (e) => {
|
||||
e.stopPropagation();
|
||||
deleteHistoryResult(btn.dataset.docId);
|
||||
});
|
||||
});
|
||||
}
|
||||
|
||||
async function deleteHistoryResult(docId) {
|
||||
if (!docId) return;
|
||||
const item = state.history.find((h) => h.doc_id === docId);
|
||||
const label = item?.filename || docId;
|
||||
if (!confirm(`确定删除「${label}」?\n将同时删除切片结果、上传原文与资源文件。`)) {
|
||||
return;
|
||||
}
|
||||
|
||||
setStatus("loading", "删除历史…");
|
||||
try {
|
||||
const res = await fetch(apiUrl(`/api/results/${docId}`), { method: "DELETE" });
|
||||
const text = await res.text();
|
||||
let data = null;
|
||||
try {
|
||||
data = text ? JSON.parse(text) : null;
|
||||
} catch {
|
||||
data = null;
|
||||
}
|
||||
if (!res.ok) {
|
||||
const detail = data?.detail;
|
||||
const msg = typeof detail === "string" ? detail : (detail ? JSON.stringify(detail) : `HTTP ${res.status}`);
|
||||
throw new Error(msg);
|
||||
}
|
||||
if (state.activeHistoryId === docId) {
|
||||
clearWorkspace();
|
||||
}
|
||||
await refreshHistory();
|
||||
setStatus("success", `已删除 · ${label}`);
|
||||
} catch (err) {
|
||||
setStatus("error", "删除失败");
|
||||
alert(`删除失败:${err.message || err}`);
|
||||
}
|
||||
}
|
||||
|
||||
async function refreshHistory() {
|
||||
if (!els.historyHint) return;
|
||||
els.historyHint.textContent = "加载中…";
|
||||
const controller = new AbortController();
|
||||
const timer = setTimeout(() => controller.abort(), 30000);
|
||||
try {
|
||||
const res = await fetch(apiUrl("/api/results"), { signal: controller.signal });
|
||||
const text = await res.text();
|
||||
let data = null;
|
||||
try {
|
||||
data = text ? JSON.parse(text) : null;
|
||||
} catch {
|
||||
throw new Error(res.ok ? "响应不是 JSON" : `HTTP ${res.status}`);
|
||||
}
|
||||
if (!res.ok) {
|
||||
const detail = data?.detail;
|
||||
const msg = typeof detail === "string" ? detail : (detail ? JSON.stringify(detail) : `HTTP ${res.status}`);
|
||||
if (res.status === 404) {
|
||||
throw new Error("接口不存在,请重启后端(backend: python run.py)");
|
||||
}
|
||||
throw new Error(msg);
|
||||
}
|
||||
renderHistoryList(data.results || []);
|
||||
} catch (err) {
|
||||
const message =
|
||||
err?.name === "AbortError"
|
||||
? "请求超时,请确认后端已启动在 :8000"
|
||||
: (err.message || String(err));
|
||||
els.historyHint.textContent = `历史加载失败:${message}`;
|
||||
} finally {
|
||||
clearTimeout(timer);
|
||||
}
|
||||
}
|
||||
|
||||
async function renderOriginalFromHistory(docId, filename, hasOriginal) {
|
||||
if (!hasOriginal) {
|
||||
els.originalTag.textContent = filename || docId;
|
||||
els.originalPreview.innerHTML =
|
||||
'<p class="placeholder">历史记录中未找到原文文件(可能已被清理)。仍可查看右侧切片结果。</p>';
|
||||
return;
|
||||
}
|
||||
|
||||
els.originalPreview.innerHTML = '<p class="placeholder">原文加载中…</p>';
|
||||
try {
|
||||
const res = await fetch(apiUrl(`/api/results/${docId}/original`));
|
||||
if (!res.ok) {
|
||||
const data = await res.json().catch(() => ({}));
|
||||
throw new Error(data.detail || `HTTP ${res.status}`);
|
||||
}
|
||||
const blob = await res.blob();
|
||||
const name = filename || "document";
|
||||
const file = new File([blob], name, { type: blob.type || "application/octet-stream" });
|
||||
state.file = file;
|
||||
els.fileName.textContent = name;
|
||||
els.submitBtn.disabled = false;
|
||||
await renderOriginalPreview(file, docId);
|
||||
} catch (err) {
|
||||
els.originalTag.textContent = filename || docId;
|
||||
els.originalPreview.innerHTML =
|
||||
`<p class="placeholder">原文预览失败:${escapeHtml(err.message || String(err))}。仍可查看切片结果。</p>`;
|
||||
}
|
||||
}
|
||||
|
||||
async function loadHistoryResult(docId) {
|
||||
if (!docId) return;
|
||||
setStatus("loading", "加载历史…");
|
||||
els.apiRequest.textContent = JSON.stringify(
|
||||
{ method: "GET", url: apiUrl(`/api/results/${docId}`) },
|
||||
null,
|
||||
2,
|
||||
);
|
||||
try {
|
||||
const res = await fetch(apiUrl(`/api/results/${docId}`));
|
||||
const data = await res.json();
|
||||
if (!res.ok) throw new Error(data.detail || `HTTP ${res.status}`);
|
||||
|
||||
state.activeHistoryId = docId;
|
||||
highlightHistoryActive();
|
||||
els.apiResponse.textContent = JSON.stringify(
|
||||
{ doc_id: data.doc_id, filename: data.filename, chunk_count: data.chunk_count, split_mode: data.split_mode },
|
||||
null,
|
||||
2,
|
||||
);
|
||||
showResult(data);
|
||||
setStatus("success", `已加载历史 · ${data.chunk_count} 片`);
|
||||
await renderOriginalFromHistory(docId, data.filename, data.has_original);
|
||||
} catch (err) {
|
||||
setStatus("error", "加载失败");
|
||||
els.apiResponse.textContent = JSON.stringify({ error: err.message || String(err) }, null, 2);
|
||||
alert(`加载历史失败:${err.message || err}`);
|
||||
}
|
||||
}
|
||||
|
||||
function buildFormData() {
|
||||
const fd = new FormData();
|
||||
fd.append("file", state.file);
|
||||
const fields = collectSplitFields();
|
||||
Object.entries(fields).forEach(([key, value]) => {
|
||||
if (value != null && value !== "") fd.append(key, String(value));
|
||||
});
|
||||
return fd;
|
||||
}
|
||||
|
||||
function unescapeDelimiter(raw) {
|
||||
return String(raw || "")
|
||||
.replace(/\\n/g, "\n")
|
||||
.replace(/\\t/g, "\t")
|
||||
.replace(/\\r/g, "\r");
|
||||
}
|
||||
|
||||
function collectSplitFields() {
|
||||
const mode = els.splitMode?.value || "default";
|
||||
|
||||
if (mode === "default") {
|
||||
return {
|
||||
mode: "default",
|
||||
max_chunk_size: Number(els.maxChunkSize?.value || 2200),
|
||||
overlap: Number(els.overlap?.value || 0),
|
||||
};
|
||||
}
|
||||
|
||||
if (mode === "delimiter") {
|
||||
const delimiter = unescapeDelimiter(els.delimiter?.value?.trim());
|
||||
return {
|
||||
mode: "delimiter",
|
||||
delimiter: delimiter || "###",
|
||||
max_chunk_size: Number(els.delimiterMaxSize?.value || 1500),
|
||||
overlap: Number(els.delimiterOverlap?.value || 0),
|
||||
};
|
||||
}
|
||||
|
||||
if (mode === "parent_child") {
|
||||
const parentDelimiter = unescapeDelimiter(els.parentDelimiter?.value?.trim());
|
||||
const childDelimiter = unescapeDelimiter(els.childDelimiter?.value?.trim());
|
||||
return {
|
||||
mode: "parent_child",
|
||||
parent_delimiter: parentDelimiter || "##",
|
||||
child_delimiter: childDelimiter || "",
|
||||
max_chunk_size: Number(els.parentMaxSize?.value || 2000),
|
||||
child_max_size: Number(els.childMaxSize?.value || 512),
|
||||
overlap: Number(els.parentChildOverlap?.value || 0),
|
||||
};
|
||||
}
|
||||
|
||||
if (mode === "by_row") {
|
||||
return {
|
||||
mode: "by_row",
|
||||
header_row_start: Number(els.headerRowStart?.value || 1),
|
||||
header_row_end: Number(els.headerRowEnd?.value || 1),
|
||||
start_row: Number(els.startRow?.value || 2),
|
||||
rows_per_chunk: Number(els.rowsPerChunk?.value || 10),
|
||||
max_chunk_size: 2400,
|
||||
overlap: 0,
|
||||
};
|
||||
}
|
||||
|
||||
return {};
|
||||
}
|
||||
|
||||
function buildRequestPreview() {
|
||||
const fields = {
|
||||
file: state.file?.name,
|
||||
...collectSplitFields(),
|
||||
};
|
||||
return {
|
||||
method: "POST",
|
||||
url: apiUrl("/api/chunk"),
|
||||
contentType: "multipart/form-data",
|
||||
fields,
|
||||
};
|
||||
}
|
||||
|
||||
const MODE_HINTS = {
|
||||
default: "按标题/结构切分,适合 PDF、Word、PPT 等",
|
||||
delimiter: "按自定义标识符切开,适合 Markdown/带固定分隔符的文本",
|
||||
parent_child: "先按父标识符切父片,再按子标识符切子片;检索用子片、父片作上下文",
|
||||
by_row: "按表格行切分,适合 xlsx / xls / csv",
|
||||
};
|
||||
|
||||
function syncModeOptions() {
|
||||
const mode = els.splitMode?.value || "default";
|
||||
els.modeOptionsDefault?.classList.toggle("hidden", mode !== "default");
|
||||
els.modeOptionsDelimiter?.classList.toggle("hidden", mode !== "delimiter");
|
||||
els.modeOptionsParentChild?.classList.toggle("hidden", mode !== "parent_child");
|
||||
els.modeOptionsByRow?.classList.toggle("hidden", mode !== "by_row");
|
||||
if (els.modeHint) els.modeHint.textContent = MODE_HINTS[mode] || MODE_HINTS.default;
|
||||
|
||||
// CSS-hidden fields still join HTML5 constraint validation and can silently
|
||||
// block <form> submit with no JS callback. Disable inactive panels' controls.
|
||||
[
|
||||
[els.modeOptionsDefault, mode === "default"],
|
||||
[els.modeOptionsDelimiter, mode === "delimiter"],
|
||||
[els.modeOptionsParentChild, mode === "parent_child"],
|
||||
[els.modeOptionsByRow, mode === "by_row"],
|
||||
].forEach(([panel, active]) => {
|
||||
panel?.querySelectorAll("input, select, textarea").forEach((input) => {
|
||||
input.disabled = !active;
|
||||
});
|
||||
});
|
||||
|
||||
if (els.policyKicker) {
|
||||
els.policyKicker.textContent = "MANUAL";
|
||||
}
|
||||
if (els.policyTitle) {
|
||||
els.policyTitle.textContent = "将使用上方手动选择的切分模式与参数";
|
||||
}
|
||||
|
||||
const fields = collectSplitFields();
|
||||
renderAutoPolicy({
|
||||
mode: fields.mode,
|
||||
max_chunk_size: fields.max_chunk_size,
|
||||
child_max_size: fields.child_max_size,
|
||||
overlap: fields.overlap,
|
||||
pdf_chunk_strategy: mode === "by_row" ? null : undefined,
|
||||
chunk_strategy: mode === "parent_child" ? "parent_child_delimiter" : undefined,
|
||||
});
|
||||
}
|
||||
|
||||
function renderAutoPolicy(config) {
|
||||
if (!els.autoPolicyGrid) return;
|
||||
const modeLabel = {
|
||||
default: "结构感知",
|
||||
delimiter: "标识符",
|
||||
parent_child: "父子标识符",
|
||||
by_row: "按行",
|
||||
}[config?.mode] || "待上传后判断";
|
||||
const strategyLabel = {
|
||||
pdf_feature_step_screenshot: "功能步骤 + 截图",
|
||||
pdf_outline_report: "章节报告(标题层级)",
|
||||
heading_hierarchy: "标题层级优先",
|
||||
heading_layout_multimodal: "标题布局多模态",
|
||||
parent_child_delimiter: "父子标识符",
|
||||
}[config?.pdf_chunk_strategy || config?.chunk_strategy]
|
||||
|| (config?.mode === "by_row" ? "表格按行"
|
||||
: (config?.mode === "delimiter" ? "通用标识符"
|
||||
: (config?.mode === "parent_child" ? "父子标识符" : "自动判断")));
|
||||
const maxSize = config?.max_chunk_size != null ? `${config.max_chunk_size} 字符` : "自动";
|
||||
const overlap = config?.overlap != null ? `${config.overlap} 字符` : "自动";
|
||||
const childSize =
|
||||
config?.child_max_size != null ? `${config.child_max_size} 字符` : null;
|
||||
|
||||
els.autoPolicyGrid.innerHTML = `
|
||||
<div><dt>模式</dt><dd>${escapeHtml(modeLabel)}</dd></div>
|
||||
<div><dt>长度</dt><dd>${escapeHtml(maxSize)}</dd></div>
|
||||
<div><dt>重叠</dt><dd>${escapeHtml(overlap)}</dd></div>
|
||||
<div><dt>策略</dt><dd>${escapeHtml(strategyLabel)}</dd></div>
|
||||
${childSize ? `<div><dt>子级长度</dt><dd>${escapeHtml(childSize)}</dd></div>` : ""}
|
||||
`;
|
||||
}
|
||||
|
||||
function toAssetUrl(path, docId) {
|
||||
const raw = (path || "").trim();
|
||||
if (!raw || raw.startsWith("http://") || raw.startsWith("https://") || raw.startsWith("data:")) {
|
||||
return raw;
|
||||
}
|
||||
if (raw.startsWith("/assets/")) return apiUrl(raw);
|
||||
if (raw.startsWith("assets/")) return apiUrl(`/${raw}`);
|
||||
const name = raw.split(/[/\\]/).pop();
|
||||
return apiUrl(`/assets/${docId}/${name}`);
|
||||
}
|
||||
|
||||
function fixAssetPaths(markdown, docId) {
|
||||
if (!markdown) return "";
|
||||
return markdown.replace(/!\[(.*?)\]\(([^)]+)\)/g, (_, alt, path) => `})`);
|
||||
}
|
||||
|
||||
function rewritePreviewImages(container, docId) {
|
||||
container.querySelectorAll("img").forEach((img) => {
|
||||
const src = img.getAttribute("src");
|
||||
if (src) img.src = toAssetUrl(src, docId);
|
||||
});
|
||||
}
|
||||
|
||||
function formatBbox(bbox) {
|
||||
if (!Array.isArray(bbox) || bbox.length < 4) return "";
|
||||
return bbox.map((v) => Number(v).toFixed(0)).join(", ");
|
||||
}
|
||||
|
||||
function renderBlockItem(block, docId) {
|
||||
const order = block.order_index != null ? `data-order="${block.order_index}"` : "";
|
||||
const page = block.page != null ? `data-page="${block.page}"` : "";
|
||||
const bbox = formatBbox(block.bbox);
|
||||
const metaBadge = [block.page != null ? `p${block.page}` : "", bbox ? `[${bbox}]` : ""]
|
||||
.filter(Boolean)
|
||||
.join(" · ");
|
||||
|
||||
if (block.type === "image") {
|
||||
const src = toAssetUrl(block.image_path, docId);
|
||||
const alt = block.text || block.image_id || "image";
|
||||
let html = `<figure class="chunk-block chunk-block-image" ${order} ${page}>`;
|
||||
if (block.bound_heading || block.nearest_heading) {
|
||||
html += `<div class="block-context">${escapeHtml(block.bound_heading || block.nearest_heading)}</div>`;
|
||||
}
|
||||
html += `<img src="${escapeHtml(src)}" alt="${escapeHtml(alt)}" loading="lazy" />`;
|
||||
if (block.ocr_text) {
|
||||
html += `<figcaption class="ocr-caption">*[OCR]* ${escapeHtml(block.ocr_text)}</figcaption>`;
|
||||
}
|
||||
if (metaBadge) html += `<div class="block-meta">${escapeHtml(metaBadge)}</div>`;
|
||||
html += "</figure>";
|
||||
return html;
|
||||
}
|
||||
|
||||
if (block.type === "heading") {
|
||||
const level = Math.min(Math.max(block.level || 2, 1), 6);
|
||||
return `<h${level} class="chunk-block chunk-block-heading" ${order} ${page}>${escapeHtml(block.text || "")}</h${level}>`;
|
||||
}
|
||||
|
||||
if (block.type === "table") {
|
||||
const title = block.table_title || block.nearest_heading || "";
|
||||
const imgPath = block.image_path || block.crop_path;
|
||||
let html = `<div class="chunk-block chunk-block-table" ${order} ${page}>`;
|
||||
if (title) html += `<div class="block-context">${escapeHtml(title)}</div>`;
|
||||
if (imgPath) {
|
||||
const src = toAssetUrl(imgPath, docId);
|
||||
html += `<figure class="table-screenshot"><img src="${escapeHtml(src)}" alt="${escapeHtml(title || "table")}" loading="lazy" /></figure>`;
|
||||
}
|
||||
html += `<div class="table-markdown">${renderMarkdown(block.markdown || block.text || "", docId)}</div>`;
|
||||
if (block.ocr_text) {
|
||||
html += `<div class="ocr-caption">*[表格 OCR]* ${escapeHtml(block.ocr_text)}</div>`;
|
||||
}
|
||||
if (block.footnotes) {
|
||||
html += `<div class="table-footnote">${escapeHtml(block.footnotes)}</div>`;
|
||||
}
|
||||
if (metaBadge) html += `<div class="block-meta">${escapeHtml(metaBadge)}</div>`;
|
||||
html += "</div>";
|
||||
return html;
|
||||
}
|
||||
|
||||
const inner = block.text ? `<p>${escapeHtml(block.text)}</p>` : "";
|
||||
return `<div class="chunk-block chunk-block-paragraph" ${order} ${page}>${inner}${metaBadge ? `<div class="block-meta">${escapeHtml(metaBadge)}</div>` : ""}</div>`;
|
||||
}
|
||||
|
||||
function renderChunkContent(chunk, docId) {
|
||||
const blocks = chunk.meta?.blocks;
|
||||
if (Array.isArray(blocks) && blocks.length > 0) {
|
||||
const sorted = [...blocks].sort((a, b) => {
|
||||
const ao = a.order_index ?? Number.MAX_SAFE_INTEGER;
|
||||
const bo = b.order_index ?? Number.MAX_SAFE_INTEGER;
|
||||
return ao - bo;
|
||||
});
|
||||
return `<div class="chunk-blocks">${sorted.map((b) => renderBlockItem(b, docId)).join("")}</div>`;
|
||||
}
|
||||
return renderMarkdown(chunk.content, docId);
|
||||
}
|
||||
|
||||
function renderMarkdown(markdown, docId) {
|
||||
const fixed = fixAssetPaths(markdown, docId);
|
||||
if (typeof marked !== "undefined") {
|
||||
try {
|
||||
if (typeof marked.use === "function") {
|
||||
marked.use({ breaks: true, gfm: true });
|
||||
} else if (typeof marked.setOptions === "function") {
|
||||
marked.setOptions({ breaks: true, gfm: true });
|
||||
}
|
||||
const html = marked.parse(fixed);
|
||||
return typeof html === "string" ? html : String(html);
|
||||
} catch (err) {
|
||||
console.error("Markdown render failed:", err);
|
||||
return `<pre>${escapeHtml(fixed)}</pre>`;
|
||||
}
|
||||
}
|
||||
return `<pre>${escapeHtml(fixed)}</pre>`;
|
||||
}
|
||||
|
||||
function escapeHtml(str) {
|
||||
return str
|
||||
.replace(/&/g, "&")
|
||||
.replace(/</g, "<")
|
||||
.replace(/>/g, ">");
|
||||
}
|
||||
|
||||
function uniqueTypes(types) {
|
||||
return [...new Set(types)];
|
||||
}
|
||||
|
||||
function typeTagClass(type) {
|
||||
if (type === "heading") return "type-tag type-tag-heading";
|
||||
if (type === "image") return "type-tag type-tag-image";
|
||||
if (type === "table") return "type-tag type-tag-table";
|
||||
return "type-tag";
|
||||
}
|
||||
|
||||
function renderChunkList(result) {
|
||||
els.chunkList.innerHTML = "";
|
||||
result.chunks.forEach((chunk, i) => {
|
||||
const btn = document.createElement("button");
|
||||
btn.type = "button";
|
||||
btn.className = `chunk-card${i === state.selectedIndex ? " active" : ""}`;
|
||||
btn.setAttribute("role", "option");
|
||||
btn.setAttribute("aria-selected", i === state.selectedIndex ? "true" : "false");
|
||||
btn.dataset.index = String(i);
|
||||
|
||||
const types = uniqueTypes(chunk.block_types);
|
||||
const heading = chunk.meta?.heading || chunk.meta?.nearest_heading || chunk.meta?.parent_heading;
|
||||
const pageHint = chunk.meta?.page ? `p${chunk.meta.page}` : chunk.meta?.pages?.length ? `p${chunk.meta.pages.join(",")}` : "";
|
||||
const imageCount = chunk.meta?.images?.length || chunk.block_types.filter((t) => t === "image").length;
|
||||
const tableCount = chunk.meta?.tables?.length || chunk.block_types.filter((t) => t === "table").length;
|
||||
const parentRef = chunk.meta?.parent_chunk_id != null ? ` · 父切片 ${chunk.meta.parent_chunk_id + 1}` : "";
|
||||
const subBadge = chunk.meta?.is_sub_chunk ? '<span class="type-tag type-tag-heading">子切片</span>' : "";
|
||||
const parentBadge = chunk.meta?.is_section_parent ? '<span class="type-tag">完整节</span>' : "";
|
||||
const previewOnlyBadge = chunk.meta?.retrieval === false ? '<span class="type-tag type-tag-preview-only">仅展示</span>' : "";
|
||||
const snippet = chunk.content.replace(/!\[.*?\]\([^)]+\)/g, "[图片]").slice(0, 160);
|
||||
|
||||
btn.innerHTML = `
|
||||
<div class="chunk-card-header">
|
||||
<span class="chunk-index">切片 ${chunk.index + 1}</span>
|
||||
<span class="chunk-meta">${chunk.char_count} 字符${pageHint ? ` · ${pageHint}` : ""}${imageCount ? ` · ${imageCount} 图` : ""}${tableCount ? ` · ${tableCount} 表` : ""}${parentRef}</span>
|
||||
</div>
|
||||
<div class="chunk-types">
|
||||
${subBadge}${parentBadge}${previewOnlyBadge}${types.map((t) => `<span class="${typeTagClass(t)}">${t}</span>`).join("")}
|
||||
</div>
|
||||
${heading ? `<div class="chunk-snippet" style="-webkit-line-clamp:1;font-weight:500;color:var(--color-text)">${escapeHtml(heading)}</div>` : ""}
|
||||
<div class="chunk-snippet">${escapeHtml(snippet)}</div>
|
||||
`;
|
||||
|
||||
btn.addEventListener("click", () => selectChunk(i));
|
||||
els.chunkList.appendChild(btn);
|
||||
});
|
||||
}
|
||||
|
||||
function selectChunk(index) {
|
||||
if (!state.result) return;
|
||||
state.selectedIndex = index;
|
||||
const chunk = state.result.chunks[index];
|
||||
const docId = state.result.doc_id;
|
||||
|
||||
$$(".chunk-card").forEach((el, i) => {
|
||||
el.classList.toggle("active", i === index);
|
||||
el.setAttribute("aria-selected", i === index ? "true" : "false");
|
||||
});
|
||||
|
||||
els.selectedChunkTag.textContent = `切片 ${chunk.index + 1} · ${chunk.char_count} 字符${chunk.meta?.parent_chunk_id != null ? ` · 父切片 ${chunk.meta.parent_chunk_id + 1}` : ""}`;
|
||||
els.chunkPreview.innerHTML = renderChunkContent(chunk, docId);
|
||||
rewritePreviewImages(els.chunkPreview, docId);
|
||||
}
|
||||
|
||||
async function renderConvertedWordPreview(file, docId) {
|
||||
if (!docId) return false;
|
||||
try {
|
||||
const res = await fetch(apiUrl(`/api/results/${docId}/preview`));
|
||||
if (!res.ok) return false;
|
||||
const blob = await res.blob();
|
||||
if (state.objectUrl) URL.revokeObjectURL(state.objectUrl);
|
||||
state.objectUrl = URL.createObjectURL(blob);
|
||||
els.originalPreview.innerHTML =
|
||||
`<iframe class="original-pdf" src="${state.objectUrl}" title="${escapeHtml(file.name)} PDF 原文预览"></iframe>`;
|
||||
return true;
|
||||
} catch (err) {
|
||||
console.warn("Word PDF 预览加载失败:", err);
|
||||
return false;
|
||||
}
|
||||
}
|
||||
|
||||
async function renderOriginalPreview(file, docId = null) {
|
||||
els.originalPreview.innerHTML = '<p class="placeholder">原文加载中…</p>';
|
||||
els.originalTag.textContent = file.name;
|
||||
|
||||
const ext = file.name.split(".").pop()?.toLowerCase() || "";
|
||||
|
||||
if (ext === "pdf") {
|
||||
state.objectUrl = URL.createObjectURL(file);
|
||||
els.originalPreview.innerHTML = `<iframe class="original-pdf" src="${state.objectUrl}" title="PDF 原文预览"></iframe>`;
|
||||
return;
|
||||
}
|
||||
|
||||
if (["doc", "docx"].includes(ext) && await renderConvertedWordPreview(file, docId)) {
|
||||
return;
|
||||
}
|
||||
|
||||
if (ext === "docx" && typeof mammoth !== "undefined") {
|
||||
const buffer = await file.arrayBuffer();
|
||||
const { value } = await mammoth.convertToHtml({ arrayBuffer: buffer });
|
||||
els.originalPreview.innerHTML = `<div class="original-docx">${value}</div>`;
|
||||
return;
|
||||
}
|
||||
|
||||
if (["doc", "docx"].includes(ext)) {
|
||||
els.originalPreview.innerHTML =
|
||||
'<p class="placeholder">Word 原文将在切分完成后以 PDF 方式显示。</p>';
|
||||
return;
|
||||
}
|
||||
|
||||
if (["jpg", "jpeg", "png", "bmp", "gif"].includes(ext)) {
|
||||
state.objectUrl = URL.createObjectURL(file);
|
||||
els.originalPreview.innerHTML = `<img class="original-image" src="${state.objectUrl}" alt="上传的图片" />`;
|
||||
return;
|
||||
}
|
||||
|
||||
if (["txt", "md", "csv", "json", "xml", "log", "html", "htm"].includes(ext)) {
|
||||
const text = await file.text();
|
||||
els.originalPreview.innerHTML = `<pre class="original-text">${escapeHtml(text.slice(0, 50000))}${text.length > 50000 ? "\n\n… (已截断)" : ""}</pre>`;
|
||||
return;
|
||||
}
|
||||
|
||||
if (["ppt", "pptx", "ppsx"].includes(ext)) {
|
||||
els.originalPreview.innerHTML =
|
||||
`<p class="placeholder">演示文稿将先转为 PDF 再解析;原文预览暂不支持,请查看右侧切片结果。</p>`;
|
||||
return;
|
||||
}
|
||||
|
||||
els.originalPreview.innerHTML = `<p class="placeholder">该格式暂不支持原文预览,请查看右侧切片结果。</p>`;
|
||||
}
|
||||
|
||||
function showResult(result) {
|
||||
state.result = result;
|
||||
state.selectedIndex = 0;
|
||||
state.activeHistoryId = result.doc_id || null;
|
||||
highlightHistoryActive();
|
||||
|
||||
els.emptyState.classList.add("hidden");
|
||||
els.dualPane.classList.remove("hidden");
|
||||
els.apiPanel.classList.remove("hidden");
|
||||
els.recallPanel.classList.remove("hidden");
|
||||
els.statsSection.classList.remove("hidden");
|
||||
|
||||
els.statBlocks.textContent = result.block_count;
|
||||
els.statChunks.textContent = result.chunk_count;
|
||||
els.statMode.textContent = result.split_mode;
|
||||
els.statDocId.textContent = result.doc_id;
|
||||
els.chunkCountTag.textContent = `${result.chunk_count} 个切片`;
|
||||
renderAutoPolicy(result.split_config);
|
||||
|
||||
renderChunkList(result);
|
||||
selectChunk(0);
|
||||
setStatus("success", `切分完成 · ${result.chunk_count} 片`);
|
||||
}
|
||||
|
||||
function renderRecallResults(data) {
|
||||
els.recallHint.textContent = `候选 ${data.candidate_count} 个 · 返回 ${data.returned_count} 个 · ${data.elapsed_ms} ms`;
|
||||
if (!data.results.length) {
|
||||
els.recallResults.innerHTML = '<p class="placeholder">没有匹配的切片,请尝试更具体或更短的关键词。</p>';
|
||||
return;
|
||||
}
|
||||
els.recallResults.innerHTML = data.results.map((item) => `
|
||||
<button class="recall-result" type="button" data-chunk-index="${item.chunk_index}">
|
||||
<span class="recall-rank">#${item.rank}</span>
|
||||
<span class="recall-result-main">
|
||||
<strong>${escapeHtml(item.heading || `切片 ${item.chunk_index + 1}`)}</strong>
|
||||
<span>${escapeHtml(item.content.replace(/!\[.*?\]\([^)]+\)/g, "[图片]").slice(0, 180))}</span>
|
||||
</span>
|
||||
<span class="recall-score">${Number(item.score).toFixed(3)}</span>
|
||||
</button>
|
||||
`).join("");
|
||||
els.recallResults.querySelectorAll(".recall-result").forEach((button) => {
|
||||
button.addEventListener("click", () => {
|
||||
const chunkIndex = Number(button.dataset.chunkIndex);
|
||||
const position = state.result.chunks.findIndex((chunk) => chunk.index === chunkIndex);
|
||||
if (position >= 0) selectChunk(position);
|
||||
});
|
||||
});
|
||||
}
|
||||
|
||||
async function handleRecall(e) {
|
||||
e.preventDefault();
|
||||
if (!state.result) return;
|
||||
const request = {
|
||||
doc_id: state.result.doc_id,
|
||||
query: els.recallQuery.value.trim(),
|
||||
top_k: Number(els.recallTopK.value),
|
||||
};
|
||||
if (!request.query) return;
|
||||
|
||||
els.recallSubmit.disabled = true;
|
||||
els.recallHint.textContent = "正在召回…";
|
||||
els.apiPanel.classList.remove("hidden");
|
||||
els.apiRequest.textContent = JSON.stringify({ method: "POST", url: apiUrl("/api/recall"), body: request }, null, 2);
|
||||
try {
|
||||
const response = await fetch(apiUrl("/api/recall"), {
|
||||
method: "POST",
|
||||
headers: { "Content-Type": "application/json" },
|
||||
body: JSON.stringify(request),
|
||||
});
|
||||
const data = await response.json();
|
||||
if (!response.ok) throw new Error(data.detail || `HTTP ${response.status}`);
|
||||
els.apiResponse.textContent = JSON.stringify(data, null, 2);
|
||||
renderRecallResults(data);
|
||||
} catch (err) {
|
||||
els.recallHint.textContent = `召回失败:${err.message}`;
|
||||
els.apiResponse.textContent = JSON.stringify({ error: err.message }, null, 2);
|
||||
} finally {
|
||||
els.recallSubmit.disabled = false;
|
||||
}
|
||||
}
|
||||
|
||||
async function handleSubmit(e) {
|
||||
e.preventDefault();
|
||||
if (!state.file) {
|
||||
alert("请先在上方上传文档,再点击「开始切分」");
|
||||
els.dropzone?.focus();
|
||||
return;
|
||||
}
|
||||
|
||||
const mode = els.splitMode?.value || "default";
|
||||
if (mode === "delimiter") {
|
||||
const delimiter = unescapeDelimiter(els.delimiter?.value?.trim());
|
||||
if (!delimiter) {
|
||||
alert("通用标识符切分需要填写标识符");
|
||||
els.delimiter?.focus();
|
||||
return;
|
||||
}
|
||||
}
|
||||
if (mode === "parent_child") {
|
||||
const parentDelimiter = unescapeDelimiter(els.parentDelimiter?.value?.trim());
|
||||
if (!parentDelimiter) {
|
||||
alert("父子标识符切分需要填写父级标识符");
|
||||
els.parentDelimiter?.focus();
|
||||
return;
|
||||
}
|
||||
const parentMax = Number(els.parentMaxSize?.value || 2000);
|
||||
const childMax = Number(els.childMaxSize?.value || 512);
|
||||
if (childMax > parentMax) {
|
||||
alert("子级最大长度不能超过父级最大长度");
|
||||
els.childMaxSize?.focus();
|
||||
return;
|
||||
}
|
||||
}
|
||||
|
||||
const btnLabel = els.submitBtn.querySelector(".btn-label");
|
||||
const spinner = els.submitBtn.querySelector(".btn-spinner");
|
||||
const setBusy = (busy) => {
|
||||
els.submitBtn.disabled = busy ? true : !state.file;
|
||||
if (btnLabel) btnLabel.textContent = busy ? "切分中…" : "开始切分";
|
||||
else els.submitBtn.textContent = busy ? "切分中…" : "开始切分";
|
||||
if (spinner) spinner.classList.toggle("hidden", !busy);
|
||||
};
|
||||
|
||||
setBusy(true);
|
||||
setStatus("loading", "正在切分…");
|
||||
if (els.apiRequest) {
|
||||
els.apiRequest.textContent = JSON.stringify(buildRequestPreview(), null, 2);
|
||||
}
|
||||
els.apiPanel?.classList.remove("hidden");
|
||||
|
||||
const controller = new AbortController();
|
||||
const abortTimer = setTimeout(() => controller.abort(), 10 * 60 * 1000);
|
||||
|
||||
try {
|
||||
// Kick off API first; do not block chunking on original preview.
|
||||
const previewPromise = renderOriginalPreview(state.file).catch((err) => {
|
||||
console.warn("原文预览失败:", err);
|
||||
});
|
||||
|
||||
const fd = buildFormData();
|
||||
const res = await fetch(apiUrl("/api/chunk"), {
|
||||
method: "POST",
|
||||
body: fd,
|
||||
signal: controller.signal,
|
||||
});
|
||||
const data = await res.json();
|
||||
|
||||
if (!res.ok) {
|
||||
const detail = Array.isArray(data.detail)
|
||||
? data.detail.map((d) => d.msg || JSON.stringify(d)).join("; ")
|
||||
: data.detail;
|
||||
throw new Error(detail || `HTTP ${res.status}`);
|
||||
}
|
||||
|
||||
await previewPromise;
|
||||
if (els.apiResponse) els.apiResponse.textContent = JSON.stringify(data, null, 2);
|
||||
showResult(data);
|
||||
await renderOriginalPreview(state.file, data.doc_id);
|
||||
refreshHistory();
|
||||
} catch (err) {
|
||||
console.error("chunk submit failed:", err);
|
||||
const message =
|
||||
err?.name === "AbortError"
|
||||
? "请求超时(超过 10 分钟)。后端可能卡在 MinerU/Office 转换,请重试或换较小文件。"
|
||||
: err.message || String(err);
|
||||
setStatus("error", "切分失败");
|
||||
if (els.apiResponse) els.apiResponse.textContent = JSON.stringify({ error: message }, null, 2);
|
||||
alert(`切分失败:${message}`);
|
||||
} finally {
|
||||
clearTimeout(abortTimer);
|
||||
setBusy(false);
|
||||
}
|
||||
}
|
||||
|
||||
function initDropzone() {
|
||||
els.dropzone.addEventListener("click", () => els.fileInput.click());
|
||||
els.dropzone.addEventListener("keydown", (e) => {
|
||||
if (e.key === "Enter" || e.key === " ") {
|
||||
e.preventDefault();
|
||||
els.fileInput.click();
|
||||
}
|
||||
});
|
||||
|
||||
els.fileInput.addEventListener("change", () => {
|
||||
if (els.fileInput.files?.[0]) setFile(els.fileInput.files[0]);
|
||||
});
|
||||
|
||||
["dragenter", "dragover"].forEach((ev) => {
|
||||
els.dropzone.addEventListener(ev, (e) => {
|
||||
e.preventDefault();
|
||||
els.dropzone.classList.add("dragover");
|
||||
});
|
||||
});
|
||||
["dragleave", "drop"].forEach((ev) => {
|
||||
els.dropzone.addEventListener(ev, (e) => {
|
||||
e.preventDefault();
|
||||
els.dropzone.classList.remove("dragover");
|
||||
});
|
||||
});
|
||||
els.dropzone.addEventListener("drop", (e) => {
|
||||
const file = e.dataTransfer?.files?.[0];
|
||||
if (file) setFile(file);
|
||||
});
|
||||
}
|
||||
|
||||
els.configForm.addEventListener("submit", handleSubmit);
|
||||
els.recallForm.addEventListener("submit", handleRecall);
|
||||
els.historyRefreshBtn?.addEventListener("click", refreshHistory);
|
||||
els.splitMode?.addEventListener("change", syncModeOptions);
|
||||
[
|
||||
els.maxChunkSize,
|
||||
els.overlap,
|
||||
els.delimiter,
|
||||
els.delimiterMaxSize,
|
||||
els.delimiterOverlap,
|
||||
els.parentDelimiter,
|
||||
els.childDelimiter,
|
||||
els.parentMaxSize,
|
||||
els.childMaxSize,
|
||||
els.parentChildOverlap,
|
||||
els.headerRowStart,
|
||||
els.headerRowEnd,
|
||||
els.startRow,
|
||||
els.rowsPerChunk,
|
||||
].forEach((el) => el?.addEventListener("change", syncModeOptions));
|
||||
syncModeOptions();
|
||||
initDropzone();
|
||||
refreshHistory();
|
||||
@@ -0,0 +1,39 @@
|
||||
"""Serve RAG-cut frontend static files (development mode).
|
||||
|
||||
Requires the API backend to be running separately:
|
||||
python backend/run.py
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import argparse
|
||||
import http.server
|
||||
import socketserver
|
||||
from pathlib import Path
|
||||
|
||||
FRONTEND_DIR = Path(__file__).resolve().parent
|
||||
DEFAULT_API = "http://127.0.0.1:8000"
|
||||
|
||||
|
||||
class FrontendHandler(http.server.SimpleHTTPRequestHandler):
|
||||
def __init__(self, *args, **kwargs):
|
||||
super().__init__(*args, directory=str(FRONTEND_DIR), **kwargs)
|
||||
|
||||
|
||||
def main() -> None:
|
||||
parser = argparse.ArgumentParser(description="Start RAG-cut frontend dev server")
|
||||
parser.add_argument("--host", default="127.0.0.1", help="Bind host (default: 127.0.0.1)")
|
||||
parser.add_argument("--port", type=int, default=5173, help="Bind port (default: 5173)")
|
||||
args = parser.parse_args()
|
||||
|
||||
url = f"http://{args.host}:{args.port}"
|
||||
socketserver.TCPServer.allow_reuse_address = True
|
||||
with socketserver.TCPServer((args.host, args.port), FrontendHandler) as httpd:
|
||||
print(f"Frontend: {url}")
|
||||
print(f"API: {DEFAULT_API} (start with: python backend/run.py)")
|
||||
print("Press Ctrl+C to stop.")
|
||||
httpd.serve_forever()
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
main()
|
||||
@@ -0,0 +1,7 @@
|
||||
fastapi>=0.115.0
|
||||
uvicorn>=0.30.0
|
||||
pydantic>=2.0
|
||||
PyMuPDF>=1.24.0
|
||||
pdfplumber>=0.11.0
|
||||
openpyxl>=3.1.0
|
||||
mineru[all]
|
||||
@@ -0,0 +1,72 @@
|
||||
#!/usr/bin/env python3
|
||||
"""CLI to chunk documents and print/save results."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import argparse
|
||||
import json
|
||||
import sys
|
||||
from pathlib import Path
|
||||
|
||||
sys.path.insert(0, str(Path(__file__).resolve().parent.parent / "backend"))
|
||||
|
||||
from rag_cut.models import SplitConfig, SplitMode
|
||||
from rag_cut.pipeline import chunk_document
|
||||
|
||||
|
||||
def main() -> None:
|
||||
parser = argparse.ArgumentParser(description="RAG-cut document chunking CLI")
|
||||
parser.add_argument("file", type=Path, help="Path to document")
|
||||
parser.add_argument(
|
||||
"--mode",
|
||||
choices=[m.value for m in SplitMode],
|
||||
default="default",
|
||||
help="Split mode",
|
||||
)
|
||||
parser.add_argument("--delimiter", default=None, help="Delimiter for delimiter mode")
|
||||
parser.add_argument("--parent-delimiter", default=None, help="Parent delimiter for parent_child mode")
|
||||
parser.add_argument("--child-delimiter", default=None, help="Child delimiter for parent_child mode")
|
||||
parser.add_argument("--max-chunk-size", type=int, default=1500, help="Parent/primary max chunk size")
|
||||
parser.add_argument("--child-max-size", type=int, default=512, help="Child max size for parent_child mode")
|
||||
parser.add_argument("--overlap", type=int, default=150)
|
||||
parser.add_argument("--header-row-start", type=int, default=1)
|
||||
parser.add_argument("--header-row-end", type=int, default=1)
|
||||
parser.add_argument("--start-row", type=int, default=2)
|
||||
parser.add_argument("--rows-per-chunk", type=int, default=1)
|
||||
parser.add_argument("-o", "--output", type=Path, default=None, help="Save JSON result")
|
||||
parser.add_argument("--preview", type=int, default=3, help="Print first N chunks")
|
||||
args = parser.parse_args()
|
||||
|
||||
config = SplitConfig(
|
||||
mode=SplitMode(args.mode),
|
||||
delimiter=args.delimiter,
|
||||
parent_delimiter=args.parent_delimiter,
|
||||
child_delimiter=args.child_delimiter,
|
||||
max_chunk_size=args.max_chunk_size,
|
||||
child_max_size=args.child_max_size,
|
||||
overlap=args.overlap,
|
||||
header_row_start=args.header_row_start,
|
||||
header_row_end=args.header_row_end,
|
||||
start_row=args.start_row,
|
||||
rows_per_chunk=args.rows_per_chunk,
|
||||
)
|
||||
|
||||
result = chunk_document(args.file, config=config)
|
||||
print(f"File: {result.filename}")
|
||||
print(f"Doc ID: {result.doc_id}")
|
||||
print(f"Blocks: {result.block_count} -> Chunks: {result.chunk_count}")
|
||||
print(f"Mode: {result.split_mode.value}")
|
||||
print("-" * 60)
|
||||
|
||||
for chunk in result.chunks[: args.preview]:
|
||||
print(f"\n[Chunk {chunk.index}] ({chunk.char_count} chars) types={chunk.block_types}")
|
||||
preview = chunk.content[:500]
|
||||
print(preview + ("..." if len(chunk.content) > 500 else ""))
|
||||
|
||||
if args.output:
|
||||
args.output.write_text(result.model_dump_json(indent=2), encoding="utf-8")
|
||||
print(f"\nSaved full result to {args.output}")
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
main()
|
||||
@@ -0,0 +1,38 @@
|
||||
"""Extract text and page summaries from requirements PDF."""
|
||||
from pathlib import Path
|
||||
|
||||
import fitz
|
||||
|
||||
PDF = Path(__file__).resolve().parent.parent / "docx" / "自研搭建AI助手知识库.pdf"
|
||||
OUT = Path(__file__).resolve().parent.parent / "docx" / "extracted_requirements.txt"
|
||||
IMG_DIR = Path(__file__).resolve().parent.parent / "docx" / "pdf_pages"
|
||||
|
||||
|
||||
def main() -> None:
|
||||
IMG_DIR.mkdir(parents=True, exist_ok=True)
|
||||
doc = fitz.open(PDF)
|
||||
lines = [f"Pages: {len(doc)}", f"Path: {PDF}", ""]
|
||||
|
||||
for i, page in enumerate(doc):
|
||||
text = page.get_text("text").strip()
|
||||
imgs = page.get_images()
|
||||
blocks = page.get_text("dict")["blocks"]
|
||||
text_blocks = sum(1 for b in blocks if b.get("type") == 0)
|
||||
img_path = IMG_DIR / f"page_{i + 1:02d}.png"
|
||||
pix = page.get_pixmap(matrix=fitz.Matrix(2, 2))
|
||||
pix.save(str(img_path))
|
||||
|
||||
lines.append(f"{'=' * 60}")
|
||||
lines.append(f"PAGE {i + 1} | images={len(imgs)} text_blocks={text_blocks}")
|
||||
lines.append(f"{'=' * 60}")
|
||||
lines.append(text if text else "[no extractable text - see pdf_pages/]")
|
||||
lines.append("")
|
||||
|
||||
doc.close()
|
||||
OUT.write_text("\n".join(lines), encoding="utf-8")
|
||||
print(f"Wrote {OUT}")
|
||||
print(f"Rendered {len(list(IMG_DIR.glob('*.png')))} page images to {IMG_DIR}")
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
main()
|
||||
@@ -0,0 +1,14 @@
|
||||
$ErrorActionPreference = 'Stop'
|
||||
$out = 'C:\Users\24019\Desktop\RAG-cut\data\test_sample.pptx'
|
||||
$pp = New-Object -ComObject PowerPoint.Application
|
||||
try {
|
||||
$pres = $pp.Presentations.Add()
|
||||
$slide = $pres.Slides.Add(1, 1)
|
||||
$slide.Shapes.Title.TextFrame.TextRange.Text = 'RAG-cut Test Slide'
|
||||
$slide.Shapes.Item(2).TextFrame.TextRange.Text = 'Body text for chunking test.'
|
||||
$pres.SaveAs($out)
|
||||
$pres.Close()
|
||||
} finally {
|
||||
$pp.Quit()
|
||||
}
|
||||
Write-Output "Saved $out"
|
||||
@@ -0,0 +1,59 @@
|
||||
"""Quick probe of sample documents for chunking strategy planning."""
|
||||
import re
|
||||
import zipfile
|
||||
from pathlib import Path
|
||||
|
||||
DATA = Path(__file__).resolve().parent.parent / "data"
|
||||
|
||||
|
||||
def probe_docx(p: Path) -> None:
|
||||
with zipfile.ZipFile(p) as z:
|
||||
media = [n for n in z.namelist() if n.startswith("word/media/")]
|
||||
xml = z.read("word/document.xml").decode("utf-8", errors="ignore")
|
||||
headings = len(re.findall(r'w:pStyle w:val="Heading', xml))
|
||||
tables = xml.count("<w:tbl")
|
||||
drawings = xml.count("<w:drawing") + xml.count("<w:pict")
|
||||
print(f" media: {len(media)}, tables: {tables}, drawings: {drawings}, heading_styles: {headings}")
|
||||
|
||||
|
||||
def probe_pdf(p: Path) -> None:
|
||||
import fitz
|
||||
|
||||
doc = fitz.open(p)
|
||||
imgs = sum(len(doc[i].get_images()) for i in range(len(doc)))
|
||||
text_len = sum(len(doc[i].get_text()) for i in range(len(doc)))
|
||||
print(f" pages: {len(doc)}, embedded_images: {imgs}, text_chars: {text_len}")
|
||||
doc.close()
|
||||
|
||||
|
||||
def probe_xlsx(p: Path) -> None:
|
||||
import openpyxl
|
||||
|
||||
wb = openpyxl.load_workbook(p, read_only=True, data_only=True)
|
||||
print(f" sheets: {len(wb.sheetnames)} -> {wb.sheetnames[:5]}")
|
||||
for sn in wb.sheetnames[:2]:
|
||||
ws = wb[sn]
|
||||
print(f" {sn}: rows={ws.max_row}, cols={ws.max_column}")
|
||||
wb.close()
|
||||
|
||||
|
||||
def main() -> None:
|
||||
for p in sorted(DATA.iterdir()):
|
||||
if not p.is_file():
|
||||
continue
|
||||
print(f"=== {p.name} ({p.stat().st_size} bytes) ===")
|
||||
ext = p.suffix.lower()
|
||||
try:
|
||||
if ext == ".docx":
|
||||
probe_docx(p)
|
||||
elif ext == ".pdf":
|
||||
probe_pdf(p)
|
||||
elif ext in (".xlsx", ".xls"):
|
||||
probe_xlsx(p)
|
||||
except Exception as e:
|
||||
print(f" ERROR: {e}")
|
||||
print()
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
main()
|
||||
@@ -0,0 +1,42 @@
|
||||
"""Run chunking on all sample files in data/."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import sys
|
||||
from pathlib import Path
|
||||
|
||||
sys.path.insert(0, str(Path(__file__).resolve().parent.parent / "backend"))
|
||||
|
||||
from rag_cut.models import SplitConfig, SplitMode
|
||||
from rag_cut.pipeline import chunk_document
|
||||
|
||||
DATA = Path(__file__).resolve().parent.parent / "data"
|
||||
OUT = Path(__file__).resolve().parent.parent / "storage"
|
||||
|
||||
|
||||
def main() -> None:
|
||||
for path in sorted(DATA.iterdir()):
|
||||
if not path.is_file():
|
||||
continue
|
||||
ext = path.suffix.lower()
|
||||
if ext == ".xlsx":
|
||||
config = SplitConfig(mode=SplitMode.BY_ROW, rows_per_chunk=5)
|
||||
else:
|
||||
config = SplitConfig(mode=SplitMode.DEFAULT)
|
||||
|
||||
print(f"\n{'=' * 60}\n{path.name} ({ext})")
|
||||
result = chunk_document(path, config=config)
|
||||
print(f"blocks={result.block_count} chunks={result.chunk_count} mode={result.split_mode.value}")
|
||||
|
||||
out_file = OUT / f"{path.stem}_chunks.json"
|
||||
out_file.write_text(result.model_dump_json(indent=2), encoding="utf-8")
|
||||
print(f"saved -> {out_file.name}")
|
||||
|
||||
if result.chunks:
|
||||
c0 = result.chunks[0]
|
||||
print(f"chunk[0] types={c0.block_types} chars={c0.char_count}")
|
||||
print(c0.content[:300].replace("\n", " ") + "...")
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
main()
|
||||
Binary file not shown.
Binary file not shown.
Binary file not shown.
Binary file not shown.
Binary file not shown.
Binary file not shown.
Binary file not shown.
Reference in New Issue
Block a user